### High-volume classification with Mistral NeMo Balancing model parameters against throughput costs is essential for efficient classification, ensuring that simple labeling tasks don't consume your entire research budget. The Ministral 3 3B model costs **$0.10 per million tokens** according to Vantaige, making it an exceptionally low-cost option for high-volume text processing, allowing developers to scale operations without proportional spikes in overhead, which means even startups can deploy complex language tasks at a fraction of the traditional budget. This price permits massive scale without hitting the six-figure annual spends common with larger models. $0.15 per million tokens is the price you will pay if you step up to the Ministral 3 8B, according to [Aicost](https://aicost.ai/ai-cost-guides/pricing/mistral). You'll pay **a 50% premium for the extra reasoning** capabilities required for nuanced sentiment analysis. For vision-integrated tasks, the Ministral 3 14B sits at $0.20 per million tokens, doubling the entry-level cost to accommodate multimodal inputs, meaning that adding visual intelligence directly impacts the unit economics of every request. You must budget for higher overhead when deploying image-heavy workflows. ### Complex reasoning tasks with Mistral Large 4 Multi-step logic requires significant compute, and the price per token for flagship models reflects this enterprise-grade reasoning requirement. The total cost to process 1M tokens (50/50 input-output split) is $0.40 for Mistral Small 4, $4.00 for Mistral Large 4, and $4.75 for Mistral Medium 3.5, illustrating a wide spectrum of pricing tiers based on model sophistication. A 20x price gap exists between the specialized and legacy tiers, so organizations must carefully justify the premium for newer infrastructure. This massive variance forces you to treat model selection as a financial constraint rather than a technical preference. Consequently, you must optimize the execution layer to route only the most difficult queries to the top-tier models. ### Long-context window pricing for Mistral models To prevent linear scaling of costs from breaking your project budget, you must use batch processing aggressively when managing long-context windows. Utilizing the batch API for Mistral Large 4 results in a 1/2 ratio for output expenses. This effectively halves the cost as reported by [TechCompare](https://www.techcompare.app/llm-pricing-calculator/mistral-large-3-pricing).  Large-scale document summarization becomes economically viable as a result. Without this 50% reduction, high-context agents would quickly exceed the cost-per-run limits of standard SaaS subscriptions, rendering complex automated tasks financially unsustainable, as the current pricing models are not built to absorb such high token consumption. This makes batch scheduling the primary tool for maintaining your margin during heavy data ingestion phases. ## Hidden expenses beyond standard token consumption costs Structural overhead rather than simple per-token rates dictates the total cost of ownership for frontier models. While input and output prices are plummeting toward zero, the infrastructure required to maintain high-throughput access and specialized weights introduces fixed costs that can dwarf variable consumption. ### Mistral fine-tuning and dedicated hosting costs Training a specialized version of a model like Mistral Large 4 requires a capital outlay for the compute hours used during the optimization phase. The recurring expense lies in the dedicated hosting required to serve those custom weights. Dedicated hosting is often required for fine-tuned models, unlike base models that share infrastructure across all users. This means you'll pay for every hour the model is available to receive requests, regardless of whether the model generates a single token.  For low-volume applications, this idle time creates a massive effective markup on every request, shifting the financial burden from usage to availability. ### Mistral rate limits and concurrency tier costs Throughput restrictions gate high-performance models, forcing you to pay for higher tiers just to maintain operational stability. Anthropic segments access into Free, Pro, and Team tiers, where the Pro tier requires a $200 upfront annual commitment to unlock higher usage limits, effectively locking out casual users who cannot justify the initial lump-sum payment, thereby restricting premium access to those with significant capital, so individual hobbyists are forced to rely on the more restrictive free tier. 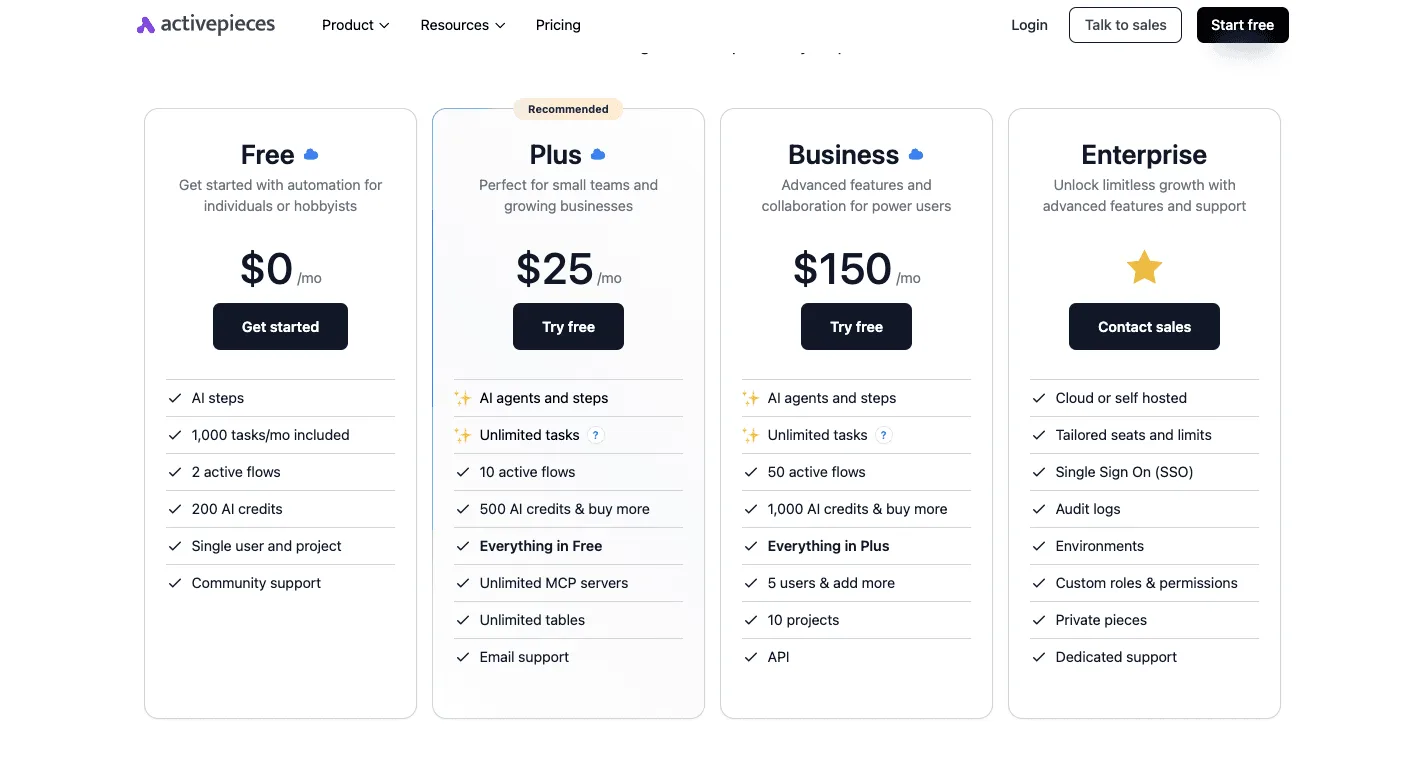 This upfront cost is a barrier to entry for scaling. You must commit to significant capital expenditure if your team outgrows the Free tier before you can process your next batch of data. These tiers act as a tax on concurrency, where the price of avoiding "429 Too Many Requests" errors is a fixed monthly platform fee. ### La Plateforme versus cloud marketplace pricing A "convenience tax" introduced by the choice of hosting environment alters the unit economics of every call. Deploying Mistral Small 4 through La Plateforme, Mistral’s native API, typically has the lowest direct cost, but migrating that same model to Azure or AWS often incurs a premium. Integrated billing and enterprise-grade security features like private networking are how cloud providers justify the higher price. Native APIs offer the lowest cost for you if you can manage your own data privacy layers. Cloud marketplaces trade higher per-token costs for reduced engineering effort in compliance and networking. ## Mistral price comparison against OpenAI and Anthropic Mistral’s tiered structure positions its models as the high-margin efficiency choice. It undercuts the input costs of established frontier models by as much as 83%, which means you can significantly reduce your operational overhead. This aggressive pricing pivot transforms model selection from a capability discussion into a line-item optimization exercise for your high-volume engineering team. ### Mistral Large 4 vs. GPT-4o and Claude 3.5 Sonnet $2.00 per 1M tokens is the baseline input cost for Mistral Large 4, so developers must account for this fixed expense when calculating the total budget for their integration projects. This allows you to process five times the volume of data for the same budget required by OpenAI, effectively quintupling the analytical reach of your existing capital. The gap is stark when compared to the $2.50 per 1M tokens charged for [OpenAI](https://aitokenusagecalculator.com/models/mistral-small-4/cost) GPT-4o and the $3.00 per 1M tokens for [Anthropic](https://aitokenusagecalculator.com/models/mistral-small-4/cost) [Claude](https://claude.com/pricing) 3.5 Sonnet, demonstrating that users opting for alternative providers are paying a significant premium. While OpenAI has a [Free plan](https://openai.com/chatgpt/pricing) at $0 per month for casual testing, enterprise-scale reasoning tasks gravitate toward these paid API tiers where Mistral’s lower overhead significantly reduces the cost of long-context retrieval. | Model | Input Cost per 1M Tokens | | :--- | :--- | | Mistral Large 4 | $2.00 | | OpenAI GPT-4o | $2.50 | | Anthropic Claude 3.5 Sonnet | $3.00 | This shift suggests that for general-purpose multimodal tasks, the "intelligence tax" is rapidly evaporating. ### Mistral Small vs. GPT-6 Luna and Haiku Mistral Small 4 enters the high-volume efficiency tier at [$0.20 per 1M tokens](https://aitokenusagecalculator.com/models/mistral-small-4/cost). It matches the price of OpenAI GPT-6 Luna exactly so that switching costs are purely technical rather than financial. For latency-sensitive routing, [Claude Haiku 5.5](https://docs.claude.com/en/docs/about-claude/models/overview) maintains a slight edge at $0.60 per 1M tokens, meaning it remains the cheapest option for basic classification. For users transitioning from consumer interfaces, the Go plan at $8 per month is a middle ground, providing a predictable monthly expense that avoids the sticker shock of enterprise-level billing, ensuring that budget forecasting remains straightforward for small teams, so financial planning becomes a low-friction task for growing businesses. For programmatic execution, these per-token micro-costs determine whether an agentic workflow is profitable at scale. ## Automating Mistral model selection to control costs Effective cost control requires routing every prompt to the cheapest model capable of completing the specific task. By treating intelligence as a variable expense, you prevent high-margin flagship models from wasting budget on basic formatting or classification duties. Linguistic complexity should dictate how you tier standard text processing to avoid overpaying for simple logic. Ministral 3 8B is the baseline for high-volume summarization. This ensures that basic data extraction doesn't trigger flagship rates. Intermediate reasoning is handled by Mistral Small 4 where context window efficiency is required. This means long documents are processed without the overhead of a massive parameter count. For mission-critical reasoning or multilingual nuance, Mistral Large 4 has the necessary depth. This justifies its higher cost only when lower tiers fail to produce a valid output. Domain-specific tasks require models optimized for structure rather than prose to reduce retry costs. Using Codestral for Python or SQL generation ensures higher first-pass accuracy, so you'll spend less time debugging hallucinated syntax.  Similarly, Mistral Embed or Codestral Embed should be used for vectorizing knowledge bases. These models are tuned for retrieval rather than generation, which lowers the computational cost per search query. Unexpected service interruptions during production runs can be prevented by managing API consumption across different tiers. The Mistral "Free" tier is restricted to non-commercial research, so you'll need to migrate to a paid tier before deploying any customer-facing features. Paid tiers include specific rate limits on concurrent requests. A high-concurrency agent will require a "Premier" tier subscription to avoid 429 errors during peak traffic. To initiate a batch audit of data stored in [Google Sheets](https://www.activepieces.com/pieces/google-sheets), set a "Every Week" schedule in [Activepieces](https://www.activepieces.com). MoneyGram and FundingSocieties run these types of complex automations in production where the execution layer is optimized for high-volume routing. By providing a unified environment that tracks AI usage via credits, the platform ensures that building a robust routing logic doesn't cost more than the simple workaround it replaced. To maintain full control over these routing costs, organizations can deploy the MIT-licensed core of Activepieces on their own infrastructure, ensuring that SSO, SCIM, and audit logs apply to every model call just as they do in the managed cloud. ## The Monday morning Mistral budget audit checklist A rigorous audit of your inference spend ensures that high-margin compute is reserved for reasoning rather than basic data plumbing. Because model performance is now a commodity, every dollar spent on a flagship model for a task that a smaller variant could handle is a direct hit to your operational efficiency. Use this sequence to align your Mistral consumption with the actual complexity of your production traffic: 1. Export usage CSV from La Plateforme, Mistral’s self-service API dashboard. 2. Identify top 3 token-consuming workflows. 3. Downgrade 'Small' tasks from 'Large' models. 4. Set hard monthly billing alerts. The delta between your theoretical budget and your actual execution costs is revealed by this audit. It highlights where over-provisioned models are draining resources. By categorizing tasks, you can shift high-volume extraction to Mistral Small 4. This model offers a lower price point for instruction following, while reserving Mistral Large 4 for complex, multi-step agentic reasoning. Once these tiers are optimized, the next step is to ensure that your orchestration layer doesn't introduce more latency than the model itself. ## How Activepieces optimizes the execution layer Activepieces provides the orchestration layer where these model cost optimizations are actually implemented and enforced. Because the platform uses a credit-based system that charges 1 credit per flow run regardless of the logic complexity, builders can design sophisticated routing trees (sending simple classification to Ministral while reserving Mistral Large 4 for final synthesis) without increasing their automation overhead. This ensures that the effort to save money on tokens isn't cancelled out by high execution fees. For organizations requiring strict governance over these AI workflows, Activepieces offers an MIT-licensed core that can be self-hosted on private infrastructure. This allows enterprise teams to implement SSO, SCIM, and detailed audit logs across all Mistral API calls.  By centralizing the execution layer, companies like MoneyGram and FundingSocieties can maintain visibility into how AI credits are consumed across different departments, preventing "shadow AI" spend from unoptimized model calls. The platform further reduces the cost of long-context tasks by automating the Batch API scheduling described in the pricing guide. Instead of manual triggers, you can set a "Schedule" in Activepieces to aggregate data from sources like Google Sheets or SQL databases and send them to Mistral in bulk. This automation ensures you consistently capture the 50% batch discount for high-volume document processing without manual intervention or custom script maintenance, meaning your operational efficiency increases while your recurring labor costs drop significantly. ## Frequently asked questions about Mistral pricing Mistral’s pricing architecture prioritizes transparent, usage-based consumption to ensure that compute costs remain a predictable line item. By aligning their tiers with specific model capabilities, they allow you to swap endpoints based on the required logic density without renegotiating your entire service agreement. ### Does Mistral offer a Batch API for 50% discounts? Workloads that don't require immediate inference can use a Batch API provided by Mistral. This allows you to process large datasets at a significantly reduced price point compared to synchronous requests.  Using this asynchronous endpoint means you're trading immediate response times for lower operational costs. This makes it the standard choice for offline evaluations or massive document processing tasks. ### Are there volume discounts for enterprise users? If you have high-throughput requirements, volume-based pricing is available, typically managed through a commitment-based model rather than a flat per-token rate. Securing a volume discount means the unit cost per million tokens decreases as your total consumption grows. This protects the margin of applications that scale into millions of daily active users. Mistral negotiates these rates based on your projected monthly token volumes. ### How do Mistral's self-hosted costs compare to the API? Self-hosting Mistral models shifts the cost structure from a variable per-token fee to a fixed infrastructure expenditure based on GPU uptime and maintenance. While the API is more cost-effective for bursty or low-volume traffic, self-hosting becomes the economical choice once your monthly token volume exceeds the cost of a dedicated cloud instance. This approach eliminates the provider's service margin. You must factor in the cost of engineering talent required to maintain these private clusters. ## Related reading - [Qwen API Pricing: Costs, Tiers, and Models (2026)](https://www.activepieces.com/blog/qwen-api-pricing-costs-tiers-and-models-2026) - [What is Mistral Large 4? Pricing and Benchmarks](https://www.activepieces.com/blog/what-is-mistral-large-4-pricing-and-benchmarks) - [Zapier vs Power Automate: Compare Before You Choose](https://www.activepieces.com/blog/zapier-vs-power-automate) ## References - [Vantaige](https://vantaige.io/ai-cost-calculator/mistral) - [TechCompare](https://www.techcompare.app/llm-pricing-calculator/mistral-large-3-pricing) - [Mistral](https://aitokenusagecalculator.com/models/mistral-small-4/cost)Pricing for inference isn't a luxury tax anymore.