**The endpoint is where the bill is set**. A dedicated Inference Endpoint charges for every hour it's up, and an always-on endpoint is up for all 730 hours in a month, which means every hour of the month becomes billable. In a shared account, that cost lands on everyone's invoice, including clients who never call it. ### Hugging Face Inference Endpoints cost with scale-to-zero While the endpoint sits idle, scale-to-zero stops the hourly charge, so you pay only for the hours it's awake. The arithmetic runs in this order: 1. Seats: five seats at the PRO-level seat price, so the seat cost is multiplied by five. 2. Subtract the usage credit each seat includes. 3. Add the endpoint's hourly rate multiplied by 730 hours for the always-on case, giving the endpoint's total monthly cost. 4. Replace 730 with the hours the endpoint is actually awake, for the scaled-to-zero case. 5. Compare the two totals. Steps 1 and 2 are identical in both, so the whole difference is step 3 against step 4. The trade-off is a cold start on the first request after idle, so a contractor or customer waiting on that request will notice the delay. If the endpoint backs something that must answer instantly, bill the always-on cost to that project and not to the shared account. ## Watch for costs and limits teams hit first Four metered items hit first: - inference usage beyond included credits - hardware left running - storage past quota - rate limits that stall a job midway Each needs a setting before a client's work touches the account. ### Inference credits and overage Expect to pay more for output tokens than for input, and the spread varies by model: - Llama 3.1 8B is $0.06 per million tokens both ways, so a long answer costs no more than a long prompt. - DeepSeek-V4.1 Flash runs $0.30 in and $1.20 out, so verbose answers cost four times what the prompt did. - The same Qwen3.8-27B costs $0.20 to $2.50 through Nscale and $0.42 to $3 through Novita, so the provider you route to changes the invoice. - DeepSeek-R1 at $2.50 to $7 is the expensive end, and a reasoning model that writes long outputs lands on the $7 side, meaning it's the price ceiling. 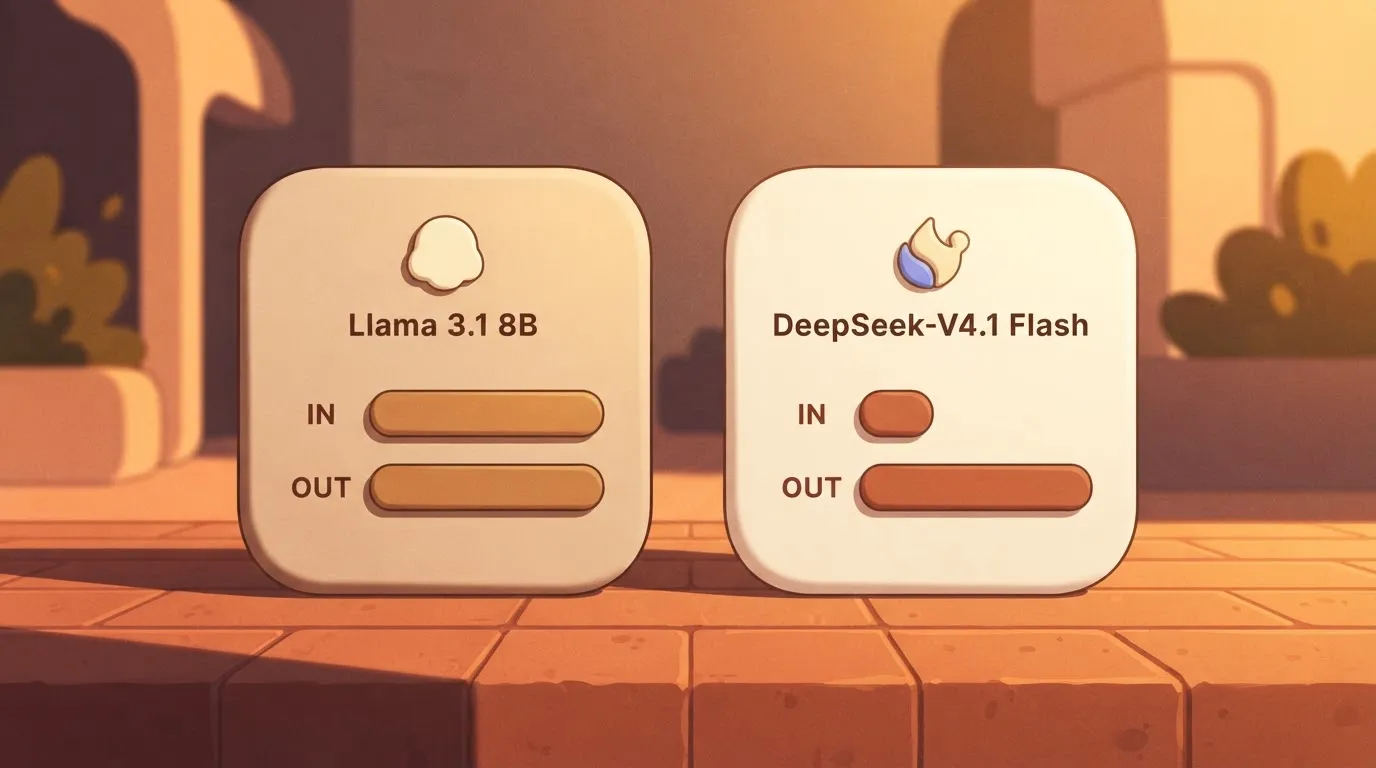 Look at the flow below to see where this bites. Step 5 sends stripped page text to a text model with a prompt to score a site 0 to 100 and write a 120-word summary. That word limit is the only output cap in the flow, and that's a cheap one to set. Set a monthly spend limit, cap output length in every prompt, and tag usage per client. Otherwise one shared account quietly makes your light users pay for the heavy ones. If that scoring flow runs in Activepieces, splitting it into ten steps costs the same as the two-step version it replaced: the published pricing page counts 1 credit per flow run, where Zapier bills per task and Make per module. 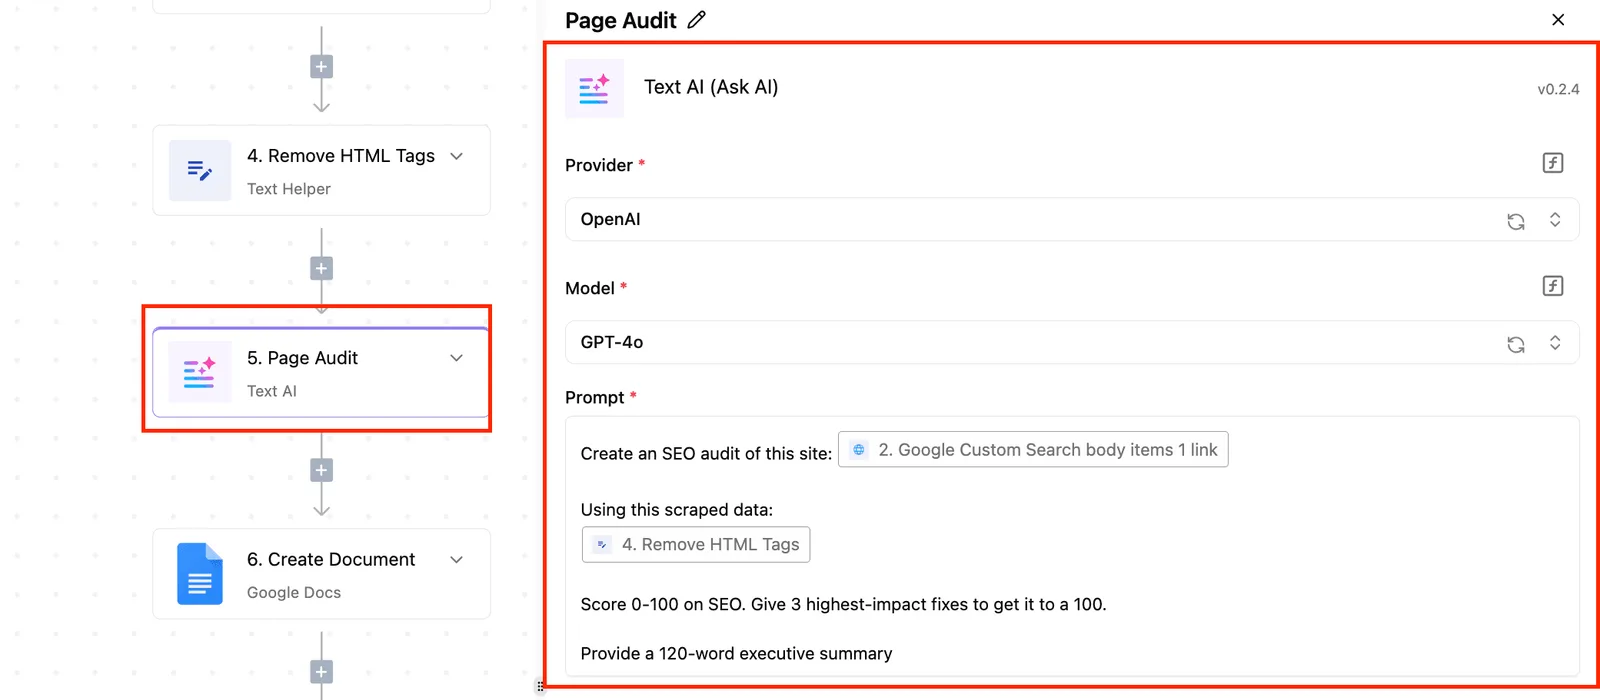 The run is the meter, not the steps inside it, so nobody is taxed for breaking the work into smaller, more reliable integrations. The Free plan includes 1,000 credits a month, and Plus is $20 a month for 10,000 credits, then $0.007 a credit over. The Hugging Face call inside the run stays metered by Hugging Face, so the prompt's output cap still does the work. ### Always-on hardware billing Leave a demo up over a weekend and it costs the same as one used all day, because a dedicated endpoint or Space on upgraded hardware bills for the hours it runs, not the requests it serves. Turn on auto-pause or scale-to-zero where the hardware allows it, and put a shutdown date on every client demo. ### Storage and private repo quotas **Private storage is the quota that creeps**. Checkpoints, datasets, and every fine-tune a contractor saved all count, and nobody deletes them after a project ends. Check usage monthly, and assign each repo to a client so cleanup has an owner. ### Hugging Face rate limits and ZeroGPU quota resets Once a batch job exhausts the daily GPU allowance that ZeroGPU gives each account, it stops partway and finishes the next day, or forces an upgrade you didn't budget. Free and low tiers also throttle requests, and the allowance resets. 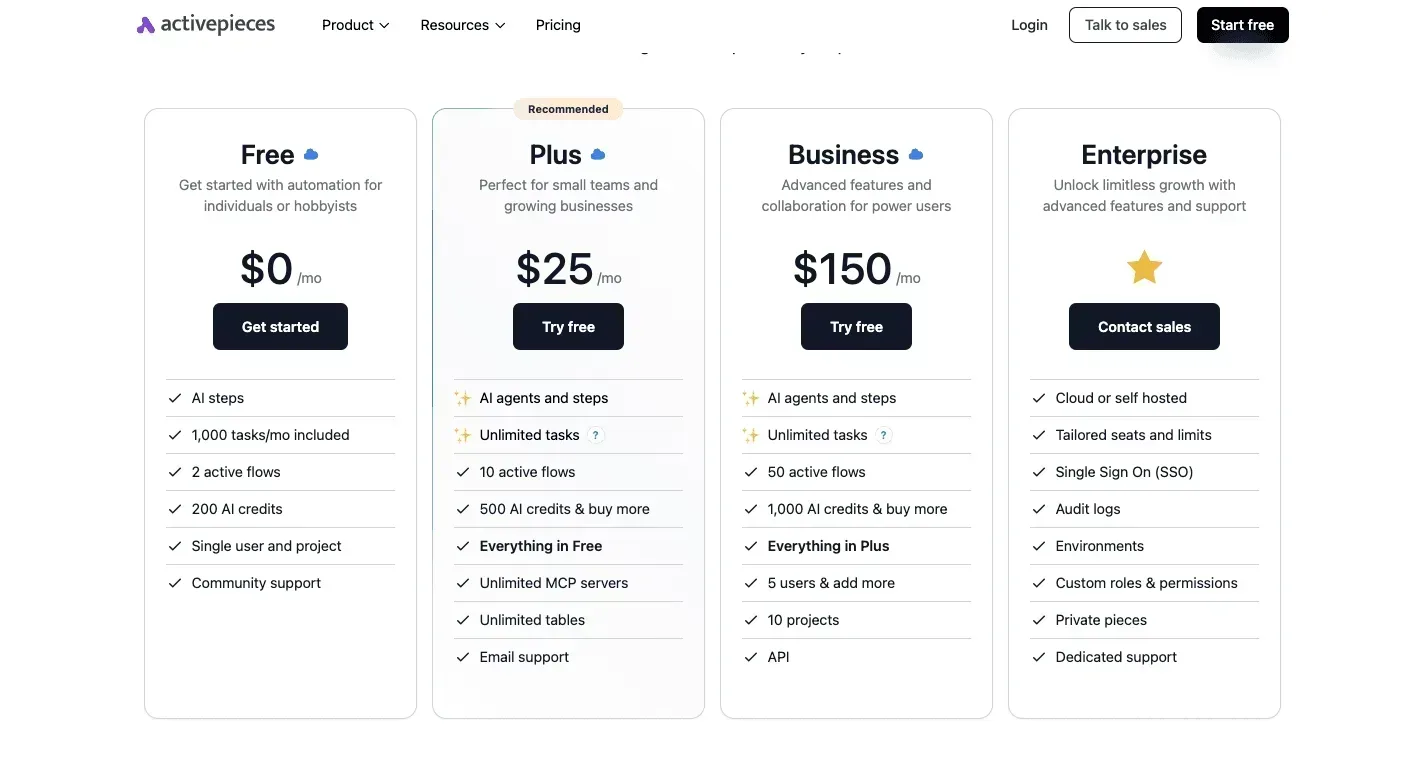 Schedule large runs right after a reset, chunk them, and alert at 80 percent of quota rather than at zero, so you're warned before you're exhausted. ## Check Hugging Face pricing versus competitors If you only need Llama 3.3 70B, the alternatives cost you more per token: Hugging Face's providers are the cheapest of the four for its output, at [0.40 USD per million tokens](https://aiforless.ai/models/meta-llama-3-3-70b-instruct). The table shows how each vendor bills, and the practical takeaway is that **idle cost, not the per-token rate, separates them**. A per-token or per-second bill stops when your traffic stops; an instance-hour bill doesn't. | Vendor | Billing model | Free tier | Idle-capacity cost | Llama 3.3 70B per M output tokens | Check date | |---|---|---|---|---|---| | Hugging Face | Seat plus metered usage | Small monthly credits on free accounts | None on serverless; hourly on dedicated endpoints | $0.40 | 2026-10-31 | | Replicate | Per second of compute | Varies by promotion | None on public models | $2.75 | 2026-10-31 | | Together AI | Per token | Varies by promotion | None on serverless | $1.04 | 2026-10-31 | | SageMaker | Per instance hour | Limited trial hours for new AWS accounts | Full hourly rate while the endpoint is up | Not listed | 2026-10-31 |  ### Per-second and per-token competitors Nearly seven times Hugging Face's rate: that is Replicate's [2.75 USD per million output tokens](https://aiforless.ai/models/meta-llama-3-3-70b-instruct). On a shared account, steady chat volume would drive that overspend. Per-second billing earns its place on bursty or unusual models, where you pay only for seconds used and never for a warm GPU. [Together](https://www.together.ai/gpu/nvidia-h100) AI sits between them at 1.04 USD per million output tokens. That's 2.6 times Hugging Face's price, which is worth paying only if its latency or model catalog fits your build better. ### Hugging Face pricing versus Amazon Bedrock endpoints At 0.72 USD per million output tokens, Bedrock, Amazon's managed model service, lists Llama 3.3 70B. That's 80 percent above Hugging Face but below Together AI, and the price buys you billing inside an AWS account you may already have approved. SageMaker is different: you rent instances, so the bill runs whether or not anyone calls the model. The GPU market helps, since [H100 rental fell](https://virtualized.ai/gpu-price-trends) from 8 USD per GPU-hour in April 2023 to 5.9 in October 2023, 4.2 in April 2024, 3.2 in October 2024, 2.85 in April 2025 and 2.75 in October 2025.  At 2.75 an hour, one always-on GPU still costs about 2,000 USD a month, so cap or schedule the endpoint. ## Cap Hugging Face costs this week The list below is the Monday order: start with the steps that stop money leaving the account. Seat count comes last because it's the smallest line on the bill. 1. Set a spending limit or billing alert on the account that pays for compute, so a runaway job reaches a ceiling you chose. 2. List every running Space and Inference Endpoint, then pause anything nobody can name an owner for. An idle one still bills while it's up. 3. Turn on scale-to-zero for endpoints that serve occasional traffic, so you pay for the hours they work and not the hours they wait. 4. Pick the plan by seat count, after the first three have shrunk the metered side. For one person's experiments a personal account is fine, but it's the wrong place to run client work. If a freelancer's PRO subscription carries a client's Space or endpoint, you're absorbing that client's compute under your own card. Move anything billable to an account you can invoice the client's project from, or add the cost to the retainer. Before an organization plan, priced per seat, pays off, several people have to share private repos, access controls and one bill. Count the people who need write access, not everyone who might look. Enterprise is where you go for tighter controls such as single sign-on, and that's a security decision, not a way to lower spend. Dedicated endpoints bill by the hour the instance is up, upgraded Space hardware bills while it runs, and hosted inference is billed by usage. This is where one shared organization account quietly cross-subsidizes the heaviest user. Tag each endpoint and Space to a client or project, so the invoice you send matches what each one cost to run. ## What Activepieces does about this The problem in this article is metered lines nobody is watching, and a scheduled flow can watch them. In Activepieces you can build a flow that runs each morning, calls the Hugging Face API through the HTTP piece, and lists every running Endpoint and upgraded Space. It then posts the list to a channel with the owner tag next to each item, or pauses anything with no owner. That turns the Monday cleanup into something that happens every day. The same pattern covers the 80 percent quota alert: read usage, compare it with your threshold, and message a person before the job stalls, giving the recipient headroom to adjust before hitting the limit. Cost is a fair worry for a watchdog that runs daily, and the published pricing page answers it. A run counts as 1 credit however many steps it has, so a check that lists, filters, tags and notifies costs the same as one that only lists. The Free plan includes 1,000 credits a month, and a daily check uses about 30 of them.  Activepieces is open source under the MIT licence for its community edition, so you can self-host it. That matters here because the flow holds a Hugging Face token with permission to pause paid hardware, and you may prefer that token never leave your own infrastructure. Self-hosting is also the way to keep one client's credentials out of another client's workspace. None of this replaces the spend limit on the Hugging Face account itself, which is the first step in the Monday order. The flow cannot cap a bill. It makes sure the person who owns each endpoint hears about it while there is still time to switch it off. ## Frequently asked questions ### Is Hugging Face free to use? Yes: an account, public model and dataset hosting, and browsing and downloading public repositories cost nothing. The charges start when you attach metered services, such as inference endpoints, dedicated compute, or Spaces on paid hardware. Those bill by usage whichever plan the account is on, so a free account with a card attached can still produce an invoice. If the invoice goes to a client, decide who owns that card before anyone launches anything. On a shared account, one person's idle GPU is billed to everyone. Some pricing details remain open, and I wouldn't quote them to a client until they're checked against the live pricing page: - The current monthly price of PRO, which has been reported at two different levels since a mid-2026 change - Whether a free inference tier still exists and what it covers - The rate charged while an endpoint is scaled to zero - Whether Team plans include compute credits - What happens when a ZeroGPU quota runs out ### Can I cancel PRO and keep my models? Yes, your repositories stay on your account after you cancel. What changes is the allowance: private storage and any PRO-only quotas revert to the free limits. If you're over them, you may have to delete or move private repos before you can add more. Export or trim private work before the renewal date, not after. Also confirm the effect on any Spaces or endpoints you run, because those are separate line items and don't disappear with the subscription. ### Does Hugging Face charge for downloading models? Not per download. Pulling public models is not metered the way compute is, though rate limits apply, and heavy automated pulls can hit them. The cost that does arise is on your side: a CI job that re-downloads a large model on every run burns build minutes and bandwidth you pay for elsewhere. Cache the weights in your pipeline. That's a cheap fix, and it keeps a client's build bill from carrying your repeated downloads. ### Do education or nonprofit discounts exist? I couldn't confirm a published education or nonprofit discount, so don't build one into a quote. Larger organisations are usually handled through the sales route for the Enterprise tier, and that's where to ask. If a client claims a discount, get it in writing from Hugging Face first. Otherwise you'll be absorbing the difference between the price you quoted and the invoice that arrives. ## Related reading - [GitLab Pricing in 2026: What Teams Pay](https://www.activepieces.com/blog/gitlab-pricing-in-2026-what-teams-pay) - [Snowflake Pricing Explained for 2026 Data Teams](https://www.activepieces.com/blog/snowflake-pricing-explained-for-2026-data-teams) - [HeyGen Pricing for Creators, Marketers and Teams](https://www.activepieces.com/blog/heygen-pricing-for-creators-marketers-and-teams) ## References - [AIforLess](https://aiforless.ai/models/meta-llama-3-3-70b-instruct) - [Hugging Face](https://huggingface.co/inference/models) - [Virtualized.ai](https://virtualized.ai/gpu-price-trends)One forgotten upgraded Space turns a flat bill into a variable one, and nobody else on the account will notice it for you.