Limits that are not on the launch page are the ones that bite, much like Gmail API quotas that only show up once volume arrives. Before the swap, confirm these on the model card. Each item matches a way a step fails quietly. A gap in the card means you test that point yourself rather than assume it. - Context window, meaning the most input one step can send before long threads or attachments get dropped or rejected. - Output limit, meaning the longest reply a step can return before generated code or summaries end mid-line. - Per-token price, plus the date any promotional rate ends, so a cost estimate does not double the day the promotion stops. - Which plan or endpoint exposes the model, because a model your account can not call fails at the first run. Once those four are written down, run a small batch of real tickets through the new step. Compare the output with the old one before you cut over. ## What is measurably new in MAI Code 2 You can only test what the maker has actually stated, and your ticket batch is no different. For MAI Code 2 I could confirm no figure with a source page and date, so none appears below. ### Figures the maker published Six claims are what a workflow builder would check first. The table shows what to look up on the maker's own pages before you size a prompt or a budget, and why each blank matters. | Figure | Source page | Date | |---|---|---| | Context window | Not confirmed | Not confirmed | | Output limit | Not confirmed | Not confirmed | | DeepSWE benchmark score | Not confirmed | Not confirmed | | Claim of matching GPT-6.1 Sol at lower cost | Not confirmed | Not confirmed | | GitHub Copilot plans that include it | Not confirmed | Not confirmed | Until a row has all three cells filled from the maker's page, treat it as marketing, not a spec.  An unchecked context window means you can not know when a long **ticket thread gets silently truncated**. An unchecked output limit means a long generated patch may be cut off mid-file with no error. The cost-versus-GPT-6.1 Sol claim in particular needs the benchmark and pricing pages behind it before it justifies swapping models. I found no confirmed source for the model ID, API access, or native workflow-tool support. That gap is why the next sections use general blocks (HTTP request, custom provider, MCP). MCP is the Model Context Protocol, an open standard that lets an AI client call tools and data through a server. Without a documented endpoint, you can not write a reliable call, so check the maker's pages first. ## Connecting MAI Code 2 in a workflow today Three general routes work without native support, in order of simplicity: an HTTP request, a custom AI provider, or MCP. We have not tested any of them against MAI Code 2. Each depends on what the maker's docs actually publish. ### Route 1: an HTTP request step Take three things from the docs: the endpoint URL, the auth method, and the exact model name. Put the endpoint in the step's URL field and the key in a header, using your platform's stored credentials rather than pasting it into the step. 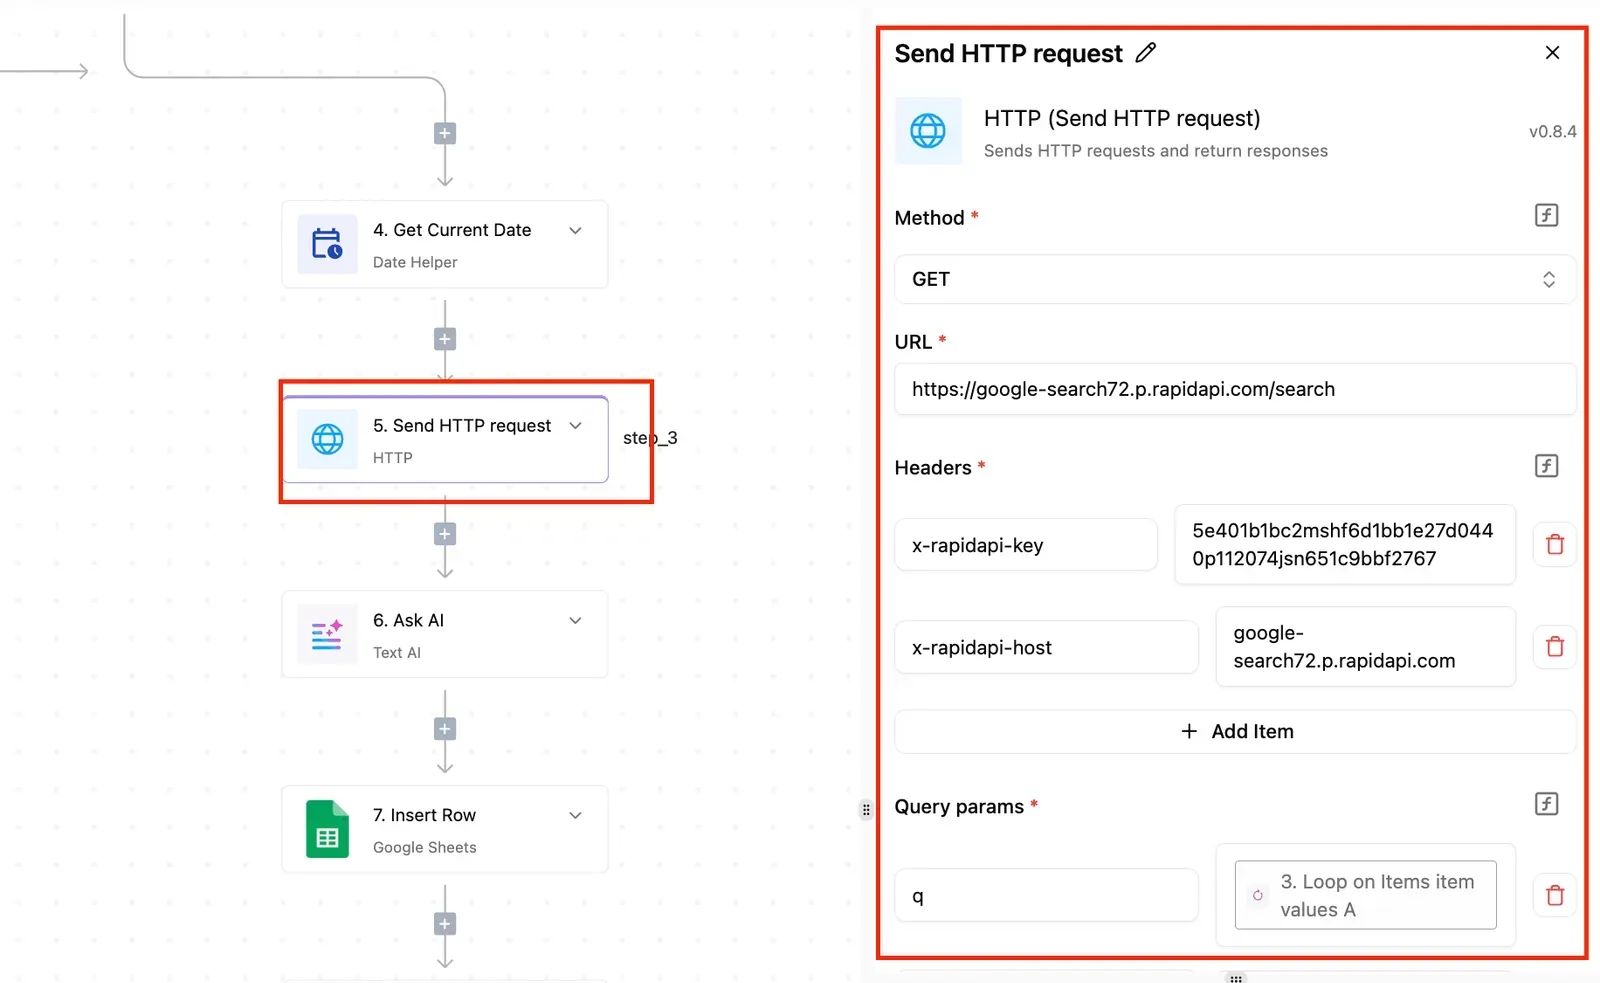 **Copy the model name character for character**, because a near miss returns an error that reads like an auth failure. Check the docs for rate limits too, since a looping workflow hits them first. ### Connect MAI Code 2 as custom AI provider Only if the maker documents an OpenAI-compatible endpoint does the second route exist, an AI step with a custom or OpenAI-compatible provider. "OpenAI-compatible" means the endpoint accepts the same request and response format as OpenAI's API, so any tool built for that format can be pointed at it by changing the base URL.  If the maker documents one, you enter the base URL, the key, and the model name once. Every AI step in your workflows can select it. A platform that sells you its own model has made your AI decision and priced it before you open the product, and a custom provider setting exists to undo exactly that. Activepieces takes whichever model you point it at, MAI Code 2 included once its endpoint qualifies, using your own provider key, so the model spend lands on your provider account at your rate. From the Plus plan up, bringing your own key makes every AI step 1 credit, against 2, 10 or 20 when the model is supplied for you, and the same flows can be reached from Claude, ChatGPT, Cursor or any MCP client. If the docs describe a different request format, do not force it. Fall back to Route 1. ### Route 3: an MCP server If MAI Code 2 is the one calling your tools, not your workflow calling it, MCP is the route. You need the server's address and its auth method from the maker's docs. If the maker publishes no MCP server, there is nothing to connect. Stop here and use Route 1. Pick the first route the documentation supports, and the next section covers what to verify before you rely on it. ## Compare MAI Code 2 pricing and performance Only while its promo runs does MAI Code 2 undercut the older Claude Haiku 4.5. At $0.50 input and $2.50 output per million tokens it costs half as much, making twice as many tokens available for the same spending. Its list price from 2027-05-17 is $1 and $5, which [LiteLLM](https://models.litellm.ai/models/mai-code-2) shows is identical to the older Haiku 4.5's price; that figure does not carry over to Claude Haiku 5.5. That eliminates cost as a distinguishing factor from that date. **Budget a workflow on promo rates and its bill doubles in May.** The older GPT-5 mini listed at $0.25 and $2, cheaper on both sides. Gemini 3.6 Flash, a previous-generation Flash, sits higher at $1.50 and $7.50, so a newer name is not automatically the cheaper one. Beside those prices, the table has the other columns. Speed and context are blank wherever no figure was published. That matters because price per token says nothing about how long a run takes or how much a request can carry. | Model | Input / output $ per 1M | Speed | Context | Availability | Check date | |---|---|---|---|---|---| | MAI Code 2 promo | 0.50 / 2.50 | not published | not published | Promo until list pricing starts | 2026-11-18 | | MAI Code 2 list from 2027-05-17 | 1 / 5 | not published | not published | From 2027-05-17 | 2026-11-18 | | Claude Haiku 4.5 (older model) | 1 / 5 | not published | not published | not published | 2026-11-18 | | Other: GPT-5 mini (older model) | 0.25 / 2 | not published | not published | not published | 2026-11-18 | | Other: Gemini 3.6 Flash | 1.50 / 7.50 | not published | not published | not published | 2026-11-18 | With speed and context unpublished for MAI Code 2, set your timeouts and payload limits from a small test run of your own, not from this table. ## What to watch for MAI Code 2 Watch the maker's own pages for speed, model ID and pricing changes. Watch your automation platform's public repository for any sign of native support. Until those move, nothing here changes your build. If you budget per run, any cost estimate you make now has a shelf life. The one dated item the maker has put on the calendar is a price change on 2027-05-17. Note that date next to the estimate and recheck it before you commit a high-volume workflow. ### What the maker has not published The gaps are where your timeouts and payload limits get decided. Check these on a schedule and re-run your own test when any of them changes: - [Microsoft](https://microsoft.ai/pdf/MAI-Code-2-And-MAI-Code-2-Flash-Model-Card.pdf) speed or latency figures for MAI Code 2 - The direct API model ID, which you need before an HTTP request or custom AI provider can call the model without a gateway in between - Commits in your platform's public repository that mention MAI, which would be the first visible sign of native support - New entries in that platform's integration catalog, which is where a ready-made integration would appear Treat each as a reason to retest, not a prediction. A commit is not a release, and a catalog entry is not a guarantee it behaves like the general building blocks. This week, read the maker's documentation, then try route 1 on a handful of your own tasks. Log the response times and failures you see, so you have your own numbers when the published ones arrive. ## What Activepieces does about this Activepieces does not have a native MAI Code 2 integration, and nothing the maker has published says it should, so there is no built-in, native way to select MAI Code 2 in Activepieces. 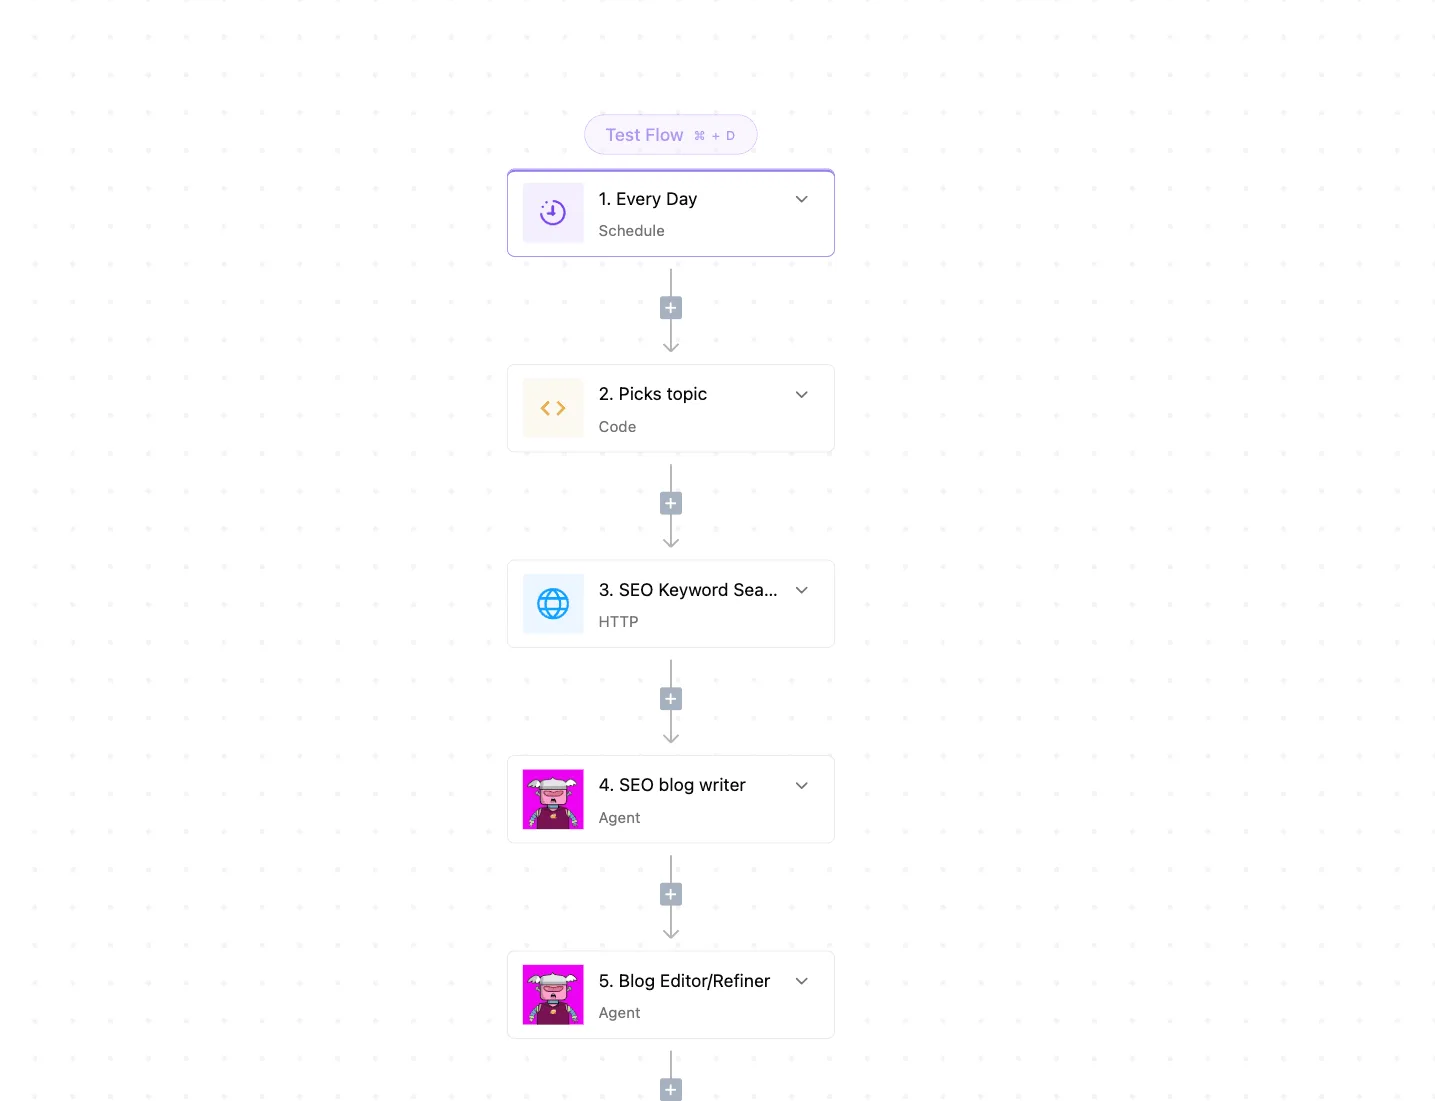 What it has is the general machinery this article leans on: an HTTP request step, an AI step that accepts a custom or OpenAI-compatible provider, and MCP. You can wire the model in through any of them as soon as the maker documents an endpoint, without waiting for us to ship anything. The core of the product is MIT-licensed and the source is public, so the commits and catalog entries I suggested watching are things you can check yourself in the repository. If native support ever arrives, that is where it will show up first. Until then, anyone who tells you otherwise is working from something other than the maker's pages or ours. The part that bears on your budget is the key. When you bring your own provider key, the model spend lands on your provider account at your rate, and from the Plus plan up every AI step costs 1 credit, against 2, 10 or 20 when the model is supplied for you. That matters here because the promo price of $0.50 and $2.50 ends on 2027-05-17. With your own key, the doubling to $1 and $5 shows up in your provider invoice, not as a repricing someone else decides. The same flows can be reached from Claude, ChatGPT, Cursor or any MCP client, so if the maker does publish an MCP server, you can test the model on one workflow before touching the rest. I have not run MAI Code 2 through any of this, and I will not claim it works until the endpoint is documented and a handful of your own tickets have passed through it.  ## Frequently asked questions Until the published numbers arrive, the only answers worth giving are the ones the maker's own pages support. Where those pages are silent, the answer is "unknown." Your workflow should be built to survive that. Is MAI Code 2 available through an API yet? I can not confirm it from the maker's pages, so plan as if it is not. Do not build a production trigger on an endpoint you can not point to in their documentation. If one appears, your HTTP request step is the first place to test it, with failures logged. Does Activepieces support MAI Code 2 natively? Nothing the maker has published describes a native integration. Treat it as unsupported natively. The general building blocks, an HTTP request, a custom AI provider, or MCP, each work only once the maker exposes something for them to call. ### Can I use MAI Code 2 with an OpenAI-compatible provider setting? Only if the maker states that its interface is compatible, and I have not seen that stated. A compatible-looking URL is not evidence. Differences in authentication, streaming, or tool-call formatting tend to surface as silent failures, the kind that look like a run succeeding with an empty result. Test with one low-stakes request before wiring it into anything that emails a customer. How much does MAI Code 2 cost per task? The maker has not published a per-task price. Any cost-per-run estimate you build today is a guess. Meter your own runs and compare them against the published pricing once it exists. ## Related reading - [Plaid Pricing 2026: Cost Per Connection and Request](https://www.activepieces.com/blog/plaid-pricing-2026-cost-per-connection-and-request) - [SAP Business One AI Assistant: Edit Automations](https://www.activepieces.com/blog/sap-business-one-ai-assistant-edit-automations) - [Asana Automations: A Quick Guide for Modern Teams](https://www.activepieces.com/blog/asana-automations) ## References - [LiteLLM](https://models.litellm.ai/models/mai-code-2)What a workflow cares about is whether the step still returns something the next step can parse, not how the model scores.