Read the plan rows as seats for people and the final row as the line your workflows draw from. Every ChatGPT plan carries no API access, and only the last row bills by usage. | Tier | Price per user per month | Inclusions | Usage limits | API access | |---|---|---|---|---| | Free | $0 | Basic chat access | Capped | None | | Go | $8 | Expanded access over Free | Higher than Free | None | | Plus | $20 | Advanced intelligence features | Higher than Go | None | | Pro | Listed on OpenAI's pricing page | Top individual tier | Highest for individuals | None | | Business | Charged per seat | Shared workspace for teams | Set by plan terms | None | | Enterprise | Negotiated with OpenAI | Organisation-wide controls | Set by contract | None | | API pay-as-you-go | No monthly fee | Models called from your own code | Rate limits by account | Yes, billed per token | Nothing in a seat price tells you what a workflow costs. It tells you only what a person pays to chat. Because the two products sit on different billing systems, a key created in the developer platform draws on API credit, not on your Plus seat. So a team paying for Business seats still gets a token invoice the first time a flow calls a model. Budget both lines separately, or the API bill will arrive as a surprise. ### When a ChatGPT subscription beats API billing If a person reads, drafts and edits in the chat window, a flat seat at $8 or $20 beats metered billing, because heavy chatting costs the same every month. Once a step runs unattended, such as classifying tickets overnight, the seat's the wrong tool. Pay per token there, and send each step to the cheapest model that handles it. ## OpenAI API cost for 1,000 summaries and classifications ### The gap between the top and bottom tier $15.50 buys a thousand email summaries on GPT-6 Astra, and the same thousand cost $0.155 on GPT-6 Luna, so the cheapest model does the same work for one hundredth of the money. 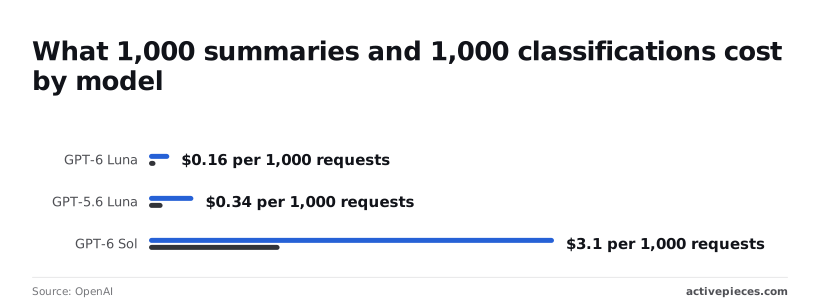 Take 800 input and 150 output tokens per summary and 400 and 20 per classification, priced from [OpenAI's pricing page](https://developers.openai.com/api/docs/pricing). The multiple's the same for both jobs, so a lighter task doesn't narrow the gap. For summaries (800 input, 150 output tokens), $15.50 on GPT-6 Astra against $0.155 on GPT-6 Luna is a gap of $15.345, which means Astra costs roughly a hundred times more per summary. For ticket classifications (400 input, 20 output), $5.00 against $0.05 is a gap of $4.95, making the expensive model a hundred times costlier per ticket. Both come to 100x. Neither job needs the flagship, so the cheaper tiers below are where the saving sits. ### What mid-tier OpenAI models cost per task The summary batch cost $3.10 on the earlier GPT-6 Sol, one fifth of Astra. GPT-5.6 Sol costs $6.20 and GPT-5.6 Terra $3.40, so the older models cost more than a newer Sol such as GPT-6.1 Sol. GPT-5.6 Luna's $0.34, over twice GPT-6 Luna's $0.155, which means staying on an old cheap model still overpays. For classification, a label's about 20 output tokens, so the bill's mostly input. On the earlier GPT-6 Sol the same batch cost $1.00, and a mid-tier model like GPT-6.1 Sol covers the job, so Astra's $5.00 is paying for capability this step doesn't need. Run the same batch on GPT-5.6 Sol and it's $2.00; GPT-5.6 Terra is $1.04, GPT-5.6 Luna $0.104, and GPT-6 Luna $0.05. That means Luna costs a fortieth of what GPT-5.6 Sol does. ### OpenAI API cost at monthly volume At 10,000 summaries a month, Astra costs $155 and Luna $1.55, making Astra a hundred times as expensive, which means you're burning $153.45 monthly for identical results. At 100,000, that becomes $1,550 against $15.50. Run classifications instead and it's $50 and $0.50 at 10,000, then $500 and $5.00 at 100,000. The flagship choice's a four-figure monthly decision on one step. A platform that bundles a model into its product has chosen your model and set its price before you log in. Activepieces works the other way round: its OpenAI integration, one of 741 counted in its open source monorepo, runs on your own OpenAI key, so GPT-6 Luna's $0.50 per million output tokens is billed to your OpenAI account at your rate, not ours. The model is a setting on each action, which means the strategy stays yours, and you can reach the same flows from Claude, ChatGPT, Cursor or any MCP client; the [integration's page](https://www.activepieces.com/pieces/openai) lists the actions it exposes. ## Hidden OpenAI API costs and usage limits Beyond list price, five charges sit on the invoice: - output tokens priced above input - reasoning tokens billed as output - per-call tool and search fees - tier-gated rate limits - retries or loops that repeat paid work ### Reasoning and output tokens A one-word classification can cost far more than its visible length suggests. Output's the costly side of every request, and reasoning models bill their hidden thinking tokens at the output rate. You never see those tokens in the reply, yet you pay for them. At $50, the flagship's output rate's close to its 2023 level. A flagship on a yes/no step pays top output rates for thinking the step never needed. ### OpenAI API tool-call and search fees On top of tokens, web search, file search and code execution are charged per call or per session. An agent that searches on every step pays that fee on every step, so switch each tool on only for the steps that need it. Once retrieved, the text re-enters the next request as input tokens, which bills you a second time for the same lookup. ### OpenAI API rate limits and usage tiers A new account running a bulk job hits throttling first. Requests-per-minute and tokens-per-minute ceilings depend on your usage tier, which rises with spend, and the usual fix's paying more to move up a tier. Set alerts below the cap, not at it. Prepaid credit and monthly spend caps stop a surprise bill, but they also halt the workflow mid-run. ### Retries, long prompts and loops in OpenAI bills When a retry follows a timeout, the whole prompt is resent, so a long system prompt's paid for twice. Fine-tuned models and embeddings carry their own rates, separate from base chat pricing, and each appears as its own invoice line.  Without an iteration limit, a loop keeps calling the model until something breaks. Cap iterations and maximum output tokens on every agent step, since those two settings bound the worst case. ## OpenAI against Anthropic and Google on price At the flagship tier, OpenAI and [Anthropic](https://www.anthropic.com/claude/haiku) charge the same, and Google charges roughly a fifth to a quarter as much, according to [whatdoesaicost.com](https://whatdoesaicost.com/prices/). That gap matters more once you've capped output tokens. ### Price comparison table Vendor choice at the top tier moves your bill by a factor of four or five, while the OpenAI-versus-Anthropic choice moves it by nothing. That's what the table below shows, with flagship input and output prices per 1M tokens. | Flagship model | Input (per 1M) | Output (per 1M) | |---|---|---| | OpenAI GPT-6 Astra | $10 | $50 | | Anthropic [Claude Fable 5.1](https://docs.claude.com/en/docs/about-claude/models/overview) | $10 | $50 | | Google Gemini 3.1 Pro | $2 | $12 | At $50 per 1M output tokens, a 1,000-token reply costs five cents on GPT-6 Astra or Claude Fable 5.1. The same reply on [Gemini](https://gemini.google/subscriptions) 3.1 Pro costs about 1.2 cents. Input's five times cheaper on Google, but output's only about four times cheaper, so the gap narrows as replies get longer relative to prompts. ### Where OpenAI is cheaper and where it's not Against Anthropic's flagship, OpenAI's never cheaper at list price, because $10 in and $50 out match exactly. Against Google's flagship, OpenAI loses on every token. Gemini 3.1 Pro's a preview model, though, so check whether a preview tier's acceptable for production work before you build on its price. OpenAI's case rests on its lower tiers. GPT-6 Luna's built for efficient, high-volume work, and Anthropic's [Claude Haiku 5.5](https://docs.claude.com/en/docs/about-claude/models/overview) targets the same job. For a classification or extraction step, those tiers are the right comparison, not the flagships. Pricing a whole pipeline off the $10/$50 line overstates what most steps should cost. These figures were current as of October 2026, so recheck them before you commit a budget. ## Route each workflow step to the cheapest adequate model with Activepieces Pick the OpenAI model separately on every step of a flow in Activepieces, so a classification step on GPT-6 Luna at $0.50 per million output tokens can sit beside a drafting step on GPT-6.1 Sol at $10, and nothing defaults to your best model by accident. That matters because the prices above only bite when every step pays the top rate. ### One model per step In Activepieces, each OpenAI action carries its own model field. A step that sorts an incoming ticket into a category can point at GPT-6 Luna, which OpenAI positions for cost-sensitive, high-volume work. The step that drafts the customer reply can point at GPT-6.1 Sol, which balances intelligence and cost. Reserve GPT-6 Astra for a step that needs complex reasoning, and you'll find few steps do.  When the bill climbs, you open the flow and see which step's on which model, because the model choice becomes a visible setting on the canvas, not a hidden default in someone's script.  The same applies if you call Anthropic or Google from a step instead: the field's per step there too. ### Escalate only when the cheap model is unsure Ask the cheap classifier to return its label plus a confidence value, then add a Router step after it. One branch handles confident results and sends them straight on. A second branch catches low-confidence results and passes the same input to a stronger model.  Anything the conditions miss goes down the Otherwise branch, so nothing falls through silently. Step 5 in the screenshot below is a Router with two conditional branches, each leading to its own Agent step, plus an Otherwise path. Notice that the expensive path sits behind a condition, so it only costs money on the inputs that earn it. Both branches still have add buttons, which's where you'd insert a fallback or a human review step. Activepieces routes the calls but doesn't change OpenAI's per-token prices: on your own key, GPT-6 Luna's $0.50 and GPT-6.1 Sol's $10 per million output tokens are the rates you're billed, and add-on fees stay as OpenAI lists them. A flow that sends long outputs to a cheap model still pays for every output token. And routing only saves money if the cheap model's labels are good enough, so test its confidence values on real tickets before you trust the threshold. ## A Monday plan to cut an OpenAI bill Do these five things in order, and test the cheap model's labels on real tickets before any traffic moves. The list shows the full sequence; the usage pull comes first because it tells you which steps are worth moving at all. 1. Pull last month's usage by model. 2. Set a monthly budget and alerts. 3. Move classification to the cheapest tier. 4. Enable caching and Batch for work that can wait. 5. Calendar a quarterly pricing re-check. The three steps people get wrong are expanded below. ### Audit usage by model Export usage grouped by model and split input from output tokens. If most spend sits on your flagship, GPT-6 Astra, find out which workflows call it. Expect output tokens to drive the total, so a step that writes long replies costs far more than one that returns a label. That tells you where to look first, and it's rarely the step you assumed. Set the monthly budget and alert thresholds now, before you touch a prompt. A routing change that misfires, such as a retry loop or a verbose prompt, shows up as a spike. Without an alert, you find it on the invoice instead of the same day. ### Move easy workflow steps to a cheaper model Classification and field extraction rarely need your best model. Send them to GPT-6 Luna, the tier built for cost-sensitive high-volume work, and keep GPT-6 Astra for steps that reason or write. Compare Luna's output against labeled tickets first, and keep the old model as a fallback for low-confidence results. Then turn on caching for prompts with a long shared prefix, and use Batch for reports and backfills nobody's waiting on. Both discount work you were already doing, so neither changes what the product does. ## Frequently asked questions **Is there a free tier for the OpenAI API?** Not as a standing arrangement you should plan around. OpenAI has offered promotional credits to new accounts at various times, but they come and go, so check your billing page for what your account has. Budget as if every call's paid. ### How do I check how many tokens my prompt uses? Use OpenAI's online tokenizer for a quick look, or the open-source tiktoken library to count locally before you send anything. Every API response also carries a usage field that reports input and output tokens for that call. That field's the number you're billed on, so log it per step and you'll see which step costs the most. ### Failed requests and price changes **Does OpenAI charge for failed requests?** Generally, a request that errors out before the model generates anything isn't billed. A request that completes is billed, even if your code throws the answer away because it failed validation. Retry loops are where this bites: each retry that returns output's a fresh charge. Cap your retries, and check the usage field on the failures too. **How often does OpenAI change its API prices?** Irregularly. Changes tend to arrive with new model releases, and older models usually keep their listed rates rather than being repriced on the spot. Pricing's also not one number per model, since add-on tools and features carry their own fees. Read the pricing page when you pick a model, and again before you commit a workload to it. ### ChatGPT versus the API **Is the ChatGPT API the same as the OpenAI API?** Loosely, people use the name for the OpenAI API, and that's the product you pay for per token. A ChatGPT subscription's a separate consumer and team product with its own billing. Paying for one doesn't give you credit on the other, so keep the two budgets apart. ## Related reading - [SAP S/4HANA Purchase Order Workflow for MS Teams](https://www.activepieces.com/blog/sap-s-4hana-purchase-order-workflow-for-ms-teams) - [Content Creation Workflow: How Successful Teams Do It](https://www.activepieces.com/blog/content-creation-workflow) - [Automate Blog Writing with AI: A Step by Step Guide using OpenAI](https://www.activepieces.com/blog/automate-blog-writing-with-ai-a-step-by-step-guide-using-openai) ## References - [OpenAI](https://developers.openai.com/api/docs/pricing) - [whatdoesaicost.com](https://whatdoesaicost.com/prices/)A ChatGPT subscription pays for the chat app, while API calls are billed per token on a separate account.