| Model | Output $/1M tokens | |---|---| | Kimi K3 | 13.50 | | Qwen3.8 2.4T | 6.00 | | GLM-5.3 | 4.40 | ### Flagship model price gaps on SiliconFlow Kimi K3 costs about three times what GLM-5.3 does. **At 50 million output tokens a month**, that's $675 against $220, a $455 gap before you have tested whether the quality difference matters for your task.  ### SiliconFlow price spread within one model family Within one vendor's line the spread is just as wide. On [SiliconFlow's pricing page](https://www.siliconflow.com/zh/pricing), Qwen3.5-9B is $0.15 per million output tokens, Qwen3.6-35B-A3B is $1.80, Qwen3.5-122B is $2.08, Qwen3.6-27B is $3.20 and Qwen3.8-2.4T is $6. A classification or extraction job that the 9B model handles shouldn't run on the largest one, because the top of that range **costs 40 times the bottom**. The 122B model costs only about 16% more than the 35B-A3B, which makes that step easy to test.  ### Image models Image models **charge per image, not per token**. On [SiliconFlow's pricing page](https://www.siliconflow.com/pricing), Z-Image-Turbo is $0.005 per image, FLUX.2 pro is $0.03 and FLUX.2 flex is $0.06.  $5, $30 or $60 buys a thousand images, a twelvefold spread, meaning your monthly budget determines which models you can afford. Draft or bulk work belongs on the cheapest model, with the dearer ones kept for final renders. ### SiliconFlow embedding, reranking, and dedicated GPU pricing When a retrieval pipeline makes many embedding and rerank calls per query, those charge on input. Cost the whole pipeline, not the generation step alone, and check each model's unit before comparing it with a chat model. viz type=stripplot title="How SiliconFlow's Qwen models spread on output price" unit="$ per 1M output tokens" source="SiliconFlow - https://www.siliconflow.com/zh/pricing".8 and $6." Qwen3.5-9B: 0.15 Qwen3.6-35B-A3B: 1.8 Qwen3.5-122B: 2.08 Qwen3.6-27B: 3.2 Qwen3.8-2.4T: 6 Billed for time, not tokens, dedicated and reserved GPUs only beat per-token billing if your traffic keeps the GPU busy. Divide the hourly rate by the tokens you actually push through it to get a comparable per-million figure. ## Rate limits, free credit, discounts, and billing The list price is the floor. Four things sit on top of it: how fast you may send requests, what free credit comes with conditions, which discounts exist, and how SiliconFlow bills the account. Each changes the per-million figure you computed above. ### Rate limit tiers SiliconFlow meters traffic in requests per minute (RPM) and tokens per minute (TPM), and the ceilings rise with account spend, in tiers labelled L0 to L5. A tier that fits a prototype can throttle a production batch job, so a slow queue costs you wall-clock time even when the token price is low. I have no confirmed RPM or TPM figures to quote. The table below says which limit binds first and what that does to a team, not what the numbers are. | Model type | Limit that binds first | What it changes for a team | |---|---|---| | Chat | TPM, because long prompts and long outputs use up tokens before requests | Concurrency is capped, so a burst of users queues instead of finishing together | | Embedding | TPM, because inputs are large and requests are small | Bulk indexing runs at the tier's pace, so a backfill takes days instead of hours on a low tier | | Free models | Both RPM and TPM, at the lowest ceilings | Fine for testing, unreliable as a production dependency | Because tiers follow spend, ask whether a tier can fall back when monthly spend drops. If it can, a quiet month can leave you throttled on the month a launch lands.  Check the downgrade rule on the vendor's rate-limit page before you plan around a tier. ### SiliconFlow free credit and its conditions If a new account receives promotional credit, it usually carries an expiry and sometimes restrictions on which models it covers. Treat it as a test budget, not as a discount on your steady-state bill. 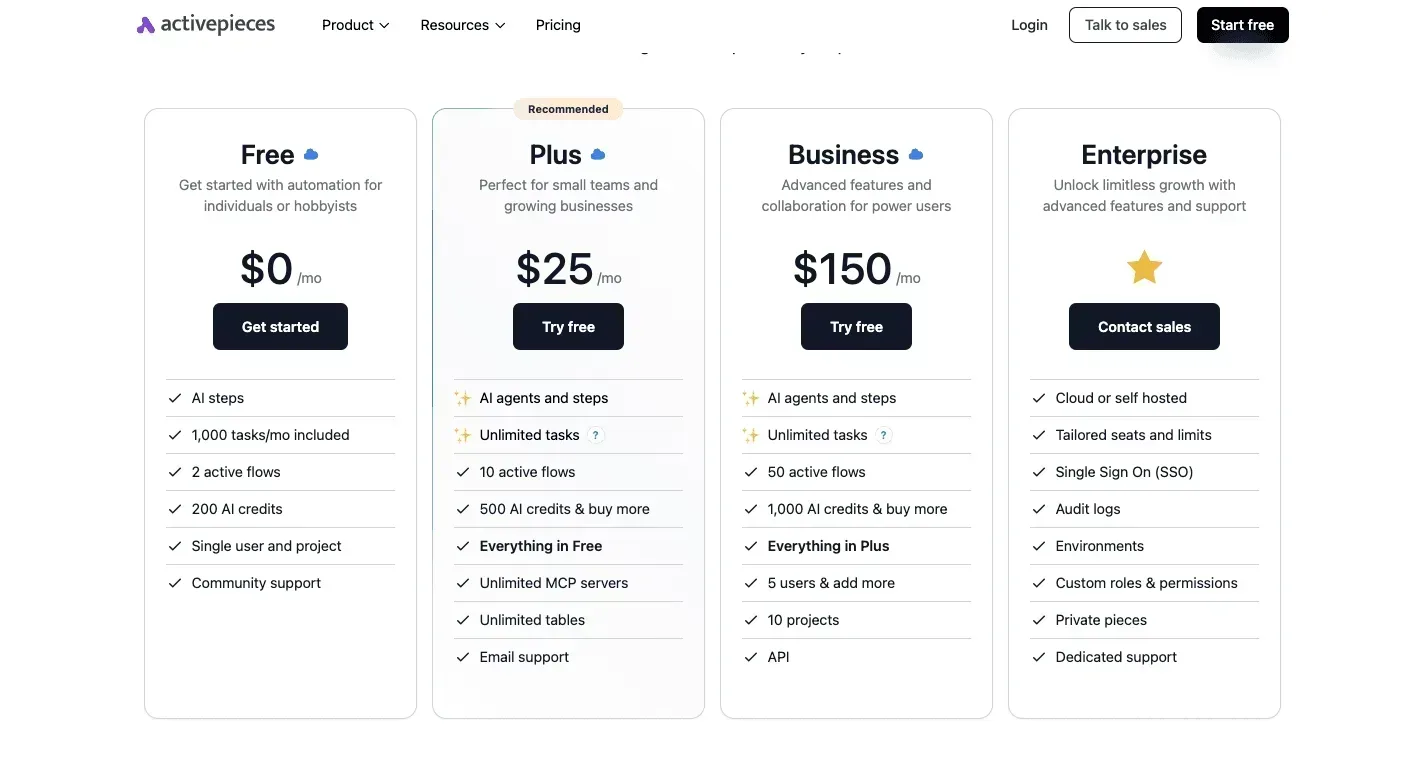 Read the expiry on your account page, and run your real workload through it early, so you learn your actual tokens per task before the credit lapses. I couldn't confirm a batch discount or a cache discount for SiliconFlow's API, so don't assume either. Without them, queuing work overnight saves nothing on price. The benefit of batching is operational: fewer idle gaps against your rate limit. Cost your workload at list price and treat any discount you later find as upside. ### SiliconFlow billing and top-up rules You spend from a prepaid balance, because billing is pay-as-you-go. **That means a balance that runs out stops your service, not your invoice.** Set a balance alert, and confirm whether topped-up funds expire or can be refunded. If they can't, a large top-up is a commitment, so size it to the next month's traffic, not to the cheapest-looking round number. ## Named workload costs per month Sizing that top-up means turning each workload into tokens per month, then multiplying by the per-million-token price of the model you would run it on. The table shows the three workloads as formulas, so the only inputs are your own counts and the prices on the current price list. | Workload | Assumed tokens per month | Cheap model cost | Premium model cost | Arithmetic | |---|---|---|---|---| | Support chatbot | Conversations × turns × tokens per turn, counted separately as input and output | Input tokens at the cheap input price plus output tokens at the cheap output price | The same two terms at the premium prices | Tokens ÷ 1,000,000 × price per million, summed across input and output | | Nightly 50,000-document summary | 50,000 × 30 nights × (document length in, summary length out) | Same two terms, cheap prices | Same two terms, premium prices | Monthly tokens ÷ 1,000,000 × price per million, input and output separately | | Knowledge-base embedding | Corpus tokens, plus changed documents re-embedded each month | Input tokens only, at the cheap embedding price | Input tokens only, at the premium embedding price | Corpus tokens ÷ 1,000,000 × input price per million | You supply every token count here, and the nightly row assumes a 30-night month. Swapping the model changes only the price terms, so the gap between cheap and premium is the same multiple on every row of that workload. ### Support chatbot cost per month Each turn resends the earlier conversation as input, so a chatbot pays for the same context repeatedly. The metered unit is tokens, so long conversations cost more than turns × a flat size suggests. Verbose replies cost more than long questions, since output is usually priced above input. If you cap reply length, you lower the dearer side of the bill. ### Nightly document summaries cost per month Of the three, this workload tolerates delay best, so it's the one to test against any batch discount or lower-priority tier your account offers. The arithmetic multiplies out fast: 50,000 documents a night is **1.5 million requests in a 30-night month**, and a premium model turns a small per-document difference into a large monthly one. Check whether a cheaper model's summaries are good enough before paying the premium on every document. A scheduled [Activepieces](https://www.activepieces.com) flow can make the nightly call to SiliconFlow's API, and the tokens are still metered on your SiliconFlow account. The flow itself is billed by the run, not by what is inside it: Activepieces charges 1 credit per flow run, so a ten-step nightly job (fetch, split, summarise, check, retry, write) costs the same as a two-step shortcut. Zapier's per-task and Make's per-module billing both rise as you break the job into smaller steps, which taxes the very habit that makes a 50,000-document job reliable. ### Knowledge base embedding cost per month There is no generated output here, because embedding bills input tokens only. The first pass over the whole corpus is a one-off cost, and after that you pay only for documents that change. That makes it the cheapest row to forecast, but you must re-embed the whole corpus if you switch embedding models, since vectors from different models aren't comparable. ## SiliconFlow versus Together AI, Fireworks, and OpenRouter On the one open model I could price across vendors, SiliconFlow's output rate matches OpenRouter's and sits a quarter of Fireworks'. The catalogs differ, so treat that as a comparison of one model, not of whole vendors. ### Price for one shared open model Output is usually the larger line on a generation-heavy bill, so the unit here is output tokens per million. The table shows DeepSeek V3.2 output pricing at the three vendors where I have a figure. Fireworks charges four times what the other two do, so a workload that generates long answers will see that gap on every top-up. | Vendor | DeepSeek V3.2 output, per 1M tokens | |---|---| | SiliconFlow | $0.42 | | Fireworks | $1.68 | | OpenRouter | $0.42 | I have no confirmed figure for Together AI on this model, so I left it out of the table instead of guessing. Recheck each price on the vendor's own pricing page on the day you fund the account. The equal figures for SiliconFlow and OpenRouter also don't mean equal bills, since the model you route to and the limits you hit differ. Four other terms decide whether you pay the list price, which is only the metered rate. - The free tier is useful for testing a model, but it tells you nothing about production cost. - If a vendor's rate limits rise with spend or account tier, your early traffic may be throttled below what you planned for, so read how each vendor moves you up. - A batch discount only reduces the bill for work that can wait, so multiply it by the share of your traffic that is truly asynchronous, not by your total. - A dedicated GPU swaps per-token billing for time-based billing, so it pays off only when your steady token volume costs more than the hours you would reserve. ### Which provider fits which workload If your workload is output-heavy and runs on open models, the table says to start with SiliconFlow or OpenRouter and let rate limits and routing decide between them. Fireworks earns its premium only if something outside this table, such as its limits or dedicated capacity, solves a problem the cheaper two don't. Cost your own monthly output tokens at each rate, then adjust for the batchable share, and the right vendor will usually be obvious. ## What Activepieces does about this The cost problem in this article is a per-workload one, and the part of it Activepieces can touch is the plumbing around the model call. A flow can call SiliconFlow through its OpenAI-compatible endpoint, so the base URL, key and model name are the only things you change. A branch can send short, easy items to a 9B-class model and only the hard cases to a flagship. That is the 40-times spread from the price section, applied item by item and not as one choice for the whole job. The same flow can absorb the rate-limit and balance problems described earlier. A failed call can retry with a delay and park the item for the next run instead of dropping it, and a scheduled check can alert you before a prepaid balance runs dry and stops the service. Those are ordinary flow steps, and you can build and test them against the $1 of starter credit before real traffic arrives, which means you can't afford many mistakes. The orchestration bill is the one that stays predictable. Activepieces charges 1 credit per flow run, whatever the number of steps inside it, so adding the retry, the check and the fallback branch doesn't change what the flow costs.  SiliconFlow still meters every token on your own account, so the token arithmetic in the workload table remains the number that matters. The core of Activepieces is open source under the MIT licence, and you can self-host it if you'd rather keep the flows and API keys on your own infrastructure. Some enterprise features sit under a separate commercial licence, so check which edition you need on [activepieces.com](https://www.activepieces.com) before you plan around one. ## Frequently asked questions Before anyone commits, five questions come up, and each answer is limited to what the pay-as-you-go model implies. Anything that can change, such as promotions or limits, should be confirmed in SiliconFlow's own documentation on the day you sign up. ### Is SiliconFlow free to use? No. The service is metered, so you pay for the tokens you consume, with the rate set by the model you call. Promotional credit or free models may exist at a given moment, but they sit on the pricing page and can change. A budget built on them would break the day they're withdrawn, so cost your workload at the paid rate. Does SiliconFlow offer a monthly subscription? Not as the basis of pricing. Billing is pay-as-you-go, which means the invoice rises and falls with your token volume rather than being a flat fee that covers a fixed allowance. That helps a spiky workload and removes any idle-month cost. It also means a traffic surge shows up directly in the bill. ### Is the SiliconFlow API compatible with OpenAI's SDK? Yes, it follows the OpenAI request format, so existing code usually needs only a new base URL, a new API key and a SiliconFlow model name. That keeps switching cost low, and it works in both directions, so you can move back as easily as you moved in. Test any model-specific parameters, because compatibility with the format doesn't guarantee that every option behaves identically on every model. ### What happens when I hit a SiliconFlow rate limit? Beyond your limit, requests are refused rather than silently slowed, so your client has to handle the error. Build in retries with exponential backoff and a queue for work that can wait. A model that is cheap per token can still be a poor fit if its limit caps your throughput, because limits depend on your account tier and the model. Check the rate-limit documentation for how tiers are assigned and whether they can move down as well as up. Do SiliconFlow credits expire? Treat any credit as expiring until the documentation says otherwise. I haven't verified the expiry terms, so the safe approach is to top up only what your costed monthly workload will use. If you receive promotional credit, find its end date in your account before relying on it. ## Related reading - [Claude API Pricing 2026: Rates for Every Model](https://www.activepieces.com/blog/claude-api-pricing-2026-rates-for-every-model) - [Replicate Pricing 2026: What You Pay Per Model](https://www.activepieces.com/blog/replicate-pricing-2026-what-you-pay-per-model) - [OpenAI API Pricing 2026: Cost Per Model Compared](https://www.activepieces.com/blog/openai-api-pricing-2026-cost-per-model-compared) ## References - [Sovyron](https://sovyron.com/providers/siliconflow/) - [SiliconFlow](https://www.siliconflow.com/zh/pricing) - [SiliconFlow](https://www.siliconflow.com/pricing)The model you pick moves the bill more than anything else.