### Strands Decider 2B as a Sonnet replacement [Strands](https://strandsagents.com/blog) describes Strands Decider 2B as "a small, open source, decision model optimized for fast experimentation, local development, and innovation." Its example presents Decider as a replacement for Sonnet in a task and claims savings from the swap. Treat that as the maker's claim, not your result. The example comes from the team that built the model, on a task they chose, and nothing in it tells you how your own tasks will score. If your steps are narrow decisions, the claim is worth a test. If they need open-ended reasoning, the savings may not carry over, and you'll only learn which by measuring. ## What Strands Decider claims is new Nobody outside the team has reproduced any of the numbers below. They are the Strands team's own, read on 2026-11-11, so they tell you where the maker says it stands and nothing more. ### Strands Decider JevBench results and benchmarks On JevBench, out of 231 tasks, the prior version, v19, solved 167, according to the [repo CHANGELOG](https://github.com/strands-labs/strands-decider/blob/main/CHANGELOG.md). That's a real improvement, but it comes from the maker's own benchmark. The same table lists: - - - - If your constraint is size, that's the trade.  Split by difficulty, Decider 2B looks different, per the [evaluation results page](https://github.com/strands-labs/strands-decider/blob/main/evaluation/results.md). The aggregate hides that cliff. **Roughly four in ten hard tasks fail**, so a workflow with branching logic or messy inputs will sit closer to the third number than the first. | Item | Stated value | Source page | Date read | |---|---|---|---| | v19 JevBench | 167 of 231 | CHANGELOG | 2026-11-11 | | Decider 2B JevBench | 180 of 231 | CHANGELOG | 2026-11-11 | | Easy / standard / hard accuracy | 1.0 / 0.931 / 0.586 | evaluation results | 2026-11-11 | _Prices and plan limits checked against [strandsagents.com](https://strandsagents.com/blog/amazon-saves-millions-replacing-sonnet-with-strands-decider/) and [strandsagents.com](https://strandsagents.com/blog) and [github.com](https://github.com/strands-labs/strands-decider) on November 11, 2026._ The three rows above are the maker's claims; the Gemma 4 comparison scores are in the prose. Without a licence you can't tell whether commercial use is permitted. Without a price you can't cost a pilot. Price and independent benchmarks are not stated on either page, and without outside benchmarks, JevBench remains the maker's own yardstick, so run your own tasks before trusting it. ## Connect Strands Decider to your workflow You can reach Strands Decider through three general building blocks, simplest first, but nothing native exists and none of them has been tested with it. On 2026-11-11 the catalog showed no integration built for it, so each route works only if the maker's interface allows it, and running your own tasks through whichever you pick is how you find out. ### Connect Strands Decider with an HTTP request step If the maker publishes an endpoint that accepts a task and returns a decision, a plain HTTP request step is enough. The first assumption to break is the response shape: if the decision comes back as free text rather than a fixed field, every downstream step ends up parsing prose. Fix it at the boundary by requiring structured output, or by adding one validation step that rejects anything off-schema, rather than patching each consumer. ### Use Strands Decider as an OpenAI-compatible AI step This route needs the maker to expose an OpenAI-compatible chat interface, or your tool to accept a custom provider with a base URL and key. Check tool calling and structured output first, since compatible in name often covers only basic completions. If either is missing, you get a model that answers but can't drive your steps. Switching to Route 1 is cleaner than stacking prompt workarounds on a partial interface. ### Connect Strands Decider through an MCP server This needs the maker to ship an MCP server, or to offer an interface you can wrap in one. It's the most work because you own the tool definitions, the authentication, and the failure handling. Keep the exposed tools narrow: one wrapper per decision type, with typed inputs. A single catch-all tool only moves the mess into the prompt. Whichever route you choose, the connection tells you nothing about quality; that comes from the measurement that follows. It does settle one wiring question, though: whether the Decider connection has to be built twice, once for flows and once for agents. In Activepieces it doesn't, because a integration is an agent tool the moment it's connected. The same integration action that runs as a step in a flow is exposed as a tool schema on the project's MCP server, where Claude, ChatGPT, Cursor or an agent you built yourself can call it. So an HTTP step or provider wrapper for Decider needs no separate catalog to publish to and no export step; a catalog you have to re-integrate for your agents is a second migration. The Integrations Framework and MCP Server documentation describe the mechanism, and packages/integrations in the open source repo shows it. ## Compare Strands Decider cost and speed Strands publishes cost and speed figures for Decider beside Sonnet 4.6, such as 897 ms versus 4,215 ms per call, but **they are the maker's own claims**. Every comparison here rests on the maker's claim, not on a measurement of ours. ### What Strands Decider's savings claim implies A savings claim only means something against a baseline, and self-hosting gives a floor for one. ### Strands Decider self-hosting cost floor [GPU Hour](https://gpuhour.com/gpus/rtx-3090/) lists a 4 vCPU cloud CPU at $0.0272 an hour, which is about $0.65 a day, so a 2B model that tolerates CPU inference costs almost nothing to leave running. 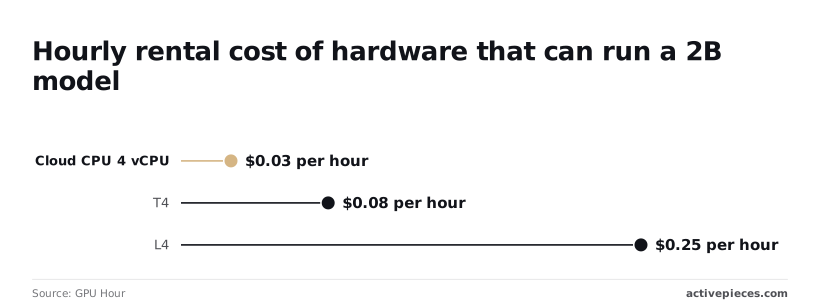 At $0.08 an hour for a T4 and $0.09 for an RTX 3090, you pay roughly $2 a day for each. An L4 is $0.25 an hour, about $6 a day, so it's the first card where idle time becomes a line item. ### Strands Decider cost versus a rented GPU If Decider's a small model, a "cheaper than Sonnet" claim has to survive that comparison with a rented card, not only with an API price. Utilization decides it: a card billed around the clock but busy for an hour a day is expensive per task, whatever the hourly rate. ### Strands Decider cost and speed gaps Strands states cost and speed figures for Decider and for Sonnet 4.6, but they are the maker's own, so an independent comparison can't be made yet. The only evidence for Decider is the Strands team's own release, none independent exists for Sonnet 4.6, and Activepieces has tested neither. Until a team runs both on its own tasks and records cost and latency per run, **the savings claim stays unverified**. The next step is to wire both models into one workflow and measure. ## What to watch next for Strands Decider Check four places on the maker's blog and repository, then run one small trial on your own tasks before changing anything. Until both are done, what you hold is the maker's account of Strands Decider. Claims can shift under you, and the list below shows where. Treat it as a recurring review, because a stale page is the first assumption that will break. - New releases on the repository, since behaviour you measured last week may not be what ships now. - Documentation, especially anything on connecting through general building blocks, because that's the integration path you would depend on. - Pricing or licence details, which decide whether a good trial result is affordable, or even permitted, in production. - Independent results from people with no stake in the release, the only evidence the maker didn't write. Anything these pages don't state is unconfirmed. Note it as unconfirmed rather than filling the gap with a guess. Keep the trial small enough to finish and strict enough to fail. A tool that moves your mess somewhere new hasn't removed it. 1. Pick a handful of tasks your team already runs, and include the hard ones, the cases your current setup gets wrong, because easy cases pass anywhere and tell you nothing. 2. Record today's output as the baseline, so the comparison is against what you ship now. 3. Connect Strands Decider through the general building blocks, not a bespoke path, so the test matches how you'd run it. 4. Run both on identical inputs and score them by one rule, written before you look at results. 5. Log each failure with its cause. A failure you can't explain is a finding, not noise. **Switch nothing until the hard tasks pass.** Only then are the results yours to repeat. ## What Activepieces does about this The article's advice comes down to one thing: connect Decider through general building blocks and measure it on your own tasks. Activepieces is built for that kind of trial. Its open source repo counts 747 integrations, and none of them is for Decider, so the connection is yours to make. You would do it with an HTTP request step, an AI step pointed at a custom provider, or an MCP server, the same three routes described above. That is a limit, and the maker would have to publish an endpoint or an OpenAI-compatible interface before any of them works. What the platform changes is how much you rebuild around the trial. A Decider connection wired once is usable twice. The integration action that runs as a step in a flow is also exposed as a tool on the project's MCP server, so an agent can call the same wrapper without a second integration.  If you run Decider and Sonnet side by side in one flow, you can feed both the same inputs, log each run, and score them by the rule you wrote beforehand. That is the measurement the savings claim has to pass. The code is open source, and packages/integrations in the repo shows how an integration is put together. If Decider turns out to need a wrapper of its own, you can read how the existing ones are written and build it yourself. We have not tested Decider, and we hold no cost, speed or accuracy figures for it beyond what Strands published. So the claims stay the maker's until your own tasks say otherwise. What Activepieces offers is a place to run that test with the hard cases included, without having built a connection you can't reuse. ## Related reading - [What Is Strands Decider? A Small Decision Model Guide](https://www.activepieces.com/blog/what-is-strands-decider-a-small-decision-model-2026) - [Best Data Automation Tools of 2026 for Analytics Teams](https://www.activepieces.com/blog/best-data-automation-tools-of-2026-for-analytics-teams) - [Reverse Logistics Automation Tools for Operations Teams](https://www.activepieces.com/blog/reverse-logistics-automation-tools-for-operations-teams) ## References - [Strands Decider repo CHANGELOG](https://github.com/strands-labs/strands-decider/blob/main/CHANGELOG.md) - [GPU Hour](https://gpuhour.com/gpus/rtx-3090/) - [Strands](https://github.com/strands-labs/strands-decider/blob/main/evaluation/results.md)What breaks first is the assumption of one model per workflow, sized for the hardest step.