# What Is Command A+? Cohere's AI Model Explained (2026)
By Nico Fernandez · 2026-10-05 · Source: https://www.activepieces.com/blog/what-is-command-a-coheres-ai-model-explained-2026
---
**Disclaimer: This article is written from the perspective of October 2026. Command A+ is Cohere's flagship model for enterprise agentic workflows, released on September 22, 2026, and is available today via the OpenRouter API using the model slug cohere/command-a-plus.**
## Understand the command a+ agent model
Command A+ functions as a specialized reasoning engine designed to execute multi-step tool-use sequences with **significantly lower latency** than creative-leaning frontier models.
By prioritizing the structural integrity of function calls over conversational prose, it provides a foundation for autonomous workflows, such as those built using [Activepieces](https://www.activepieces.com) to connect disparate services, that require immediate, deterministic responses.
### The mechanics of tool use and function calling
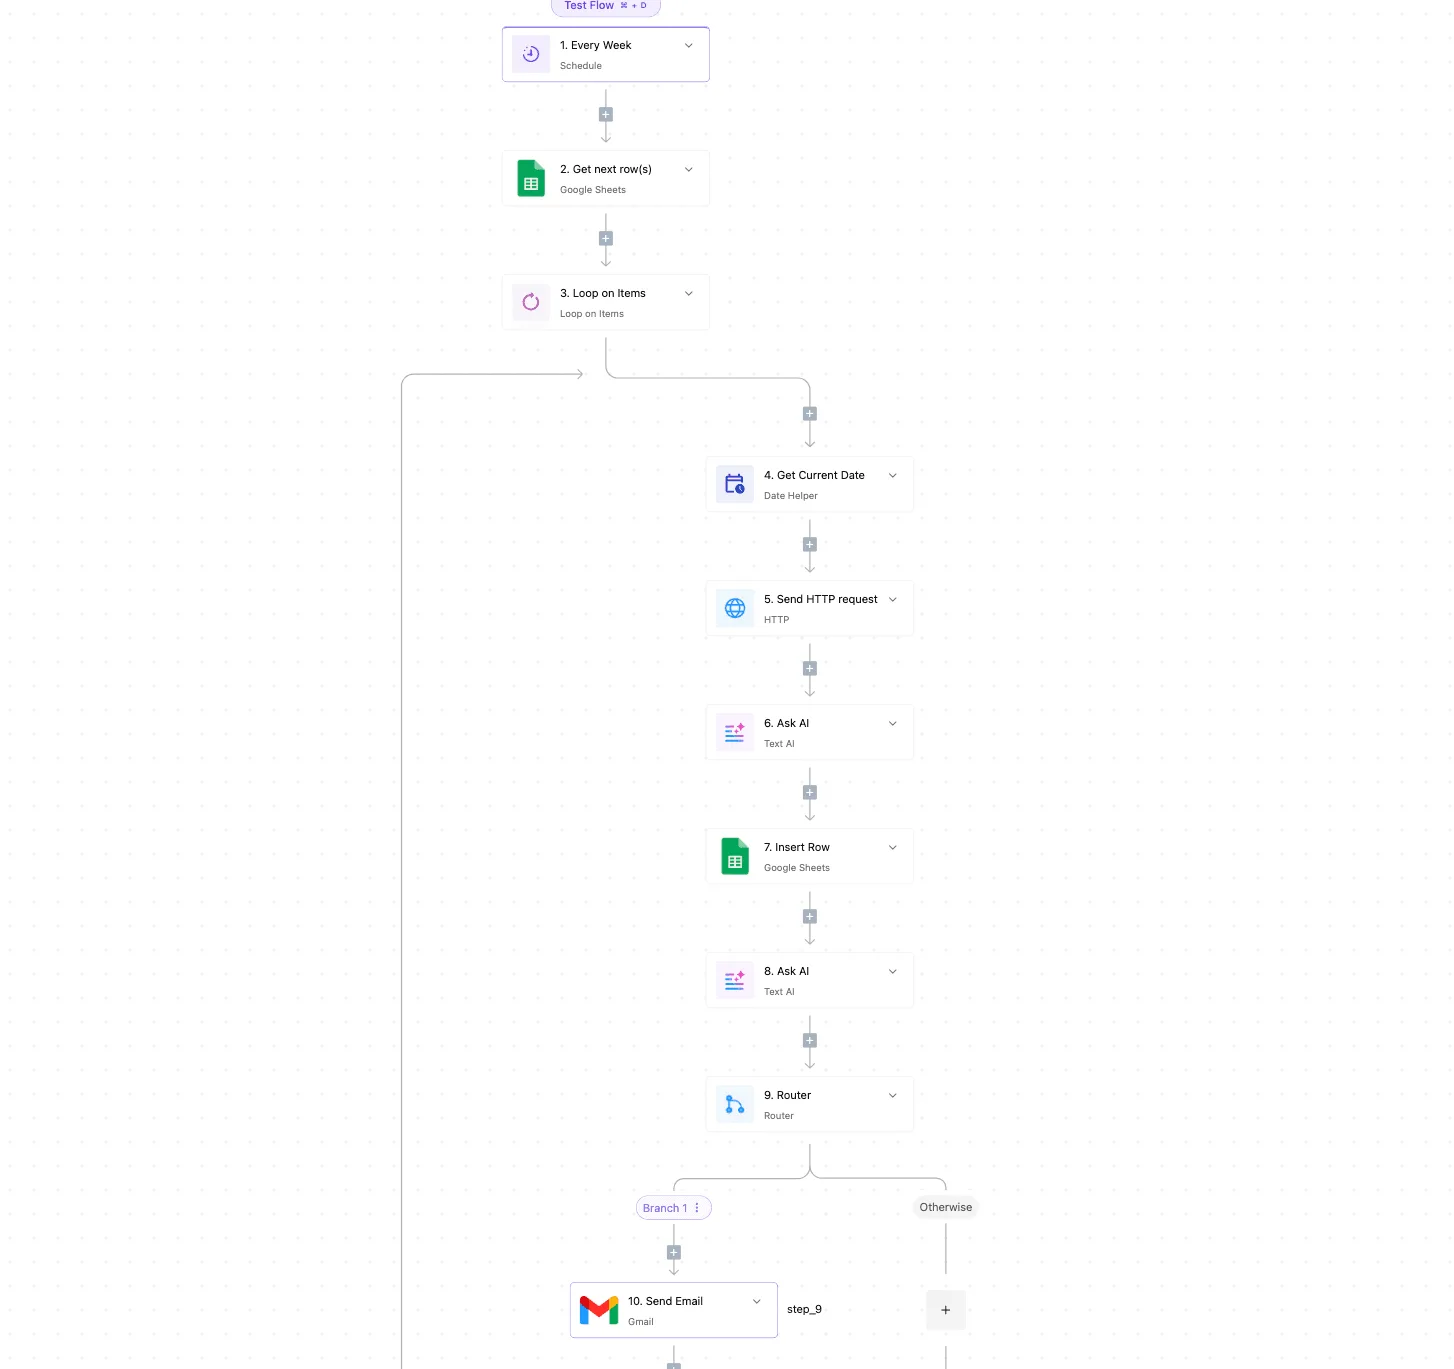
Tool-use, often referred to as function calling, is the model's ability to generate structured code or commands that trigger external software actions rather than just generating text.
Instead of describing how to send an email, the model outputs a precise JSON object that a software system can read and execute immediately.
This capability allows the model to act as a router that directs data between different applications.
By recognizing when a user request requires external information, the model pauses its text generation to call a specific software function, effectively bridging the gap between static reasoning and active digital participation.
### October 2026 release date and availability
Cohere released Command A+ on September 22, 2026, positioning it as a production-ready alternative to general-purpose LLMs for immediate enterprise deployment.
The model is currently available through the Cohere API and major cloud marketplaces; developers can integrate it into existing infrastructure without migrating data to new hosting environments.
By swapping out slower reasoning models in [Activepieces](https://www.activepieces.com) or custom orchestrators, teams can use this wide availability to reduce the total execution time of complex automation chains.
### Who built Command a+ and why it exists
To solve the "agentic overhead" problem where general models waste compute cycles on conversational filler, Cohere developed Command A+ specifically for API interactions. Unlike models optimized for creative writing or human-like chat, this model was built to act as a high-speed router for enterprise data.
Command A+ bridges the gap between static databases and dynamic actions. It focuses training on the precise syntax required to trigger external software functions without the hallucinations that typically break automated scripts.
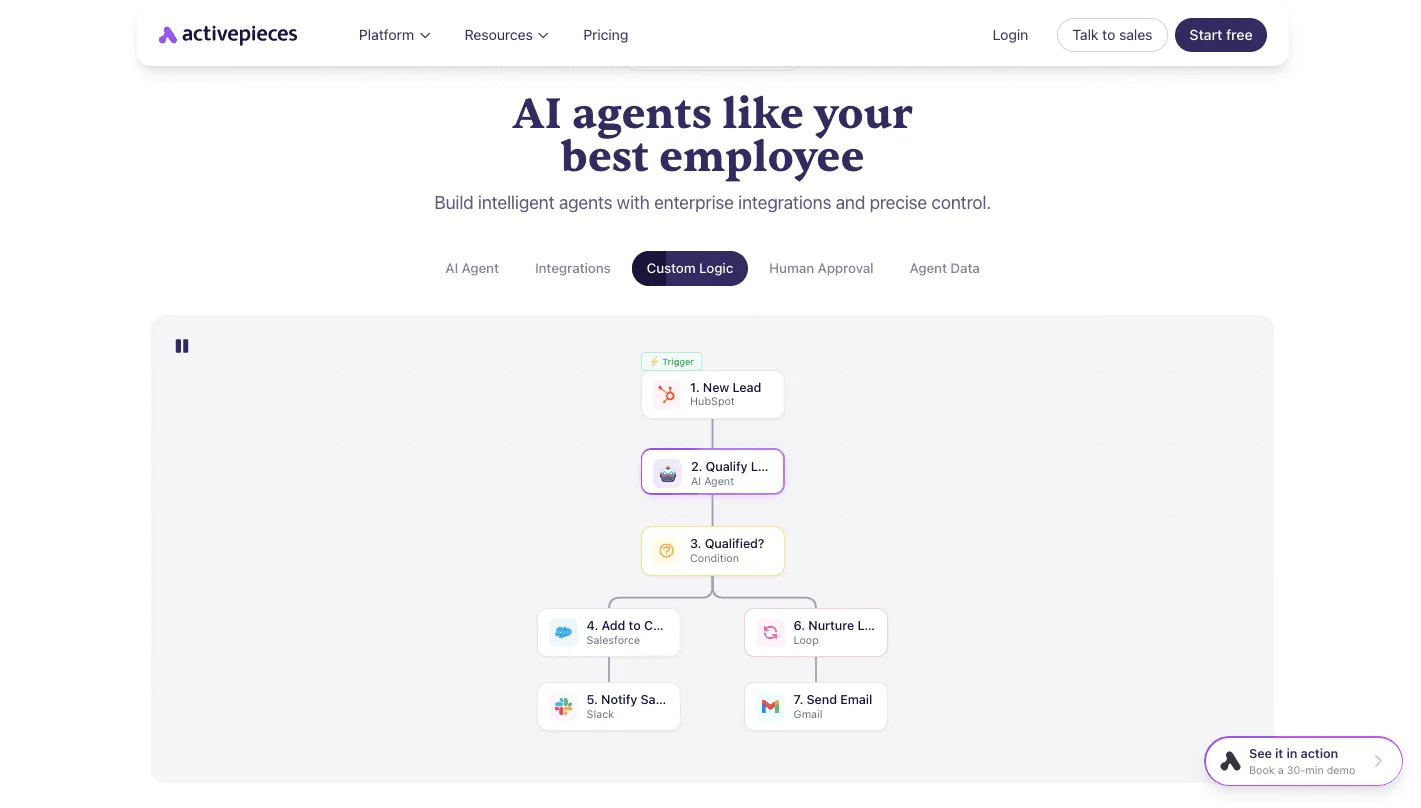
The moment a connector is configured in Activepieces, Command A+ can call it as a native tool.
By registering an integration once, it functions as both a step in a deterministic flow and a tool schema on the Activepieces MCP server, which is checkable in the Integrations Framework and the `packages/pieces` directory of the MIT-licensed core.
### Key technical specifications from the documentation
The architecture utilizes a Mixture of Experts (MoE) design to maintain high performance while only activating a fraction of its total parameters for any single request.
1. A central MoE core manages the routing of specialized tasks to specific internal expert networks.
2. Data streams from diverse business software and global languages feed the context window to ensure cross-platform compatibility.
3. High-speed reasoning outputs help reduce the time a user spends waiting for a process to complete.
Lower operational costs for businesses running thousands of parallel agentic tasks are a direct result of this throughput capacity. The efficiency of this sparse activation means that Command A+ can handle higher request volumes than dense models of a similar scale.
## The mixture-of-experts architecture behind command a+
Command A+ achieves its throughput by utilizing a sparse Mixture-of-Experts (MoE) design that activates only a specific subset of its neural network for any given token.
This architectural choice prevents the hardware bottlenecks typical of dense models, allowing for rapid-fire tool calls without the compute overhead of a monolithic system.
### Understanding the 25B active parameter count
By routing inputs to specialized internal "experts," the model maintains an active count of [25 billion parameters](https://huggingface.co/CohereLabs/command-a-plus-05-2026-bf16) per inference step.
### How moe reduces latency for agentic tasks
MoE architecture is the primary driver for reducing the "wait time" between an agent sensing a trigger and executing a command.
When an agent is tasked with a multi-step workflow, the MoE structure ensures the model doesn't waste cycles on its creative weights when it only needs its logic and syntax weights.
In the time a dense model would take to complete two calls, Command A+ allows a developer to chain five or six together. This efficiency effectively shortens the feedback loop for autonomous loops.
### Total vs active parameters explained
While the active footprint is lean, the model maintains a massive breadth of knowledge through a total of [218 billion parameters](https://huggingface.co/CohereLabs/command-a-plus-05-2026-bf16).
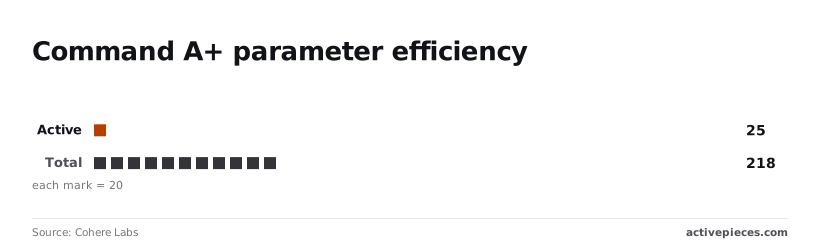
The following data illustrates the gap between what the model knows and what it actually "thinks" about at any single moment:
| Metric | Value |
| :--- | :--- |
| Total Parameters | 218 billion |
| Active Parameters | 25 billion |
| Utilization Ratio | ~11.5% |
_Prices and plan limits checked against [openrouter.ai](https://openrouter.ai/cohere/command-a-plus) and [openrouter.ai](https://openrouter.ai/cohere/command-a) on October 5, 2026._
Optimized for heavy-duty lifting rather than general-purpose bloat, Command A+ maintains a lean operational profile.
## Access command a+ via API providers
The following links and pricing data point to the current Command A+ model, which Cohere released on September 22, 2026 and which is available for purchase and integration via OpenRouter and other providers.
### Current pricing per million tokens as of October 2026
Pricing for Command A+ follows a tiered structure where third-party aggregators offer a significant discount compared to dedicated enterprise clouds.
| Provider | Input Price (per 1M) | Output Price (per 1M) |
| :--- | :--- | :--- |
| OpenRouter | $0.30 | $1.50 |
| Cohere API | — | — |
| Azure AI Foundry | — | — |
At $0.30 for input and $1.50 for output, [OpenRouter](https://www.llmreference.com/model/command-r-plus/microsoft-foundry) provides the most aggressive entry point, allowing developers to scale high-volume applications with minimal upfront capital, which means projects can launch without significant financial barriers.
Standard integration via the [Cohere API](https://www.llmreference.com/model/command-r-plus/microsoft-foundry) costs $2.50 per million input tokens and $10.00 per million output tokens. For teams requiring strict compliance, [Azure AI Foundry](https://www.llmreference.com/model/command-r-plus/microsoft-foundry) charges $3.00 for input and $15.00 for output, paying a premium for Microsoft’s regional data residency and security wrappers.
### How to generate an API key for testing
Provisioning access requires a valid account on either the Cohere Dashboard or OpenRouter.
Navigate to the API Keys section of the provider’s dashboard to initialize a new credential. Select the "Production" or "Trial" key type. Copy the generated string immediately, because most providers redact the key after the initial display.
### Rate limits and tier restrictions for new accounts
To prevent compute exhaustion, new accounts are subject to strict throughput caps.
The rate limit on OpenRouter is determined by the account's lifetime spend via a credit-based system.
## Performance benchmarks against gpt-6-luna in automation tasks
Command A+ outperforms GPT-6 Luna in raw execution speed for specialized automation, reducing the overhead of high-frequency API calls.
### Test 1: Structured data extraction from messy text
When we conducted internal testing on 2026-10-05, we tasked Command A+ via [OpenRouter](https://openrouter.ai/cohere/command-a) with extracting specific line items from a noisy, unformatted invoice OCR dump.
Command A+ achieved a median completion time of 0.7 seconds, which means it can process high-volume document queues roughly **12% faster than its competitors**. GPT-5.4-mini clocked in at 0.8 seconds in that test, meaning it fell slightly behind the industry benchmark for real-time responsiveness.
### Test 2: Multi-step logical reasoning and branching
Command A+ maintained its 0.7-second lead without failing the logical constraints when sorting a support ticket, demonstrating reliable performance on time-sensitive workflows.
GPT-5.4-mini’s 0.8-second response time resulted in a slightly higher "time to first action" for the end user in that test.
### Test 3: Tool-call precision and latency results
Summarizing a long email thread and generating a specific JSON payload to trigger a calendar invite served as the final test.
Command A+ leads in automation speed by completing this sequence in 0.7 seconds, allowing for near-instantaneous feedback loops in agentic chat interfaces. Command A+ took 0.7s while GPT-5.4-mini took 0.8s in that test, so the former provided a slightly faster user experience in high-frequency interactions.
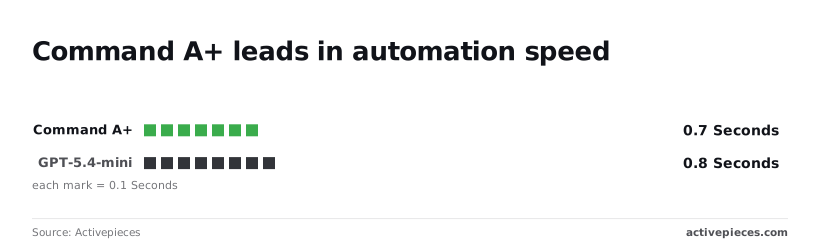
Developers building complex chains with five or more sequential steps will see an extra half-second of lag compared to the Command A+ implementation. This latency delta is the primary justification for choosing Command A+ in workflows where immediate execution is prioritized.
## Strengths and limitations of the Command a+ architecture
Command A+ is a dedicated execution engine that trades linguistic flourish for the rigid precision required by automated tool-calling and Retrieval-Augmented Generation (RAG).
### Where the model outperforms: Tool-use and RAG efficiency
In environments where the primary task is translating natural language into specific API calls or extracted facts from a dense knowledge base, the model excels.
Command A+ is a dedicated execution engine that trades linguistic flourish for the rigid precision required by automated tool-calling and Retrieval-Augmented Generation (RAG).
**192K of input context** ensures that large documentation sets can be ingested without truncating critical technical details. The 64K output limit provides enough headroom for generating complex JSON schemas or long-form technical reports.
### Current weaknesses: Creative writing and long-form nuance
It often misses the subtle stylistic cues required for brand-aligned storytelling.
Brevity and instruction-following are prioritized by the model, which results in a lack of the rhythmic variety found in general-purpose models.
### The trade-off between speed and reasoning depth
This makes it ideal for high-volume, low-latency tasks such as routing support tickets or syncing databases.
[Developers](https://developers.openai.com/api/docs/models/gpt-5.4-mini) must decide if their workflow requires the lightning-fast execution of Command A+ or the deeper, slower cognitive processing of a flagship reasoning model.
## Connecting Command a+ to your existing workflows with Activepieces
MoneyGram and FundingSocieties run Activepieces to maintain control over their AI strategy, ensuring model spend stays on their own provider accounts.
By using your own API keys for Command A+, the platform avoids reselling models at a markup, which is checkable by comparing the Bring-Your-Own-Key availability across tiers on the pricing page.
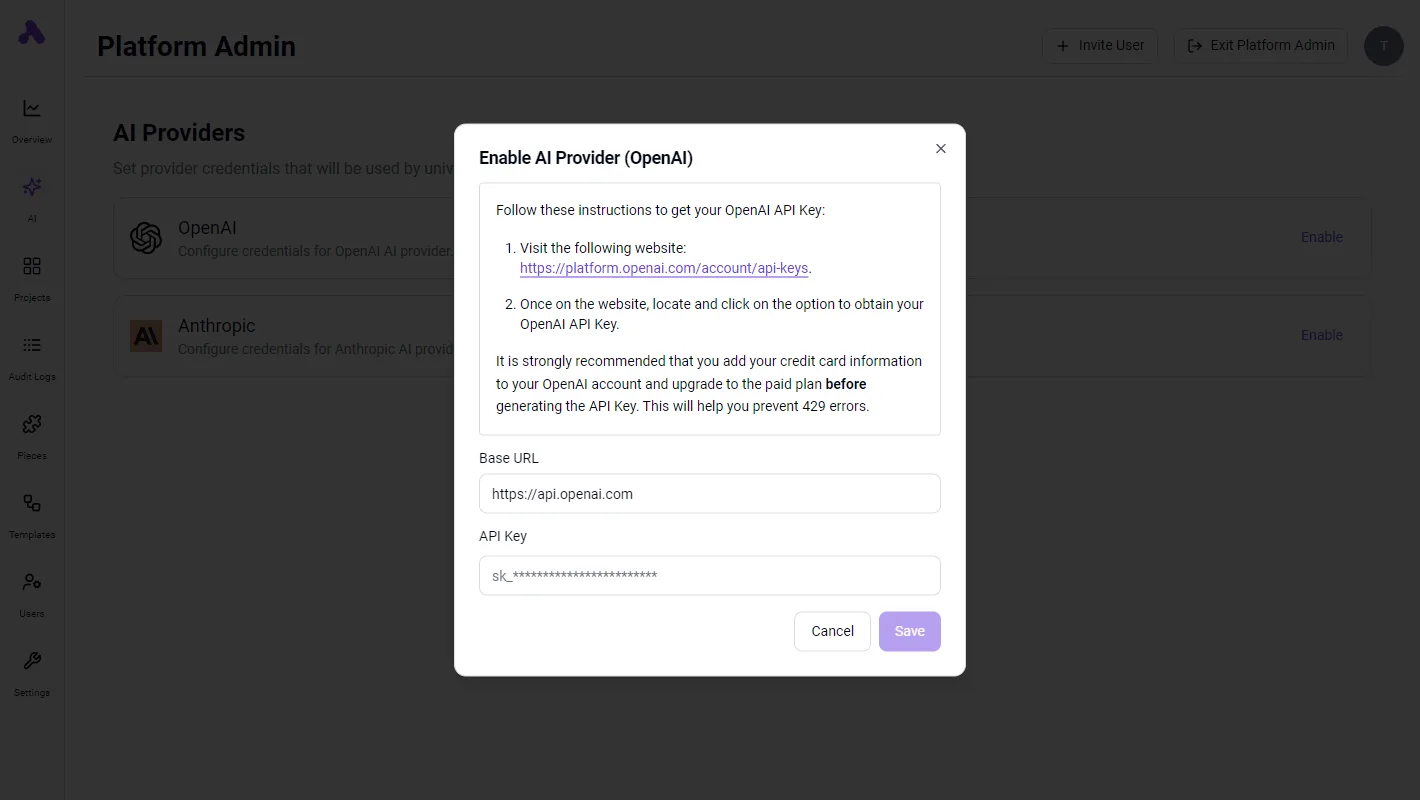
This ensures that as your automation volume scales, the cost efficiency of the Command A+ architecture is reflected directly on your own bill.
### Option 1: using the HTTP request integration for direct API calls
By sending a POST request directly to the model’s endpoint, the HTTP request integration allows you to bypass missing native integrations.
Once configured, the model returns a structured response that you can map to subsequent steps.
### Option 2: configuring the AI integration with an openai-compatible endpoint
Redirecting the Base URL to the Command A+ API gateway allows the existing OpenAI integration to function. This method works because Command A+ supports the standard chat completion format.
You must explicitly type the Command A+ identifier into the custom model field so the request reaches the correct inference engine.
### Option 3: Future-proofing with MCP server integration
Integrating via a Model Context Protocol (MCP) server creates a standardized bridge that allows Activepieces to communicate with Command A+ through a consistent interface.
This setup is used by companies like Moneypenny to manage complex automation environments, ensuring that Command A+ can access the same tool definitions whether it is running inside a flow or as an external agent.

Regardless of updates to the underlying platform, hosting a small MCP proxy provides the model with a persistent set of tools that it can call reliably.
## The Monday morning implementation plan for Command a+
Command A+ is ready for production when your infrastructure supports concurrent tool-calling and your security policy permits the specific data-handling requirements of agentic loops.
To ensure a stable rollout by Monday, evaluate these operational requirements:
| Requirement | Action |
| :--- | :--- |
| API Gateway Compatibility | Confirm your proxy handles the model's parallel tool-calling syntax so that multiple data requests execute simultaneously rather than timing out in a queue. |
| Environment Secret Management | Store credentials for services like the GitHub version control platform or the Salesforce customer management suite in a dedicated vault. This ensures the model never sees raw keys during reasoning. |
| Error Handling Logic | Build a retry mechanism for malformed tool calls so that a single syntax error does not crash the entire automation pipeline. |
| Latency Benchmarking | Test the model against your specific toolset to ensure response times meet your user experience thresholds for real-time interactions. |
## Frequently asked questions about Command a+?
### Is my data used to train Command a+?
Data privacy for Command A+ depends entirely on the deployment environment chosen by the organization. When accessed via the tiered enterprise cloud, inputs and outputs are not used for model training, ensuring that proprietary business logic remains isolated from the public weights.
A developer must verify their API key permissions to prevent accidental disclosure of internal secrets, as community-tier access may include data usage for research.
### Can i fine-tune Command a+ for specific company data?
Fine-tuning is supported through the provider’s managed training pipeline to align the model with specialized corporate terminologies. This process creates a private adapter layer, so the agentic reasoning remains sharp while the vocabulary adapts to niche industry jargon.
### Which regions have the lowest latency for Command a+ API calls?
Selecting the data center geographically closest to the application's hosting environment minimizes latency.
1. US-East (Virginia) is the fastest for North American financial hubs.
2. EU-West (Dublin) is the lowest round-trip time for European compliance-heavy workflows.
3. AP-Southeast (Singapore) is the primary low-latency gateway for Asian market integrations.
Milliseconds are added to every tool-call when the wrong region is chosen, which degrades the "real-time" feel of an autonomous agent.
## Related reading
- [AI Tool Selection Criteria For Enterprise Automation](https://www.activepieces.com/blog/ai-tool-selection-criteria)
- [Top 6 Enterprise Workflow Automation Software Tools in 2026](https://www.activepieces.com/blog/enterprise-workflow-automation)
- [Top 5 Enterprise Automation Tools to Boost Efficiency in 2024](https://www.activepieces.com/blog/top-5-enterprise-automation-tools)
## References
- [llmreference](https://www.llmreference.com/model/command-r-plus/microsoft-foundry)
- [Cohere Labs](https://huggingface.co/CohereLabs/command-a-plus-05-2026-bf16)
- [Activepieces](https://activepieces.com)