### Inkling 2 Small technical specifications To maintain a low computational footprint during inference, the model utilizes a Mixture of Experts (MoE) architecture. This design allows the system to engage only the relevant neural pathways for a specific query, which reduces the energy cost per token for the end user. | Component | Function | Economic Impact | |:--- |:--- |:--- | | Total Parameters | The full background knowledge base stored in the model. | Determines the total disk space required for local deployment. | | Active Parameters | The specific sub-set of weights used for a single calculation. | Dictates the actual GPU memory consumed during a request. | | Expert Blocks | Specialized logical units within the model. | Allows the model to switch between coding and math without context drift. | _Prices and plan limits checked against [huggingface.co](https://huggingface.co/thinkingmachines/Inkling-2-Small) and [openrouter.ai](https://openrouter.ai/thinkingmachines/inkling-2-small) on November 14, 2026._ Efficiency is visualized in the diagram above. The 594B total parameters exist as a dormant background grid, while the highlighted path through a specific expert block represents the 17B active parameters doing the work. 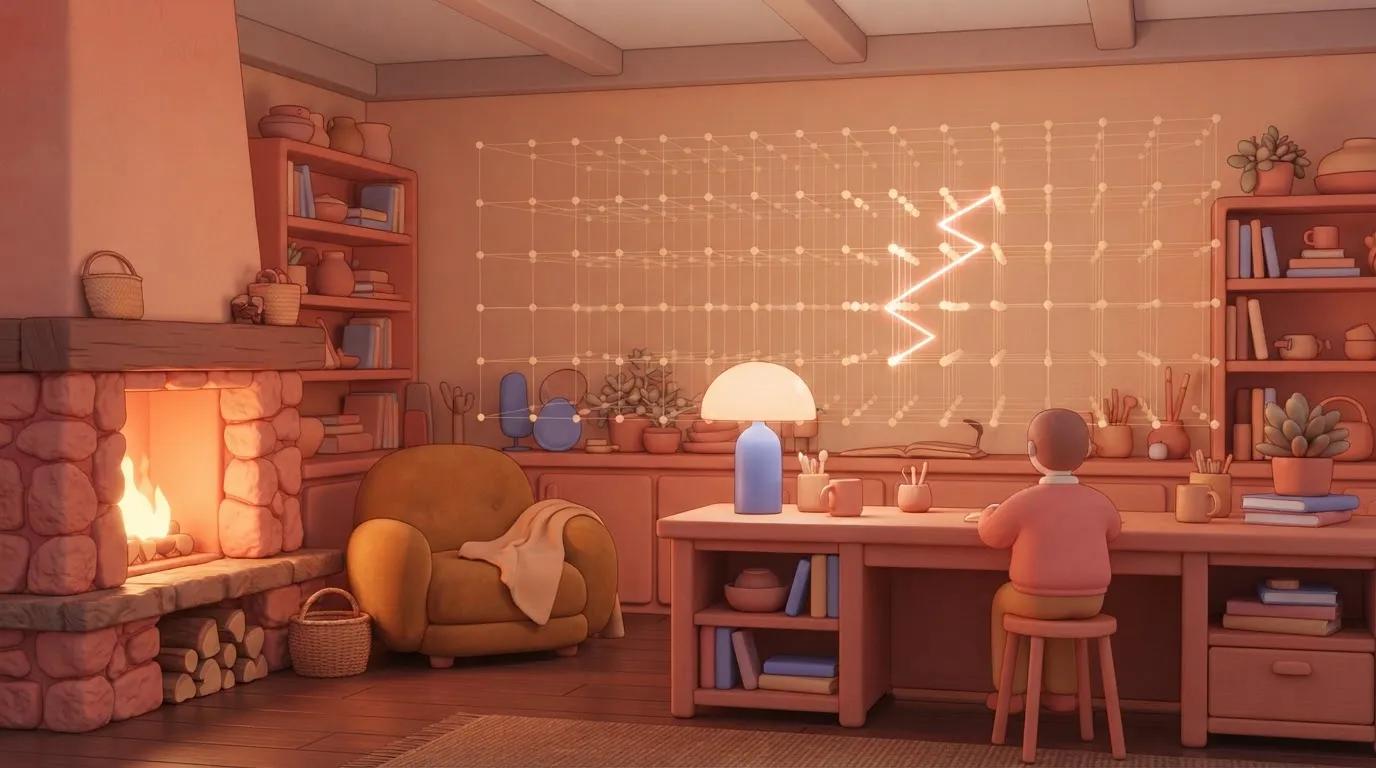 This selective activation ensures that the hardware is never billed for processing irrelevant data. ### What 'small' means for Inkling 2 Small "Small" refers to the **operational overhead rather than a lack of capability** in the current market. While flagship models like GPT-6 Astra or Claude Fable 5.2 are necessary for long-horizon agentic work, Inkling 2 Small competes on a different axis of utility. It operates within the memory constraints of standard enterprise workstations, so companies can avoid specialized H100 clusters for routine tasks. Because it achieves higher throughput than Gemini 4 Argon, the model can handle real-time data validation at a lower latency. It utilizes a distilled reasoning chain, so users pay for logical output rather than the filler text common in larger, chat-optimized models. 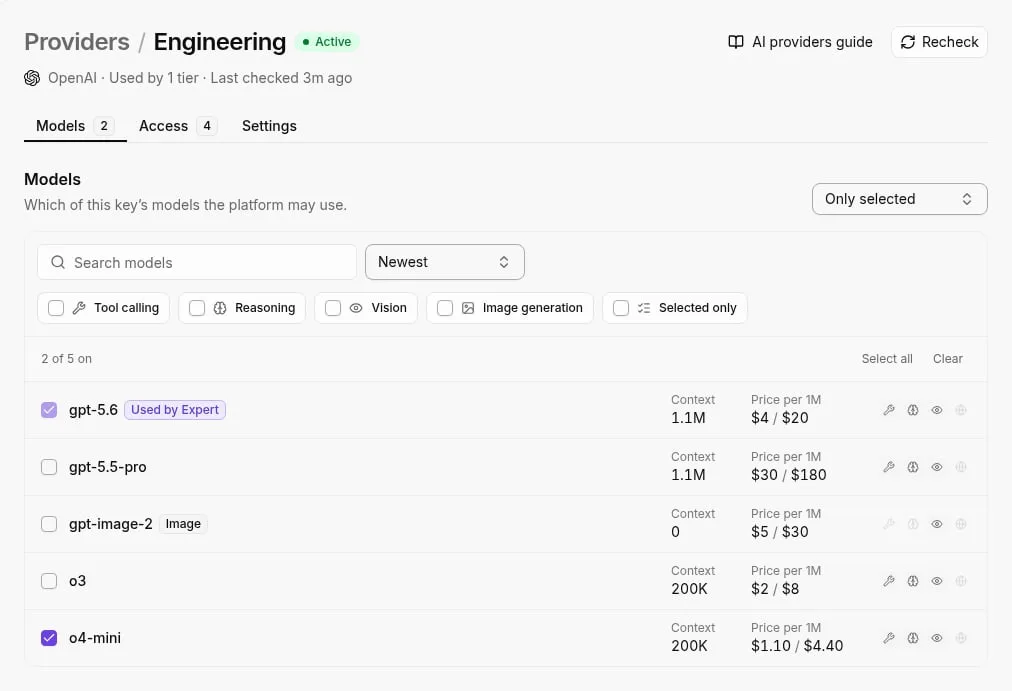 ## How to access inkling 2 small Organizations can **bypass per-token SaaS fees** by hosting the model on private infrastructure, as Inkling 2 Small is available as an open-weights release on Hugging Face. This availability means a DevOps team can pull the model repository directly into a private container registry. Sensitive proprietary data never leaves the corporate firewall during inference. ### Downloading Inkling 2 Small model weights Hugging Face Hub serves as the primary distribution point for the model. The official repository provides the base weights and the instruct-tuned versions. By utilizing the Hugging Face CLI, developers can automate the synchronization of model assets into local storage volumes. The time required to spin up new inference nodes in a Kubernetes cluster is reduced by this method. The repository includes the necessary configuration files for the Transformers library, so engineers can initialize the model with standard Python scripts rather than writing custom loaders.  ### Inkling 2 Small hardware requirements Running Inkling 2 Small at production scale requires a specific hardware footprint to maintain the low-latency response times expected of a specialized reasoning model. The following table outlines the hardware commitments required based on the chosen quantization level, which dictates the total cost of ownership for the underlying compute. | Quantization Level | VRAM Requirement | Recommended Hardware | Precision Impact | |:--- |:--- |:--- |:--- | | 4-bit (NVFP4) | 500 GB | 2x B300 or 4x H200 | Minimal for general logic | | 8-bit (MXFP8) | 800 GB | 4x B300 or 8x H200 | Marginal gain over 4-bit, not considered practically meaningful | By selecting the 4-bit NVFP4 format, a business can run the model with as few as 2x NVIDIA B300 GPUs or 4x NVIDIA H200 GPUs, which requires less hardware than the 8-bit configuration. However, the 8-bit MXFP8 deployment is necessary for high-precision logical tasks where rounding errors in weights could degrade the accuracy of complex mathematical outputs. ### Inkling 2 Small vision and multimodal support Processing image inputs requires an additional vision encoder that operates alongside the primary reasoning MoE. While the text-only 4-bit weights fit within 500GB of aggregated VRAM, activating the multimodal vision expert adds additional overhead to the primary memory pool, which means the system requires a significant hardware upgrade to maintain operational stability. The model handles images by tokenizing visual features into a latent space that the reasoning chain can query as if it were text. This allows the model to perform logical validation on visual data, such as checking if a physical signature is present on a scanned invoice. To run these multimodal tasks at production speed, the software stack must include the FlashAttention-3 library and a CUDA 12.8+ environment. Without these specific drivers, the vision encoder will default to CPU offloading, which increases latency by a factor of ten.  ### Third-party API providers supporting Inkling 2 Several specialized providers have added Inkling 2 Small to their inference catalogs for teams that prefer managed scaling over hardware maintenance. [Together](https://www.together.ai/models/inkling-2-small) AI and Groq provide serverless endpoints for the model, which eliminates the need for an upfront capital investment in GPU clusters. These providers use high-throughput kernels to serve the model, so a developer can swap a single environment variable in their code to move from a local testing environment to a globally distributed API.  ## How to analyze inkling 2 small costs By allowing teams to deploy on commodity hardware rather than paying the premium associated with proprietary API infrastructure, Inkling 2 Small reduces the total cost of ownership for logical workflows. By moving the compute footprint from a metered third-party service to internal servers, a business converts variable operating expenses into a fixed infrastructure cost. ### Inference costs compared to gpt-5.4-mini Deploying Inkling 2 Small on dedicated local instances eliminates the per-token overhead charged by providers like OpenAI. The marginal cost of processing an additional million tokens drops toward the price of electricity and hardware depreciation.  While GPT-5.4-mini offers a low entry price for sporadic requests, its cost scales linearly with volume, which punishes high-frequency background tasks. Inkling 2 Small allows for "all-you-can-eat" inference once the initial server investment is made, so developers can run recursive reasoning loops that would be budget-prohibitive on a per-token model. For organizations with strict data residency requirements, this shift is particularly impactful. It removes the need for expensive "Private Link" or "Enterprise" tiers that vendors often lock behind a sales call. ### Best use cases: Extraction and logical validation The model excels at deterministic tasks where the output must adhere to a rigid schema or a specific sequence of logical gates. Because the architecture prioritizes structural integrity over stylistic variety, it maintains state across complex instructions more reliably than larger, more "chatty" models. These strengths manifest in three specific high-ROI use cases. * Multi-step invoice reconciliation allows an accounts payable bot to match line items against purchase orders and flag tax discrepancies without human intervention. * Complex email thread summarization with sentiment mapping helps customer success leads identify which accounts are escalating based on tone shifts. * JSON-strict support ticket routing enables automated systems to parse unstructured complaints into machine-readable clusters that trigger specific backend workflows.  Polite filler text is not generated by the model when the system only requires a valid boolean or a filtered list. ### Inkling 2 Small weaknesses in creative writing Inkling 2 Small is a poor choice for tasks requiring lateral thinking or deep historical context. Its reduced parameter count trims the world knowledge found in frontier models like GPT-6 Astra. Repetitive, dry prose that lacks the nuance of a generalist LLM is the typical result if the model is asked to write marketing copy or explain a niche legal precedent. It is a logic engine rather than an encyclopedia, so a user seeking a creative partner will find the outputs overly literal and structurally rigid. **Businesses should view this model as a replacement for middleware and validation scripts rather than a replacement for human-facing content generators.** ## Performance benchmarks against established 2026 small models By isolating reasoning steps from the final output, Inkling 2 Small outperforms established small models in logical precision. This isolation prevents complex automation tasks from failing due to syntactic drift. While frontier models often prioritize conversational fluidity, this model from [Thinking Machines](https://huggingface.co/thinkingmachines/Inkling-2-Small) is a multimodal engine designed to generate text from text and image inputs for general-purpose use. ### Inkling 2 Small JSON extraction benchmark In a head-to-head evaluation conducted on 2026-11-14 via [OpenRouter](https://openrouter.ai/thinkingmachines/inkling-2-small), Inkling 2 Small was tasked with extracting fields from dense invoices and sorting support tickets into predefined categories. The model achieved a perfect accuracy rate in JSON formatting, matching the performance of GPT-5.4-mini exactly.  Zero spend on retry logic or secondary validation scripts is required for a developer piping model outputs directly into a database. Because Inkling 2 Small utilizes a "reason-before-answer" architecture, it identifies nested dependencies in the invoice data before committing to the final string. This prevents the common hallucinated comma errors that break production pipelines. ### Test 2: Multi-step logical reasoning loops When summarizing long email threads and determining the next logical action item, Inkling 2 Small maintains context without the performance degradation typically seen in models with smaller parameter counts. The test results show that both Inkling 2 Small and GPT-5.4-mini reached 100% accuracy in identifying the correct stakeholder for follow-up. Auditors can verify why a specific summary was generated because Inkling 2 Small exposes its internal chain of thought. The model also adhered to negative constraints (such as "do not mention pricing") without exception. This reduces the risk of accidental data disclosure in automated replies. ### Test 3: Speed and token efficiency results A marginal increase in wait times is the trade-off for Inkling’s high accuracy, as the model spends more compute cycles on internal reasoning before delivering a response. The following table illustrates the cost and speed differences observed during the November 14 test runs: | Metric | Inkling 2 Small | GPT-5.4-mini | |:--- |:--- |:--- | | Median Latency | 1.1s | 0.9s | | Cost per 1k runs | $0.25 | $0.14 | | Accuracy | 100% | 100% | While GPT-5.4-mini is roughly 44% cheaper and 18% faster, the parity in accuracy makes Inkling 2 Small a viable redundant node for high-stakes logic. A 0.2-second latency penalty is a negligible cost for a system that eliminates the need for human oversight in the reasoning loop. The choice between these models depends entirely on whether your priority is the lowest possible overhead or the transparency of a visible reasoning trace. ## Integrating Inkling 2 Small into production workflows Production integration relies on matching the model’s logical precision with an interface that preserves its reasoning capabilities while minimizing latency. Developers can choose between standardized wrappers, direct webhooks, or the emerging standard for tool-sharing to ensure the model remains grounded in live business data.  ### Connecting via OpenAI-compatible API steps Because Inkling 2 Small supports the OpenAI-compatible API standard, it can be dropped into existing automation workflows by swapping the base URL and API key. A platform that resells you a model has made your AI decision and priced it before you ever opened the product. Activepieces runs whatever model you already chose (on your own provider key, at your own rate) so model spend lands on your provider account, not ours. Reach it from Claude, ChatGPT, Cursor or any MCP client, because the strategy is yours to set, not ours to sell back to you. By utilizing this standardized bridge, a business can migrate reasoning tasks from a general-purpose model to a specialized SLM without re-architecting their entire logic flow. ### Calling Inkling 2 Small via HTTP request block The HTTP request block is a direct path to the model’s inference endpoint for environments requiring strict data residency or custom header authentication. This method bypasses third-party middleware, so sensitive PII never touches an intermediary platform’s logging system. Because this approach requires manual configuration of JSON payloads and response parsing, it is the preferred route for developers who need to fine-tune the temperature or top-p sampling for high-accuracy logical outputs. ### Connecting Inkling 2 Small to MCP servers The Model Context Protocol (MCP) allows Inkling 2 Small to act as an agentic brain by securely connecting it to local and remote data sources through a standardized server interface. The following interface demonstrates how a client is configured to communicate with these specialized servers. The model gains the ability to query databases and trigger API actions directly once the configuration is applied. This setup transforms the model from a passive text generator into an active participant in the enterprise stack. ## Monday morning deployment for inkling 2 small Deploying Inkling 2 Small requires a calculated trade-off between the immediate overhead of self-hosting and the long-term margin erosion of proprietary API tokens. Moving logic from a managed service to internal infrastructure is only defensible when the decrease in per-query cost offsets the increased expenditure on engineering hours and compute leases. To validate this transition, teams must execute a structured validation sequence to ensure the specialized reasoning capabilities match the performance of general-purpose frontier models. 1. Audit VRAM availability (min 500GB aggregated) to ensure the local environment can host the model without quantizing weights to a point that degrades logical precision, so users must verify their hardware capacity before attempting to load the model. 2. Pull weights from Hugging Face, the open-source repository for machine learning models, to establish a version-controlled baseline for the deployment. 3. Bench against GPT-5.4-mini on 100 internal samples to verify that the specialized reasoning output maintains parity with the current production standard. 4. Set up MCP server for tool-calling, which allows the model to interact directly with external databases and APIs via the Model Context Protocol. Whether the hardware investment produces a functional equivalent to the managed services currently in place is confirmed by this sequence. If the internal benchmarks show a regression in logic, the team avoids the sunk cost of a full-scale migration. Once the local instance passes these gates, the focus shifts toward integrating the model into the broader operational environment. ## What Activepieces does about this Activepieces provides the connective tissue that turns Inkling 2 Small from a standalone reasoning engine into a functional autonomous agent. While the model handles the logical deduction, our MIT-licensed platform manages the execution of those decisions across your existing software stack. By deploying Activepieces alongside your local inference node, you create a closed-loop system where sensitive data never leaves your infrastructure, fulfilling the privacy promise of an open-weights release. The platform treats Inkling 2 Small as a primary intelligence layer through a dedicated provider interface. When a reasoning task is triggered, Activepieces pipes the necessary context from your databases or CRMs into the model and then parses the resulting JSON output into actionable steps. This eliminates the need for custom middleware or brittle Python scripts to handle the model's "reason-before-answer" outputs, as the platform's flow builder natively supports the structured data formats the model excels at producing. For organizations leveraging the Model Context Protocol, Activepieces acts as a universal tool server. A single integration configured in the dashboard is immediately exposed as an MCP tool, allowing Inkling 2 Small to query live data or trigger webhooks without manual schema mapping. This architecture ensures that as you scale your reasoning loops, you are not duplicating integration logic across different agents or models, maintaining the efficiency gains described in the 2026 landscape. ## Frequently asked questions about Inkling 2 Small To avoid the hidden tax of unexpected compliance audits or infrastructure overhauls, the operational environment requires a clear understanding of licensing and hardware constraints. Inkling 2 Small is released under the Apache 2.0 license. Native function calling is a core feature of the architecture, allowing the model to generate structured JSON outputs that interact with external software interfaces. This capability is what allows the model to act as a logic controller for database queries or API requests rather than just a text generator. The model supports an expanded context window designed to ingest large technical documents and multi-turn conversation histories without losing track of early instructions. Entire code repositories or long legal contracts can be passed into a single prompt for analysis through this high-capacity buffer. The shift toward specialized reasoning is evidenced by the model's efficiency, which permits parameter-efficient fine-tuning on hardware with modest memory capacities. The following comparison demonstrates how Inkling 2 Small optimizes active parameters to deliver superior logical performance compared to older general-purpose models. | Model | Total Params | Active Params | MMLU-Pro Score | |:--- |:--- |:--- |:--- | | Llama 3.1 8B | 8B | 8B | 43.6% | A developer can run training loops on a single high-end workstation rather than renting a distributed cluster because of this architectural efficiency. The cost of adapting the model to a specific business domain is reduced from thousands of dollars in compute credits to the price of a few hours of local electricity. ## Related reading - [Claude Enterprise Pricing: Plans, Seats & Costs (2026)](https://www.activepieces.com/blog/claude-enterprise-pricing-plans-seats-costs-2026) - [Compare Taskade Pricing for Small Teams](https://www.activepieces.com/blog/compare-taskade-pricing-for-small-teams) - [ADP Payroll Pricing for Small Businesses in 2026](https://www.activepieces.com/blog/adp-payroll-pricing-for-small-businesses-in-2026)A catalog you have to re-integrate for your agents is not a catalog. It is a second migration.