Constraint first: one run each, default settings, no tuning. We ran [Ripple-65B Preview](https://openrouter.ai/ricursiveai/ripple-65b-preview) (ricursiveai/ripple-65b-preview on OpenRouter, a hosted API that routes requests to many models) and openai/gpt-5.4-mini on identical inputs. 1. Sort a support ticket into a category. 2. Pull fields from an invoice. 3. Summarise an email thread. Because each output was checked against a known answer, anyone holding the same inputs can reproduce a pass or fail. ### Results, speed and cost per task All three tasks have recorded timings, so the figures below report speed and cost across those runs. Ripple-65B Preview had a median of 0.7 seconds at $0.000025 per task, and openai/gpt-5.4-mini a median of 0.8 seconds at $0.000139 per task. Ripple was faster and far cheaper per task, so on this evidence price isn't the obstacle to a trial. 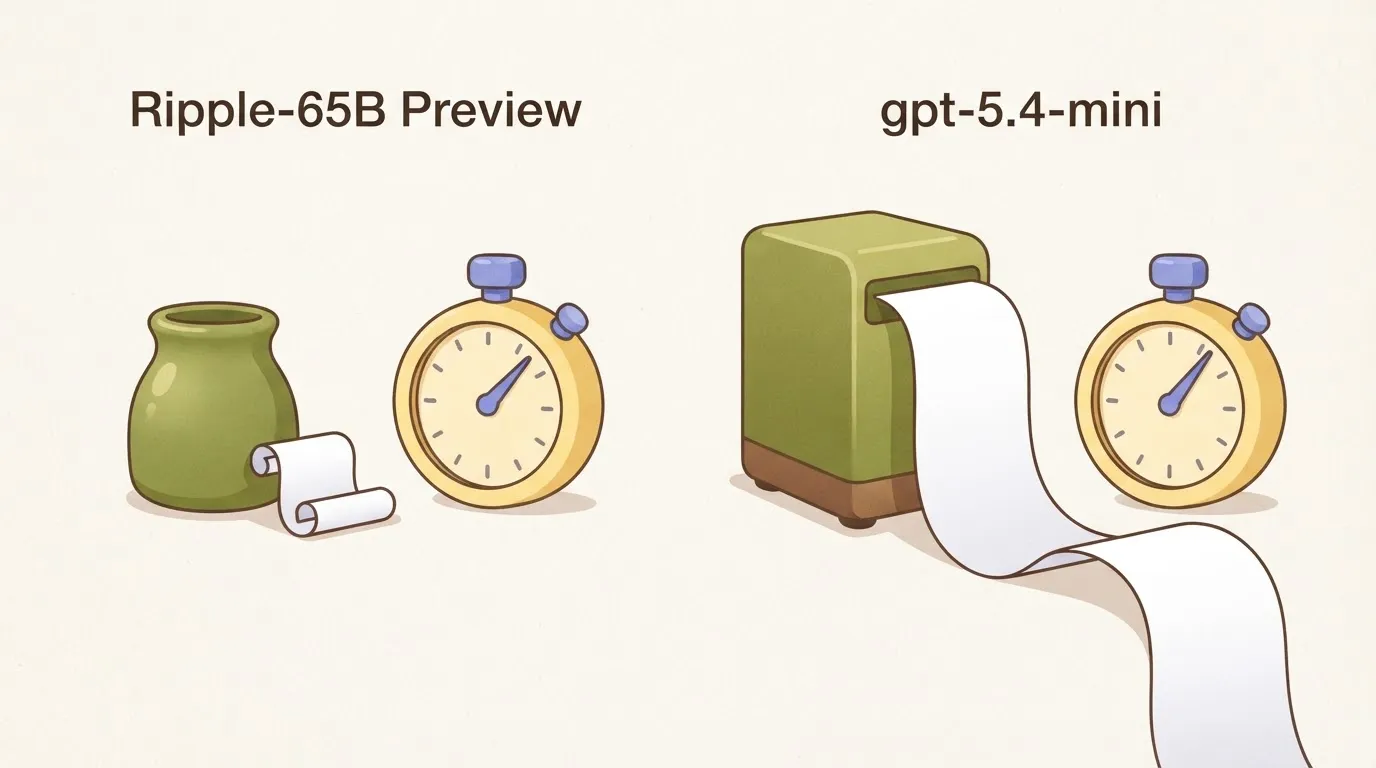 Don't act on the 0.1-second gap in speed, since it could vanish on a different day or network path. The cost gap is the figure to carry forward: at these prices, a bounded trial costs almost nothing. ### What our three-task Ripple-65B Preview test shows For routine extraction and sorting, three tasks with one run each is a small, indicative test, not a benchmark. It isn't enough to show it holds up on your documents, your volumes or your worst-case inputs. Run it once and you learn nothing about variance between runs, and a preview model can change without notice. Repeat the test on your own data before you trust any figure here. ## Ripple-65B Preview compared with established coding models Of the four models below, Ripple-65B Preview is the least documented, which is why your own test has to fill the gaps the maker has left. The table lists what each vendor states on five points; "not stated" marks a gap. | Model | Licence | Access route | Cost model | Maturity | Quality evidence | |---|---|---|---|---|---| | Ripple-65B Preview | Open; Apache 2.0 | Weights on Hugging Face (BF16, NVFP4) | Not stated | Preview | 80.52 on Terminal-Bench 2.1 (maker-reported) | | GPT-6.1 Sol | Closed | Hosted | Not stated | Established | Not stated | | Claude Sonnet 5.5 | Closed | Hosted | Not stated | Established | Not stated | | Mistral Large 4 | Open-weight; terms not stated | Not stated | Not stated | Established (v26.10) | Not stated | With no quality evidence in three of the four rows, the table can't rank them; any position here reflects incomplete data rather than genuine performance differences. No price in the table is firm enough to budget against until you check each vendor's current rates. Try Ripple when the trial is bounded and your current model stays in place. [SlashData and Mozilla](https://www.slashdata.co/blog/open-models-production-gap) report that 50% of developers use both open and closed models, so a second model beside your first is ordinary practice. 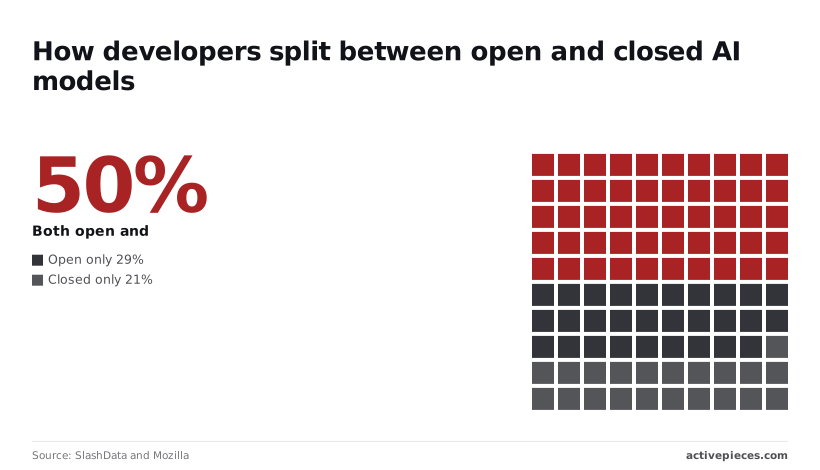 Another 29% use open models only, so running one without a hosted fallback is a minority choice you should make deliberately. ### When to stay with a hosted model Stay hosted when the workload is in production or has an audit window. The same SlashData and Mozilla survey finds 21% of developers use closed models only, and they get a stated price and an established track record. A hosted model such as GPT-6.1 Sol publishes a per-token price, so you can forecast spend before the first request. Ripple-65B Preview's maker states no price for the weights, so a self-hosted cost has to be estimated separately. ## Connecting Ripple-65B Preview to workflows in Activepieces  As of 2026-11-08, Activepieces, the open-source AI automation platform, has no Ripple-65B-specific integration, so you reach the model through three general routes, ordered here from simplest to most involved. That doesn't imply native support, and the unforecastable cost above applies on every route. Whichever route you pick, you must host the model or reach an endpoint that serves it. [Activepieces](https://www.activepieces.com) doesn't choose that model for you, whereas a platform that resells you a model has settled your AI decision and its price before you open the product. With Bring-Your-Own-Key, available on the paid tiers, Ripple would be billed to your own provider account at your own rate, and the strategy stays reachable from Claude, ChatGPT, Cursor or any MCP client, so you're never locked into one vendor's pricing or interface decisions. Settle where the endpoint runs, and whether the workflow runner can reach it, before you build anything.  ### Route 1: HTTP request step Add an HTTP request step that sends a POST to your endpoint and passes the response to the next step. It needs no provider setup and nothing beyond the endpoint's URL and its authentication.  You can run the same request by hand from a terminal first, which makes Route 1 the easiest to reproduce. You write the request body and parse the reply yourself, so keep the test workflow small. ### Route 2: AI step with a custom or OpenAI-compatible provider Activepieces works with any major model and with your own provider key (Bring-Your-Own-Key, from the paid tiers up), so Ripple usage would bill to your own provider account. This is cleaner for prompts, and swapping the model later becomes a settings change rather than a rebuild. Only if the server you host actually implements that format does the provider route work. Confirm that against your own deployment, not against launch material. ### Route 3: MCP server Wrap the model, or a task built around it, in an MCP server, the protocol that lets an agent call external tools, and you have the third route. It takes the most work, since you build and run that server as well as the model endpoint. Only if you want an agent choosing when to call Ripple-65B does the MCP route make sense. A bounded trial doesn't need that. Start with Route 1, and move up only if the trial justifies it. ## Testing Ripple-65B Preview safely in one day If you hold to six steps in order, Route 1 fits in a single working day, and none of the steps touches production. The list sets the sequence, and each step leaves a written record you can hand to whoever approves the next stage: 1. Read the model card and the licence. 2. Pick three low-risk tasks. 3. Run them against your current model. 4. Record quality, speed and cost. 5. Keep a human check on every output. 6. Set a recheck date for the maker's page. The three parts below cover the constraints behind each step. ### Checks before downloading Ripple-65B Preview Because the card and licence are the only maker-stated facts you can verify without running anything, step one comes first. Check what the licence permits for your use, what the card says about training data and known limits, and what "Preview" commits the maker to. Save a copy of both pages; it shows what you read on the day. ### Run your own Ripple-65B Preview three-task comparison Choose tasks you already do, where a wrong answer costs little: internal summaries, draft replies, reformatting. Run identical inputs through Ripple-65B Preview and your current hosted model. For each, write down quality, speed and cost in the same sheet, so a gap in one column isn't excused by another. Before anything leaves the test, a person reads every output, because a preview model's errors aren't yet characterised. Record the result as a trial finding, not a verdict. Then put a dated reminder to reread the maker's page, since a preview can change terms, weights or behaviour between your test and your decision. Only a repeat of the same three tasks justifies moving up from Route 1. ## Frequently asked questions **Is Ripple-65B Preview free to use?** Yes for the weights: they are free to download and use, because the licence is Apache 2.0, but hosted use is billed per token. The maker states a hosted price. A self-hosting cost isn't stated, so you carry the hardware and power bill yourself and must price it before comparing it with the hosted rate. ### Can I run Ripple-65B Preview on my own hardware? Yes, if your machine meets the maker's stated memory requirement. Check that figure first, because the quantised build and the full-precision build need very different amounts. The hosted route on OpenRouter lists the same context window as the maker's own page., so a long-document test run there doesn't prove what the weights can do locally. Test on the setup you intend to keep. ### Production readiness **Is Ripple-65B Preview production-ready?** No. It carries a preview label, and no independent benchmarks exist. Every quality claim therefore comes from the maker or from your own small test. Until a third party reproduces the results, treat it as a trial candidate. Don't use it as the sole model behind anything that has an audit or uptime obligation. ### API compatibility **Does Ripple-65B Preview work with an OpenAI-compatible API?** Not stated in the maker's material I relied on. Don't assume it. Send one chat request through your existing client library with only the base address and model name changed. If the response parses, you have your answer. If it fails, you have lost minutes, not a sprint.  ### Rechecking for changes **How often should I recheck Ripple-65B Preview's page for changes?** Recheck before every trial run and whenever a new version tag appears. Preview models change licence terms, memory needs and hosted limits without much notice. Save a dated copy of the page at the start of the trial so any later difference is something you can show. ## Related reading - [DynamoDB Pricing Guide: Costs and Tips (2026)](https://www.activepieces.com/blog/dynamodb-pricing-guide-costs-and-tips-2026) - [Self-Hosted LLM: Hardware, Cost, and Setup Guide for 2026](https://www.activepieces.com/blog/self-hosted-llm-hardware-cost-and-setup-guide-for-2026) - [Ripple 65B Preview: Pricing, Speed, and Test Results](https://www.activepieces.com/blog/ripple-65b-preview-pricing-speed-and-test-results) ## References - [Hugging Face (Ricursive Intelligence)](https://huggingface.co/ricursiveAI/Ripple-65B-Preview) - [SlashData and Mozilla](https://www.slashdata.co/blog/open-models-production-gap)Until you measure tokens, latency and cost on your own tasks, any such claim is marketing and not an input to a budget.