Muse Ember: Meta's New AI Model Explained (2026)
Nov 9, 202611 min read
Muse Ember is a new AI model released by Meta and announced in a post on its research site, research.meta.ai/blog/muse-ember. Everything stated here as fact comes from that one page, apart from the test results, which are from our own run.
Meta's new AI model Muse Ember
Muse Ember release date and announcement
If you want to know what exists, the maker's post is the primary record, since Meta presents Muse Ember as a model it put out itself.
A launch post describes what the maker wants you to see, so treat it as a list of claims to check, not as results. For an automation team, the question's whether the model does your task at a price you can carry.
In Activepieces, a model's one step among several. The canvas below shows four numbered steps, with the "Ask AI" step selected and its configuration open on the right, set to Perplexity's sonar-pro.
Only that one step names a model, so a swap means changing that setting, not rebuilding the flow.
Next, the integration runs Muse Ember against gpt-5.4-mini in that kind of step.
I read the Meta page on 2026-11-09. Anything the page says could have changed since then, so recheck it before you plan around it. Anything not on that page isn't asserted here. The rest of the integration uses measurement, not Meta's wording, to decide.

Everything below works on Activepieces' free plan. Start without code or a credit card.
Model changes for automation teams
If your workflows call a model, a new model matters to you. Every AI step in a workflow runs on some model, and swapping that model changes what the step delivers on your tasks, not on the maker's demos.
Where a model sits inside an automated workflow
Strip a workflow down and it's a trigger, a run of actions, and somewhere in the middle a step that sends text to a model and maps the reply into a field.
That step might classify a support ticket, pull a total off an invoice, or draft a response.
To the trigger and the downstream field mappings, it makes no difference which model answered, as long as the reply keeps the shape they expect. The model's the engine of that one step.
That makes a swap easy to attempt, and easy to get subtly wrong.
What to check before switching to Muse Ember
Swapping the model behind a step moves the following, and a launch page can't tell you how any of them land on your inputs:
- Output quality on the task: whether the answers are as right as before, in the format the next step expects.
- Seconds per run: how long the step holds up everything queued behind it.
- Cost per run: what each execution adds to the bill once the workflow runs at volume.
Run the same real inputs through your current model (for a small, fast OpenAI model today, GPT-6 Luna) and through Muse Ember, then compare all three. If one improves while another gets worse, the swap's a trade-off you have to price, not an upgrade.
What Meta states is new in Muse Ember
Meta describes Muse Ember as its smallest and most efficient model. It's built for complex reasoning execution and repetitive agent work such as tool calls, coding subtasks, routing, extraction and long document parsing, per its research blog.
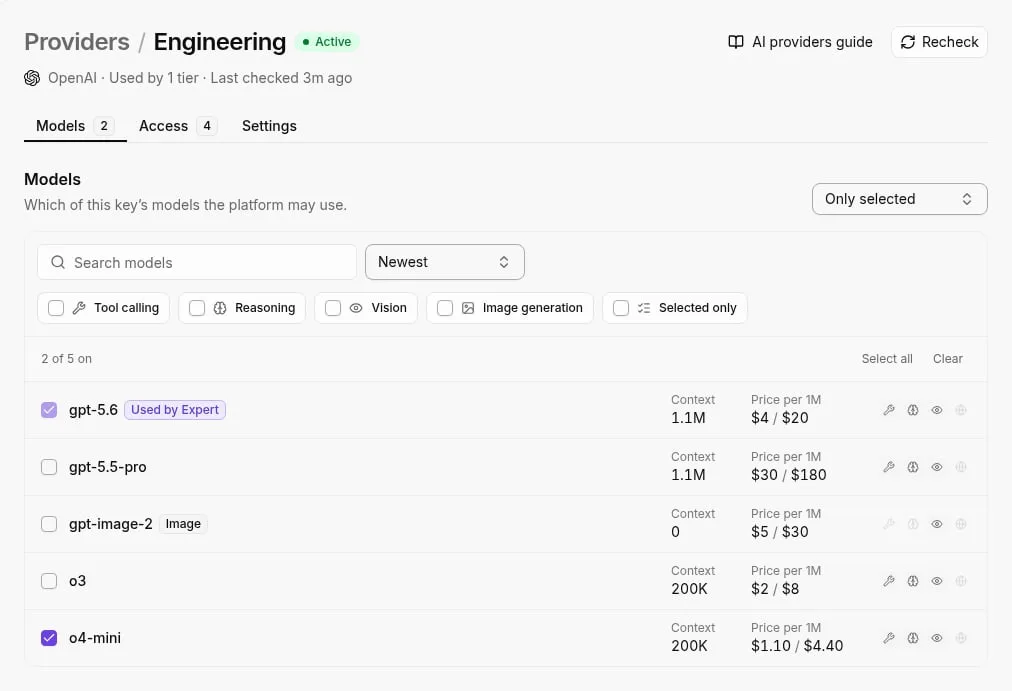
Every figure below is a stated spec, dated 2026-11-09, not a measurement.
Capabilities the maker states
Against 400,000 tokens for gpt-5.4-mini, the developer docs give Muse Ember a context window of 1,048,576 tokens. That's about 2.6 times the input, so a long document can go in whole without chunking.

Max output's 524,288 tokens against 128,000, about four times, so a large extraction can come back in one call. Neither figure says the model uses that room well.
To see how to call it, go to the docs page, which should list the access routes. This article carries them in the table above, but check that page before planning the swap.
Here is what a quote needs, and where this article has no figure.
| What the page states | The figure | Note |
|---|---|---|
| Model ID | muse-ember-1.0 | Stated on Meta's page |
| Access routes | Muse Code and Meta Model API | Stated on Meta's page |
| Responses API | Supported | Confirmed on Meta's page |
| Input price | $0.10 per million tokens | Stated on Meta's page |
| Cached input price | $0.004 per million tokens | Stated on Meta's page |
| Output price | $0.50 per million tokens | Stated on Meta's page |
Meta's page states the prices, so the test logs tokens per task to let you work out the cost.
How Activepieces handles a new model
A platform that resells you a model has chosen it and priced it before you open the product. Activepieces runs any major model, or your own provider key, so spend lands on your provider account at your rates.
A model that's new this week is a change to one step's setting, not a rebuild of the flow.
The dated pull request or integration page
To let platform admins connect their own keys, pull request 17037 adds Meta, alongside NVIDIA.
It points at the Meta Model API (api.meta.ai/v1) through the Responses API with store: false, which asks the API not to keep responses, a sensible default when test prompts contain client data.
19 provider types appear in the Activepieces provider setup guide. Twelve are model makers, so most connections run on the maker's own key. Four are cloud platforms, which means billing through an existing cloud account.
Two are gateways, one key fronting many models. One's OpenAI-compatible, the fallback for any endpoint speaking that protocol if a model never gets its own entry.
Using it in a workflow today
An admin adds the Meta key once, and the Ask AI step can then select it.
The "Test Flow" canvas below runs weekly, reads Google Sheets rows in a loop, and calls Ask AI at steps 6 and 8, which are the two places to compare gpt-5.4-mini against a Muse model.
For the cost comparison, write per-task results at step 7, Insert Row.
Easier to see it running than to read about it: set it up free, no card.
Our test of Muse Ember against gpt-5.4-mini
On 2026-11-09 Muse Ember got all three automation tasks right, but gpt-5.4-mini finished each one faster, so the question for a swap's whether accuracy is worth the wait.
We ran meta/muse-ember on OpenRouter at default settings, which reason before answering, against openai/gpt-5.4-mini. Each model sorted a support ticket, pulled fields from an invoice and summarised an email thread. Every output was checked against a known answer.
On 2026-11-09 Muse Ember got all three automation tasks right, but gpt-5.4-mini finished each one faster, so the question for a swap's whether accuracy is worth the wait.
Muse Ember vs gpt-5.4-mini test results
Here are correctness and seconds per task. Muse Ember's reasoning shows up as time, and the gap grows with task length, per the test record.
| Task | Muse Ember result | Muse Ember seconds | gpt-5.4-mini seconds |
|---|---|---|---|
| Ticket sort | Correct | 1.3 | 1.0 |
| Invoice fields | Correct | 3.4 | 1.0 |
| Email summary | Correct | 3.7 | 0.8 |
| Total | 3 of 3 | 8.4 | 2.8 |
0.3 seconds is all the ticket sort costs extra, which a queue won't notice. Invoice fields add 2.4 seconds and the email summary 2.9, so across the set Muse Ember takes three times as long.
That matters in a step a person waits on, and barely at all in an overnight batch.
Treat this as indicative, not proof: three tasks, one run each, and a single anomaly in any run could account for the entire pattern, so you need additional runs to validate your concern.
Seconds depend on load at the time, and a different prompt could move either model's result.
Re-run your own ten worst tickets before changing anything.
Muse Ember vs gpt-5.4-mini cost and speed
Your ten worst tickets give you the timings. The price and speed comparison with gpt-5.4-mini only holds once each figure carries its source and date, and no such ranking is claimed here.
Take per-token prices only from each vendor's own pricing page, and write the date you read it beside the figure. Prices change, so an undated number tells you nothing about what you'll be billed.
Where a page leaves out the context window or the access route, record that as a gap. Don't fill it from a reseller's listing.
Muse Ember and gpt-5.4-mini speed and cost
Each column below rests on a source. Take from it that price comes from the vendor, speed comes only from your own run, and gaps stay visible.
| Column | Muse Ember | gpt-5.4-mini |
|---|---|---|
| Input and output $ per 1M tokens | Maker's page | OpenAI's page |
| Median seconds in our test | Our run | Our run |
| Context window | Maker's page | OpenAI's page |
| Access route | Maker's page | OpenAI's page |
| Check date | Date read | Date read |
| Gaps | Anything the page omits | Anything the page omits |
Multiply the listed price by the tokens your tickets actually use, then divide by tasks completed correctly. That gives a cost per finished task, which's the figure to swap on.
Muse Ember pricing changes to watch
Watch the maker's pricing page and the provider listing inside your automation platform. Those are the two places where your cost per finished task can change without any workflow edit on your side.
Each of these is checkable, so look at the source rather than a summary of it:
- The maker's pricing page, for any change to input or output rates, since either one moves your per-task cost.
- The model identifier muse-ember-1.0, to see whether a newer version replaces it, because a swapped identifier means your test no longer describes what runs.
- The maker's stated rate limits, since a cap that throttles a batch job turns a cheap model into a slow one.
- Your platform's release notes, for changes to how it handles Meta as an AI provider, such as which models it lists and which fields it passes through.
One real task run on both models will settle the swap where launch claims won't, and it takes under a day.
- Pick one real task from a workflow you already run, with an input you can reuse.
- Add Meta as an AI provider in your automation platform with your own key.
- Run the task on muse-ember-1.0 and save the output.
- Run the same input on your current model, gpt-5.4-mini.
- Compare the result, the seconds each run took, and the cost of each.
Whichever model wins on those three lines, for your task, is the one to put in the workflow.
Frequently asked questions
The model that wins your three-line test answers most of what follows, and where the findings are silent, the answers below say so.
Is Muse Ember free to use? Check the maker's page. It's the only pricing source here, and I won't guess past it. Price per task's one of your three lines, so measure it on your own workload before assuming it undercuts gpt-5.4-mini.
How do I use Muse Ember in an automation? Find the step in your workflow that calls the model and swap the model name.
Keep the prompt and field mappings identical, then run the same inputs through both models. If the output shape changes, the swap isn't drop-in.
Is Muse Ember better than gpt-5.4-mini? Only your test can say, and only for your task. The findings can't answer these:
- Muse Ember's speed on Artificial Analysis, an independent site that publishes measured model speeds
- Task counts on a shared benchmark, which would show whether results rest on a large sample
- Any pricing beyond what the maker's page states
Until those exist, the small test's your evidence.
When was Muse Ember released? Take the date from the maker's page. The findings here don't add one, and the swap decision doesn't depend on it.