SambaNova API Pricing: Cost per Million Tokens (2026)
Oct 30, 202615 min read
According to LiteLLM, SambaNova charges per million tokens, with a free tier and paid tiers above it. The model you pick moves your input price from $0.22 to $3 per million.
That's a 13.6x spread inside one API, so comparing SambaNova to competitors requires specifying the model.
What SambaNova Cloud is, in one paragraph
Send tokens to open-weight models running on SambaNova's hardware, and you pay for the tokens you send and receive. That is Cloud, the company's hosted inference API. The metered unit's the token, not the seat or the run.
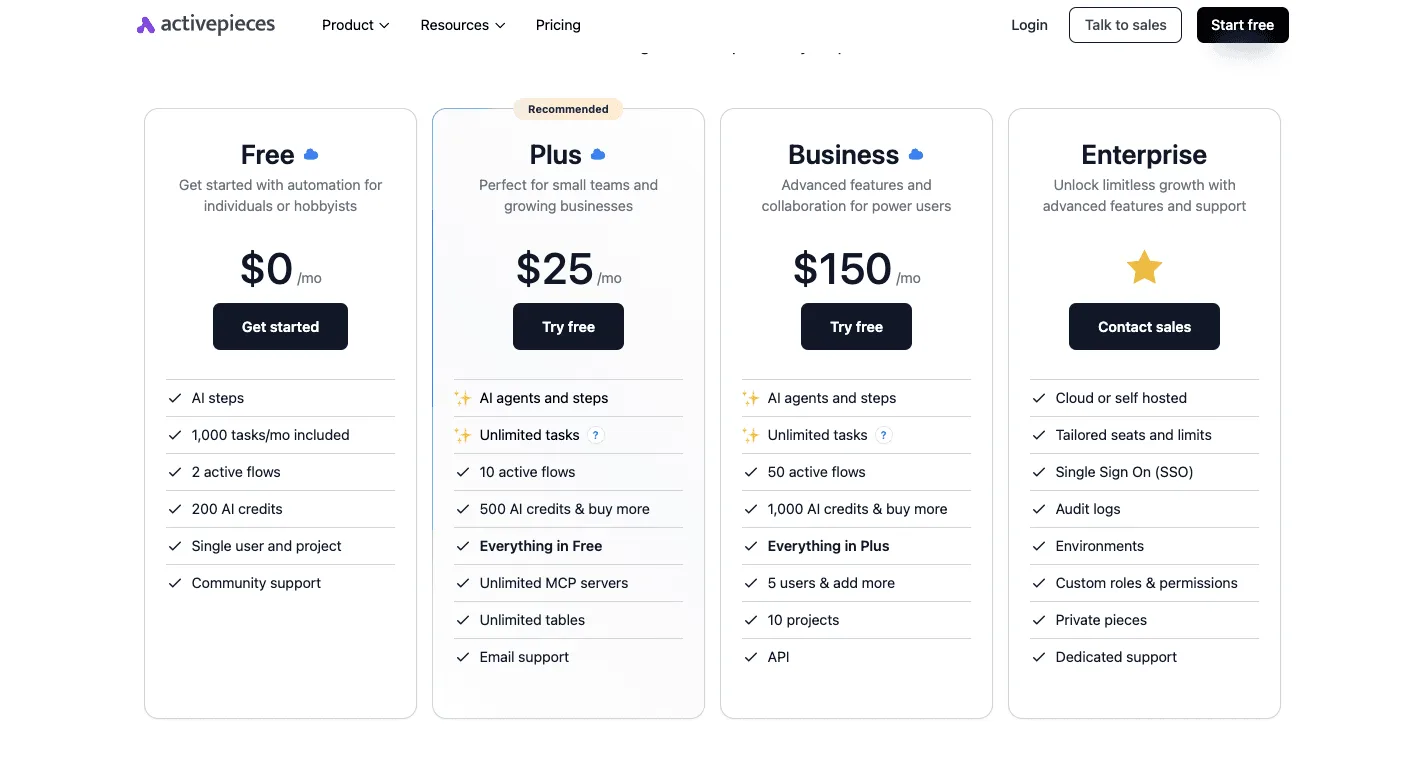
Activepieces takes your own AI keys on Plus ($20 a month) and up, bills every AI step at 1 credit, and leaves the model cost on your own provider bill, so the model choice carries through.

Moving between tiers barely changes the per-token rate; what changes is how many requests per minute you may send. That means a plan's a capacity decision. Match it to your request volume before you compare model prices.
LiteLLM lists:
- GPT OSS 120B is $0.22 per 1M input tokens, so 10M input tokens a month costs $2.20
- Gemma 4 31B is $0.38, which makes it the next-cheapest option
- MiniMax M2.7 and Llama 3.3 70B both cost $0.60, so on input price alone you pick between them on quality
- Llama 4 Maverick is $0.63, a few cents more for a larger model
- DeepSeek V3.1 is $3, so the same 10M tokens costs $30
- Prices were last checked on 2026-10-30
Check SambaNova's own pricing page for cached input and current prices before you budget.
| Model | Input $/1M tokens |
|---|---|
| GPT OSS 120B | 0.22 |
| Gemma 4 31B | 0.38 |
| MiniMax M2.7 | 0.60 |
| Llama 3.3 70B | 0.60 |
| Llama 4 Maverick | 0.63 |
| DeepSeek V3.1 | 3.00 |

Five of the six models cost under $1, so the cheap end's crowded. Justify DeepSeek V3.1 with a specific need.
SambaNova rate limits and free tier by plan
Unless the tier lets you call the model you just justified as often as your workload needs, the choice doesn't help, because your plan sets the ceiling on requests and tokens.
Free is a testing allowance, not a production one. SambaNova meters three things: requests per minute, requests per day and tokens per day, and the table ranks the tiers on each.

| Tier | Requests per minute | Requests per day | Tokens per day | Pricing page vs docs |
|---|---|---|---|---|
| Free | Lowest cap | Lowest cap | Smallest daily budget | Use the docs rate-limit page |
| Developer | Raised above Free | Raised above Free | Much larger daily budget | Use the docs rate-limit page |
| Enterprise | Set by contract | Set by contract | Set by contract | Confirm in the agreement |
Wherever the pricing page and the docs disagree, build your capacity plan on the docs, because that page describes what the API enforces.
SambaNova free tier request limits
On Free, it's usually the daily request cap, not the token budget, that stops a prototype first. A few long prompts exhaust requests before tokens, so a batch job or a busy demo stalls partway through the day.
Treat Free as a way to check output quality on your own prompts, not as a place to run anything that has users.
Moving to Developer raises all three meters, and the token budget rises by the largest margin. That matters most for long-context and agent workloads, which spend tokens quickly. Enterprise limits are negotiated, so the figure comes from a contract, not a published ladder.
Expect tighter caps on some models than the plan's default limits suggest. A large model such as DeepSeek V3.1 may allow fewer requests per minute than a small one on the same tier.
Check the per-model entries before you size traffic, since the slowest-capped model in your pipeline sets your real throughput.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
What SambaNova Costs a Month at Three Workloads
Once you know the slowest-capped model, the bill follows from one formula: tokens metered in and out, each multiplied by that model's per-million price. The model you choose moves the total more than the traffic does.
Without the prices, which you should read from SambaNova's current pricing page, the table lays out how each workload's inputs build up to a dollar figure.
The model you choose moves the total more than the traffic does.
| Workload | Monthly input tokens | Monthly output tokens | Cheapest adequate model | Monthly dollar cost |
|---|---|---|---|---|
| Support-ticket summariser | tickets × tokens per ticket thread | tickets × summary length | Smallest model that keeps summaries accurate | input ÷ 1M × input price + output ÷ 1M × output price |
| 5,000-conversation chatbot | 5,000 × turns × context resent each turn | 5,000 × turns × reply length | Mid-size model that holds tone and facts | same formula, mid-size prices |
| Nightly batch extraction | nights × documents × document length | nights × documents × extracted fields | Largest model only if smaller ones miss fields | same formula, large-model prices |
Read the table by column: the rows differ most in how input tokens accumulate, which is where the chatbot surprises people.
For ticket summarising on a small model, input dominates, because a long thread produces a short summary.
Output is not free, but the input price of the smallest acceptable model sets the floor for the bill, and you should test whether that model's summaries hold up before paying for more.
For the customer chatbot on a mid-size model, each turn resends the conversation so far, so input tokens grow faster than the conversation count suggests. A 5,000-conversation month costs more than 5,000 times a single exchange, and trimming history's the cheapest saving available.
When the job is nightly extraction on a large model, delay is fine but missed fields are not.
Pay for the large model only if a smaller one fails your accuracy check, and size the job against the model's rate limit so it finishes inside the night.
Whichever row matches your traffic, run your own counts through the formula before choosing a tier.
Hidden SambaNova API costs and limits
Past list price, which is all the formula covers, five things move the bill, and you can check each before you pick a tier. Each one changes either the tokens metered or the capacity you can buy:
- Output tokens priced above input ($0.60 in vs $2.40 out)
- Long-context requests
- Retries after throttling
- Model deprecations
- Quote-only enterprise capacity
Output tokens and context length
On every model here, output costs more than input. On Compute Prices, MiniMax M2.7 runs $0.60 in and $2.40 out per million tokens, so a chatty response costs four times what the prompt did.

Output price gaps by model
Roughly 3x is the gap on both GPT-OSS 120B ($0.22 to $0.59) and Gemma 4 31B ($0.38 to $1.15), so verbose outputs dominate your spend there too.
DeepSeek V3.2 is $3 to $4.50, a narrower 1.5x gap but a much higher floor, so cap output length on the cheaper models and watch input on this one.
Context limits per request
Per request, context limits decide how much you pay. Per SambaNova Docs, MiniMax M3 takes 1,000 thousand tokens, while Llama 3.3 70B, DeepSeek V3.1, GPT-OSS 120B and Gemma 4 31B take 128 thousand.
DeepSeek V3.2 takes only 32 thousand, so long documents must be chunked, and every chunk repeats your instructions as billed input.
SambaNova retries and model deprecations costs
When you resend a throttled request, it is metered again if the client re-submits the whole prompt. Budget a retry margin on top of the formula, and use backoff so bursts don't multiply spend.
When a model is retired, you are forced to migrate to another row of the price table. Check the changelog before committing, since a replacement can carry a different input-to-output ratio.
SambaNova enterprise capacity pricing
You can't model enterprise capacity, because it has no published rate. If your volume pushes past the self-serve tiers, the cost's a sales conversation, not a formula.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
SambaNova versus Groq, Cerebras, and Together AI
For a comparable open model, the four vendors price tokens close enough that list price rarely decides the purchase; the limits attached to each tier do. That follows from the sales-conversation point above: once you leave self-serve, you're comparing negotiated capacity, not a rate card.
Price for a comparable Llama-class model
Pick one open model that all four vendors host, then compare input and output tokens separately, because output tokens are the larger line for chat and agent workloads.
I'm not quoting per-million-token prices here, since they change and each should be read from the vendor's own pricing page on the day you buy.
Do the math at your real input-to-output ratio. A vendor that's cheaper on input but dearer on output will lose on a generation-heavy workload, and a gap that looks small per million tokens becomes real money at billions of tokens a month.
Free tier and rate limits compared across vendors
On a free or entry tier, the meter that matters is requests and tokens per minute, not dollars. A low ceiling means a production burst gets throttled, so you pay in retries and latency rather than on the invoice.
Compare each vendor's free allowance by what it lets you test: a prototype at your expected concurrency, not a single prompt.
Also check whether limits are set per model, since a tier that's generous on a small model can be tight on the large one you actually need.
If the model you need's one SambaNova serves well and your traffic fits inside a self-serve tier, SambaNova is the better buy. A competitor wins in three cases:
- Your model isn't offered, or is offered with a shorter context window than your documents need.
- Your burst rate exceeds the tier ceiling and another vendor's limit is higher at the same spend.
- You need a broad catalog of models from one provider, which a wider host can supply.

Run the same test prompt set against each vendor and compare cost per completed task, not cost per token.
Automating SambaNova API Calls with Activepieces
To run SambaNova API calls on a schedule or in response to an event, you use Activepieces, a workflow automation tool.
It bills 1 credit per flow run however many steps sit inside it, so a ten-step flow with a retry branch, an error handler and a database write costs what the two-step workaround did, whereas Zapier charges per task and Make per module for the same care.
The price per token and the tier limits stay exactly where they were. What changes is how many calls you make, and how many of them fail and get paid for twice.
Calling the API from a workflow
Start with a trigger: a timer, a webhook, a new row in a spreadsheet, an incoming email. After it you add a step that sends an HTTP request to SambaNova's endpoint with your API key and a prompt built from the trigger's data.
Once SambaNova replies, the reply goes to the next step, which might write a summary to a database or post it to a chat channel.
Count the run, because each time the trigger fires, one run starts, and each run makes at least one model call. So the number of runs is the number of requests your SambaNova tier has to absorb.
Summarize a day's tickets in one nightly job and that's one run. A webhook that fires on every incoming support message's as many runs as you have messages.
Decide which pattern you're building before you choose a plan, because the second one's what pushes you into a higher rate-limit tier.
Handling SambaNova rate-limit errors and capping spend
When SambaNova returns a rate-limit error, the request didn't complete, so the right response is to wait and send it again, not to drop the task.
With Activepieces you can set a step to retry on failure and branch on the error, so a rejected call can pause and try again instead of ending the run as a failure.
That protects your completed-task count, which is the figure you compared vendors on.
But retries cost something. A loop that retries without a limit can turn one stuck workflow into a stream of calls.
Cap the number of attempts per step, and cap the runs a workflow may start in a period. With both caps in place, the worst month your automation can produce has a ceiling you can calculate in advance from your model's per-token price.
A Monday Checklist for Picking a SambaNova Plan
Work through six steps in order, because each one sets the input for the next and the plan choice only becomes obvious at step four.
Estimate tokens and pick a model
- Estimate monthly tokens. Count the requests your automation makes in a month, then multiply by the average input and output tokens per request. Keep input and output separate, since the two are metered at different prices, so a workload that writes long answers costs more than one that reads long documents and replies briefly.
- Pick the cheapest adequate model. Take the smallest model on SambaNova's list that passes your own quality check on a sample of real inputs. Each step up in model size raises the per-token price on every request, so a model chosen for headroom you never use is a recurring charge on your whole volume.
Test SambaNova free tier limits before paying
- Test on the free tier. Run that sample through the free tier with the model from step two. You're checking output quality and also how the account behaves under load, which tells you whether you need to pay at all.
- Measure request rate against limits. Log your peak requests per minute, not your average, and compare it with the rate limit of each tier.
If your peak sits above a tier's ceiling, you will see throttled calls and retries, and the tier is wrong for you whatever the token price says. This is the step where volume, not list price, picks the plan.
Set a SambaNova spend alert and pricing re-check
- Set a spend alert. Put the alert below the ceiling you calculated from the caps, so you hear about drift before the cap stops your jobs.
- Re-check the pricing page on a fixed date. Put a recurring entry in your calendar, once a month or once a quarter, to compare SambaNova's pricing page with your estimate. Prices and limits change, and a calendar date catches that where memory won't.
Frequently asked questions
Choosing a plan leaves a few billing questions that decide whether the estimate holds. Each answer below says whether it was confirmed against SambaNova's own pages.
Is the SambaNova API free to use? Yes, up to a point: SambaNova has a free tier with tighter rate limits than the paid tiers, so it suits testing but not production traffic.
Whether it requires a card on file is unconfirmed, and I haven't linked a vendor page I could not verify. Check the signup flow before assuming either way.
Does SambaNova charge for input and output tokens separately? Yes, the list price gives each model an input rate and an output rate per million tokens.
A workload that generates long answers from short prompts is therefore billed mostly at the output rate, so estimate the two token counts separately. Reading the input rate alone understates that bill.
Can I use SambaNova with OpenAI client libraries?
Yes, SambaNova documents an OpenAI-compatible endpoint, so in most cases you change the base URL, the API key and the model name.
That keeps switching cost low, but test any parameter you depend on, such as tool calling or streaming options, because compatibility can be partial.
I've left the exact base URL out rather than guess; it is on the vendor's docs.
How do I get higher SambaNova rate limits? Limits rise as you move up tiers, and the highest volumes go through a sales conversation rather than a published price.
Enterprise terms and quotas are unconfirmed, so ask for them in writing and tie the request to your measured peak requests per minute.
Does SambaNova offer a discount for batch requests? Unconfirmed. I found no batch pricing I could verify, and prompt caching is in the same state.
Price your workload at the standard rate, and treat any batch or caching discount as an upside to ask the vendor about, not as part of the budget.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales