MiniMax M3.1 Flash Pricing & Specs: 2026 Test Results
Oct 25, 202611 min read
MiniMax M3.1 Flash is a native multimodal mixture-of-experts model from MiniMax, built for coding, agentic workflows, computer use and cybersecurity. Its page on the maker's Hugging Face was live on 2026-10-25.
Everything below rests on that page, not on third-party benchmarks, so claims about how it behaves in Activepieces or any other automation setting are outside what we can say here.
Meet the new MiniMax M3.1 Flash model
What MiniMax M3.1 Flash is built for
About MiniMax: the model is described as native multimodal, so it takes more than text. Its listed focus on agentic workflows and computer use is why it belongs in an automations conversation at all.
The page gives us no release date we can quote, so treat 2026-10-25 as the earliest date we can vouch for.
Until you run it on your own jobs, any "cheaper" or "faster" claim is the maker's word, and a client won't accept that on an invoice. Nothing about cost or speed per task has been independently measured beyond our own small test.
Where to access MiniMax M3.1 Flash
Before you commit a client workflow to it, confirm availability and terms on the maker's Hugging Face page, which is the primary source. For automations, what matters is whether your builder can reach the model without custom code.
Open Activepieces and you'll find a connector library of 744 integrations counted from its open source monorepo, roughly 60% of them community-contributed, sorted by category and last-updated date, so you can see what the platform can call today and when each connector was last maintained.

Search that library for the model or its provider before planning anything. If there's no connector, you're paying for extra setup time on a generic request step, and someone has to bill that time instead of a shared account absorbing it.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Why new models benefit automation teams
Because every AI step in a workflow is a part you can swap, a new model matters. A swap pays only if that step gets cheaper or faster without the output getting worse.
The rest of the workflow stays put: the trigger, the connectors and the hand-off to the next app. Only the model call changes.
You never need to judge a model in the abstract, because a swap makes the decision small and testable. You judge it against the one you already run, on the one step you'd hand it.
Start from what a client will accept on an invoice and work backward. A step that runs hundreds of times a month can hide a lot of waste.
A shared account will absorb that waste quietly until someone checks which client's runs are paying for it.
Three measurements settle a swap:
- What one run of the step costs, counted per task rather than per list-price unit.
- How long one run takes from start to finish, since a slow step holds up everything after it.
- Whether the output holds up when you feed both models the same input, so the comparison is fair.
When a model wins on two and fails the third, it has only moved the cost somewhere else, usually to whoever has to correct the output by hand. The sections below take each measurement in turn, using MiniMax M3.1 Flash as the candidate.
What MiniMax says is new in M3.1 Flash
The maker's page lists capabilities, but input price and context size are not published on the pages checked, so you can't benchmark the total cost.
The maker's page lists capabilities for M3.1 Flash, but the table's capabilities entry is not published. Until MiniMax publishes them, any claim about what it does better is the vendor's silence filled in by someone else, and you shouldn't budget around it.
Price and access terms
Read the "not published" cells as gaps in your cost model. The table shows what each page states, checked 2026-10-25. You can't price a run without an input rate, so you can estimate only the output side today.
| Item | What the page states |
|---|---|
| Capabilities | Not published |
| Context size | Not published |
| Input price | Not published |
| Output price | — |
| Access terms | Not published |
Because the link in each row goes to the ModelMenu price tracker, not to MiniMax itself, you should treat the output figure as reported rather than confirmed by the maker.
Compare it with the earlier releases. The tracker lists M1 at $2.20 per million output tokens. M2, M2.1, M2.5, M2.7 and M3 all sit at $1.20.
A job that is mostly output would see its generation bill halve, if the quality holds. The chart below sets the releases side by side.
What Activepieces shipped for MiniMax M3.1 Flash
On 2026-08-24 Activepieces added MiniMax as an AI provider in a dated pull request. The change is provider-level, so it's not a dedicated M3.1 Flash integration.
That matters when you price a test: you're borrowing a general connection, not a tuned integration.
The shipped support and its date
Alongside xAI, DeepSeek, Z.ai, Qwen and Moonshot AI, the Activepieces pull request registers MiniMax on 2026-08-24. All of them use the OpenAI wire format, which means the platform talks to MiniMax the same way it talks to any OpenAI-style endpoint.
For an agency, swapping models inside one flow is a settings change, not a rebuild. A side-by-side cost test costs you an afternoon rather than a project.
The pull request doesn't name M3.1 Flash specifically, so confirm the model identifier against MiniMax's own page before you rely on it.
Connecting it in a workflow today
Start with a throwaway flow, not a client's live automation. The screenshot shows the builder with a Schedule trigger set to "Every Hour" selected, a successful sample-data test beside it, and the integration selector open over the canvas.
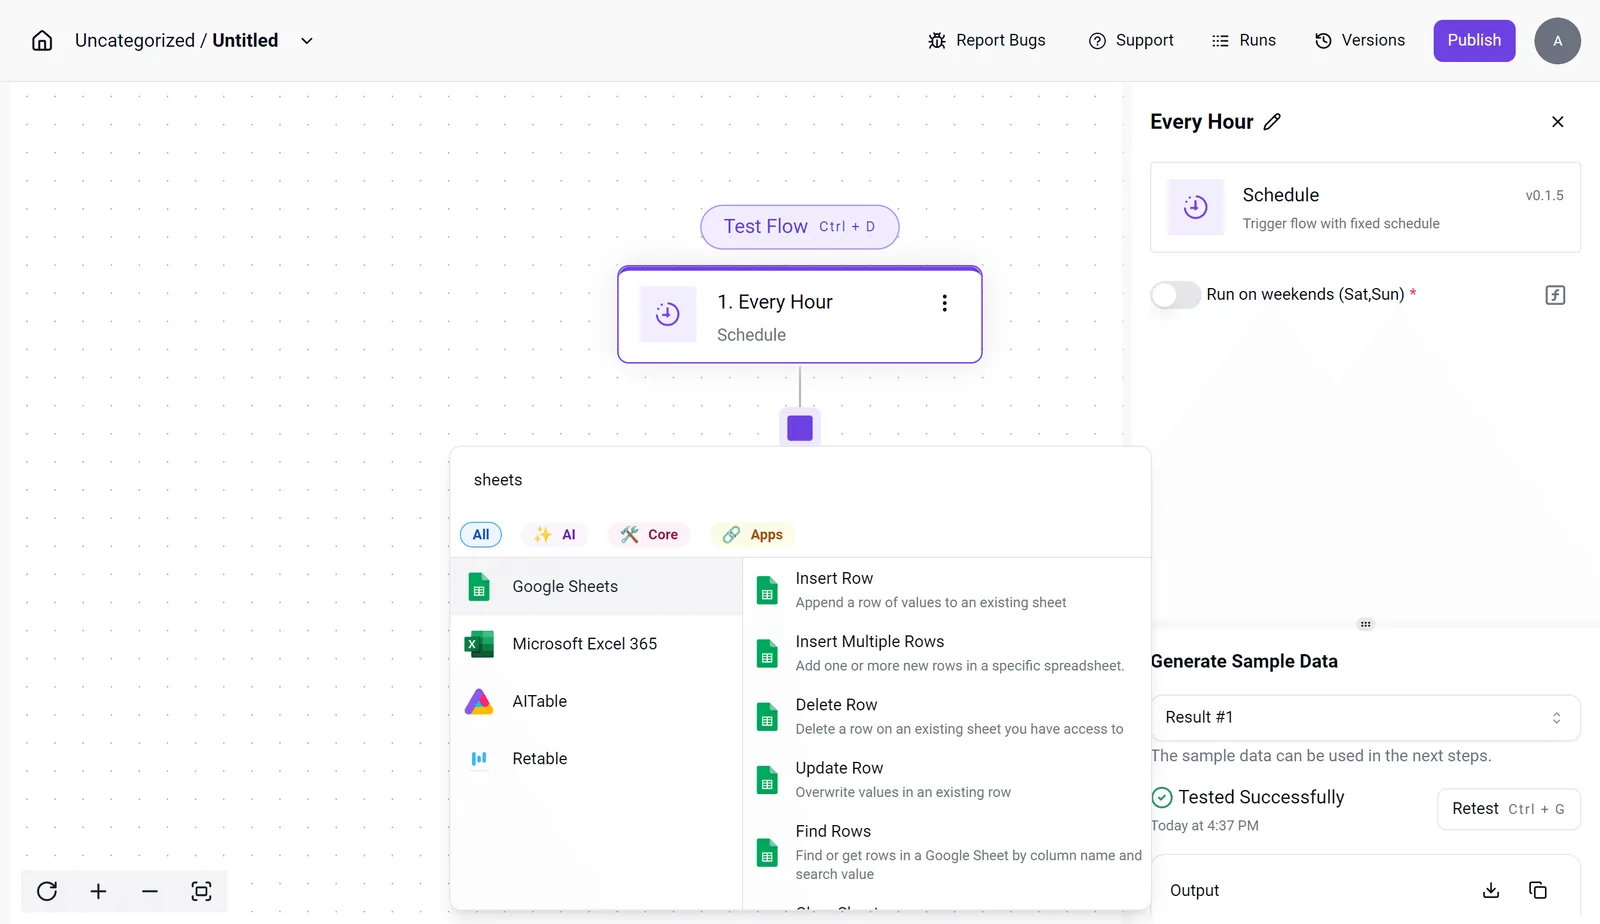
Run that trigger on a test sample first, so you pay for nothing until the steps behind it are proven.
Your own AI keys come with the Plus plan at $20 a month, where every AI step counts as 1 credit and the model cost lands on your own provider bill, so the per-task figure you measure is the rate your provider charges rather than a markup.
The pricing page lists the same step at 2 credits for a fast model, 10 for a smart one and 20 for a frontier one when Activepieces supplies the model, which is the rate your own key avoids. Use this order:
- Keep your current model's step as the baseline.
- Add the MiniMax provider with your own API key, on your own account, so a client's usage never rides on a shared key.
- Duplicate the step, point it at the new model, and feed both the same inputs.
- Compare cost and run time per task, then decide.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
What we measured on three automation tasks
Speed alone won't settle which model you bill a client on.
The three tasks and how we scored them
On 2026-10-25, both models were run on the same three jobs: sort a support ticket, pull fields from an invoice, and summarise an email thread, which means you can directly compare their performance.

MiniMax M3.1 Flash was called as minimax/minimax-m3.1-flash on OpenRouter with default settings, against openai/gpt-5.4-mini.
Each output was checked against a known answer. This is a small, indicative test, not a benchmark. Treat it as a reason to run your own, not as proof.
Results, speed and cost per task
MiniMax won the two short, structured jobs and lost the longest one. The table shows median seconds per task.
| Task | MiniMax M3.1 Flash (seconds) | openai/gpt-5.4-mini (seconds) |
|---|---|---|
| Sort a ticket | 0.4 | 0.8 |
| Invoice fields | 0.6 | 0.8 |
| Summarise email | 1.2 | 0.9 |
Half the wait: sorting a ticket took 0.4 seconds against 0.8, which matters when a ticket flow fires hundreds of times a day, because seconds scale. Invoice extraction ran 0.6 seconds against 0.8, a gap you'll barely notice in a single run.
The one task with long input and free-form output went to the incumbent: summarising an email thread took 1.2 seconds against 0.9, so the newer model still hasn't closed this gap.
To price a run, take each model's per-token rate from its own page and multiply by the token counts of your real tasks. Speed is only half the invoice question.
Until you do the multiplication, a shared account is quietly subsidising whichever client sends the longest emails.
Speed is only half the invoice question.
What MiniMax M3.1 Flash pricing means per task
Only once you price the gap per client run does a cheaper, faster model change your bill, and it only holds on an invoice if the cheaper output survives checking.
Multiplied by volume, the per-run gap from a small test, a fraction of a cent or a few cents, starts to matter. On a client running a few hundred tasks a month, the saving is too small to change a quote.
On the client with thousands of long-email runs, it's the margin.
Where a person or a chained step is waiting, seconds per run matter. In an overnight batch, faster output buys you nothing, so don't build it into a price.
MiniMax M3.1 Flash hallucination rate caveat
At 93 %, M3.1 Flash's hallucination rate, according to Artificial Analysis via AgiHunt, means it bluffs on most questions it can't answer. DeepSeek V4.1 Flash scores 67 %, Gemini 3.8 Flash 55 %, GLM-5.3 Flash 28 % and MiniMax M3 18 %.

M3.1 Flash is the worst of the five, so a saving on it can be paid back in rework.
Your automations are not what the chart measures. It covers questions a model doesn't know, so it can't show how often your tasks go wrong. Only your own inputs can.
Use the result in this order:
- Take your monthly run count.
- Multiply it by the per-run cost gap.
- Compare seconds per run, and ignore the gap if no one waits.
- Check output on your own inputs, including ones with missing facts.
- Swap one step only, so any failure has one cause.
If the saving survives step four, move that one step first and leave the rest of the workflow alone.
What to watch next with MiniMax M3.1 Flash
Watch three things, all of which you can observe without guessing: the maker's Hugging Face page, any published pricing change, and your own three tasks rerun on a schedule, enabling you to spot genuine improvements when they happen.
If the first saving held up after step four, these checks tell you whether it keeps holding or quietly erodes.
What to check on the Hugging Face page
Treat any edit to the maker's Hugging Face page as a change to your assumptions, since it is the only source for what the model is supposed to do.
Look at the model card text, the listed version, and any note on limits or intended use.
A revised version means the model you tested is no longer the model you're billed for.
Check pricing separately. A list price that moves changes your cost per task directly, and it can move in the client's favor or against it.
On a shared account, a price rise is the point where one workflow starts costing more than the client is paying for. Nobody notices until the invoice. Note the date you last confirmed the price, and confirm it again before each billing cycle.
A test to run on your own tasks
Keep the same three tasks you used in the original test, with the same inputs and the same pass criteria, making future results directly comparable to this baseline. Rerun them whenever the maker's page changes, or on a fixed rhythm if it doesn't.
Record cost per task and time per task beside the model you already run, not in isolation.
This is the only check that speaks for your workload. If the saving shrinks or the output quality slips, you have your answer in numbers, and you can move the task back before the client sees it.
Related reading
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales