Turbopuffer Pricing: All Plans Compared (2026)
Nov 10, 202616 min read
Per Turbopuffer, the service bills for what you store, write and query, and every plan sets a monthly minimum, a detail worth checking before you wire it into a pipeline built with something like Activepieces:
Turbopuffer pricing is a usage-based model for its object-storage-backed vector and full-text search database, in which you pay for the data you store, the writes you make and the queries you run, subject to a minimum monthly spend set by your plan.
- The Launch plan has a monthly minimum of $16
- The Scale plan has a monthly minimum of $256
- The Enterprise plan has a monthly minimum of at least $4,096
- You can't use the service without a minimum monthly commitment
- Your usage decides the bill
- The plan only sets its floor
There are no nodes to size, because turbopuffer is a serverless vector and full-text search database. Three units set the bill:
- Data stored
- Data written
- Queries run
Estimate your bill from your data size and your read and write traffic before you look at plan names.
Plan table, checked 2026-11-10
Read each figure as the least turbopuffer will invoice you in a month, not as a typical bill. The table lists the three plans and the monthly minimum each carries on turbopuffer.com/pricing as of 2026-11-10.
| Plan | Monthly minimum |
|---|---|
| Launch | $16 |
| Scale | $256 |
| Enterprise | ≥ $4,096 |
Step up a plan and the floor multiplies, so it is a commitment decision. Moving up because a plan looks more complete is not a good reason. The next section covers what that floor does to your bill.
What the monthly minimum means
Pay less than the minimum in metered storage, writes and queries and you still pay the minimum; pay more and you pay the usage. That is what a monthly minimum is: a floor. Two things follow from that.
First, a small or sporadic workload overpays. If your real usage would come to a fraction of the Launch minimum, the rest of that $16 buys nothing.
The gap is wasted money, every month. Because the floor rises at each tier, the waste grows too if you pick a plan your data doesn't justify.
Second, the floor stops mattering once usage is large. A big vector dataset that is rarely queried is mostly a storage bill, and storage is the meter this pricing is built to keep cheap.
At that scale the minimum is a rounding error beside the usage charges.
Now take the opposite case, a dataset queried constantly. Query volume then becomes the dominant meter, and the minimum tells you nothing about what you'll pay.
Budgeting from the floor
Look at the "≥" on Enterprise. It marks the starting point of a negotiated range, not a fixed price, so you can't budget from that figure alone.
Before you commit to any plan, work out your gigabytes stored, your writes per month and your queries per month. Those three numbers are your bill, and the plan only sets how low it can fall.
Stage-by-stage Estimate of a Real Monthly Bill
Once you have those three numbers, turning them into a monthly figure takes five steps, and the last one's simply taking the larger of your usage total and the $16 Launch minimum.
The workload is a five-person team's docs search: about 10 million vectors at 768 dimensions, with a stated number of writes and queries per month.
If you want to document your bill calculations, keep the pricing page and its calculator open in two windows and take a screenshot of each at every step.
The screenshots show which rate line you filled in and what it returned, which is what you want on file when the invoice arrives.
- Size storage: 10 million vectors × 768 dimensions × 2 bytes (f16) is about 15 GB, which means you'll incur storage costs from the start regardless of queries.
- Enter writes: the GB you upload in a month, priced at the page's write rate, gives your write line.
- Enter queries: count each search, apply the 1.28 GB minimum to each, and price the total at the query rate to get your query line, so your query bill grows with volume.
- Sum usage: storage line plus write line plus query line gives your usage total.
- Compare that total to the $16 Launch minimum and take the larger, which means you'll pay at least $16 per month no matter what. That's the bill.
Multiply vector count by dimensions by bytes per value, and f16 means two bytes. That gives about 15 GB, which is small enough that the storage line is likely to be the smallest of the three.
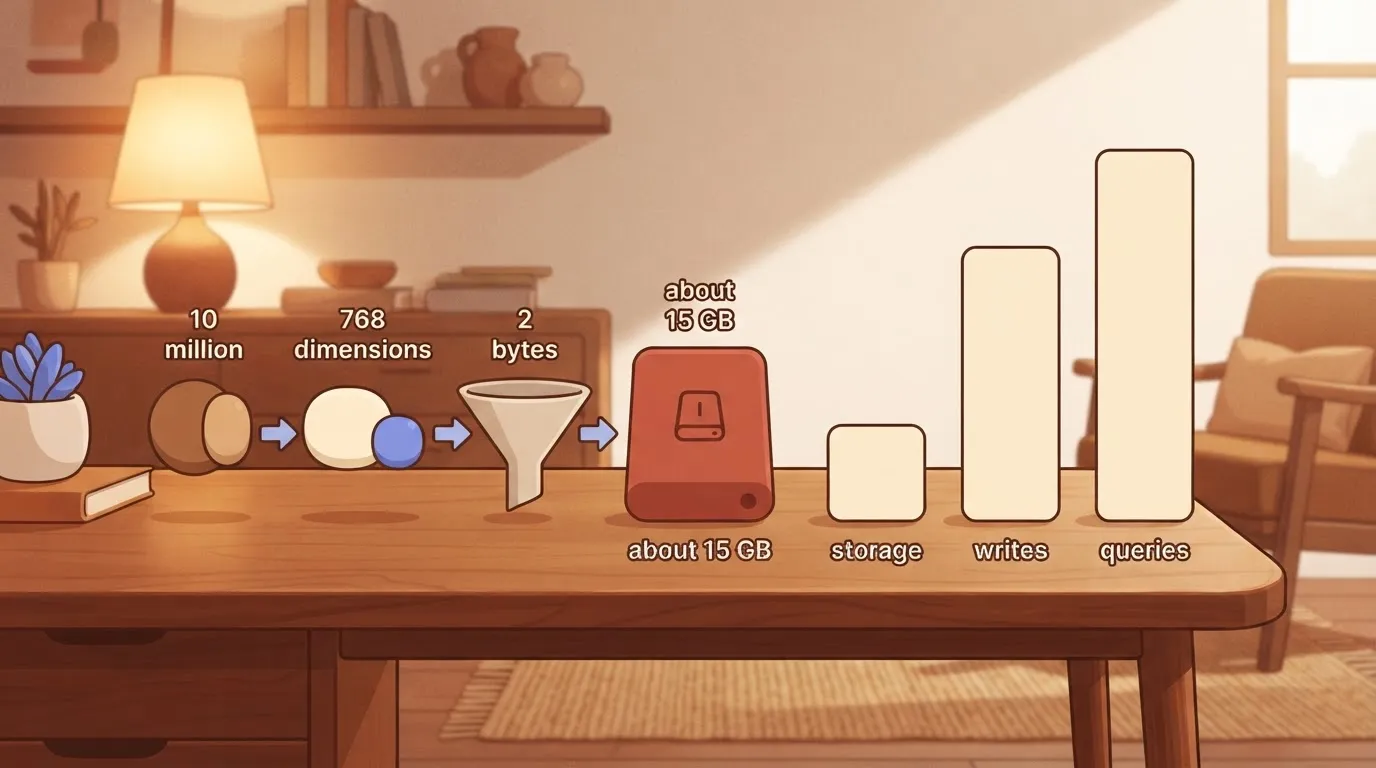
Attributes and document text stored beside each vector add to this, so include them before you read the rate off the page.
Count writes and queries
Writes come from how often your docs change, not from how many exist. A team that re-indexes the full corpus nightly pays for that full upload every night, while one that upserts only edited pages writes a small fraction of it.
Writes come from how often your docs change, not from how many exist.
For queries, each search is billed at no less than 1.28 GB, so thousands of tiny lookups are priced as thousands of large ones.
When five people search docs a few times an hour, the count stays modest, but an agent that searches on every step multiplies it quickly.
Compare the total to the plan minimum
Add the three lines and set the result against the $16 Launch minimum, so the higher value is your actual monthly charge. If usage lands below it, you pay $16 and the usage detail stops mattering.
If it lands above, you pay usage and the plan changes nothing.
With mostly idle data, a team of five should expect the first case, which is why the minimum, not the rate card, sets the bill.
Turbopuffer Pricing at 10x the Data Volume
Repeat all five steps with ten times the vectors, about 150 GB, revealing whether costs scale linearly or whether the vendor applies pricing lock-in, because at that volume, even small per-unit premiums accumulate into significant overcharges.
Storage scales in a straight line, and writes and queries scale with it if your usage pattern holds.
Think of it as the check on lock-in, done as arithmetic: if the 10x total still sits near the minimum, growth is cheap, meaning scaling won't lock you in through pricing.
If it jumps well past it, you now know the volume where the bill starts following usage.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Hidden Turbopuffer Costs and Limits That Affect Pricing
Beyond the headline rates, four things move a turbopuffer bill. They're how queries are metered, the limits your data shape runs into, whether a query hits cold or warm data, and the embedding spend that never appears on its invoice.

Each one decides where your 10x total lands relative to the minimum.
Billing units and per-request minimums
Because queries are metered by data queried, each one is billed for at least 1.28 GB. A small namespace therefore costs the same per query as a 1.28 GB one, so a chatty app with tiny indexes pays for volume it never touches.
Above that floor, marginal discounts apply: 80% above 32 GB and 96% above 128 GB queried, so the per-unit cost of additional queries plummets above 128 GB.
Large, mostly idle data gets cheaper per gigabyte as it grows, which is the shape of workload the pricing favours.
If your data is small, pinning is not an option: it keeps a namespace warm on dedicated capacity and carries a minimum of 64 to 128 GB as of August 2026.
Committed-spend discounts are the other lever, but they only pay off if your monthly usage reliably clears the commitment.
Hit a limit on namespace size, document count or attributes and you have to change your data layout rather than pay more, because these are fixed ceilings, not price tiers.
Check them before choosing between one namespace per tenant and a shared namespace with a filter, because that choice sets both your per-query minimums and your ceiling.
Cold queries and cache behaviour
Whether the data is in cache decides latency. The turbopuffer performance documentation puts p50 between 14 and 874 milliseconds, p90 between 17 and 1214, and p99 between 27 and 1686, spanning warm to cold.
874 ms cold against 14 ms warm is roughly 60 times at p50, so an interactive search box that sits idle overnight will feel slow on the first query of the morning.
Constant-hot workloads stay near the low end but pay for that constant traffic. Idle data is cheap, but it's slow to wake.
Costs outside turbopuffer: embeddings and sync
Turbopuffer will not create your vectors for you; it stores and searches them. Every document and every query needs an embedding from a model provider, billed separately per token. For a team re-embedding after a model change, that charge can exceed the storage bill.
Once you keep the index in sync with your source database, that adds its own cost: each upsert is a metered write, and the job that runs it is infrastructure you operate.
Activepieces can run that job, and the run is the meter: its published pricing page lists 1 credit per flow run, however many steps, so a ten-step sync of fetch, filter, embed, batch and upsert costs the same as the two-step shortcut it replaced.
Zapier bills per task and Make per module, so splitting the job into smaller, more reliable steps raises the charge there, while turbopuffer meters the same writes either way.
Turbopuffer Against Pinecone, Qdrant Cloud and Weaviate Cloud
Because of those sync writes, the metering unit, not the plan name, decides this comparison. Turbopuffer bills storage, writes and queries as you use them, so large, mostly idle data stays cheap and constant-hot data doesn't.
Entry price and free tier
Because this article carries no confirmed price figures for the four vendors, the table below compares what each one meters and what that does to a workload like yours.
Take from it which line of your usage each vendor charges for, then read the live pricing page for the rate.
| Vendor | What is metered | What drives your bill |
|---|---|---|
| turbopuffer | Storage, writes, queries | Data volume, sync frequency, query traffic |
| Pinecone | Storage, plus read and write units on serverless | Query and upsert volume, plus stored data |
| Qdrant Cloud | Provisioned cluster resources over time | Cluster size, whether or not it is busy |
| Weaviate Cloud | Stored data, scaled by vector dimensions | Dimension count and collection size |
The practical split is usage against reservation. With usage metering, an idle index costs roughly its storage. With provisioned resources, an idle index costs the same as a busy one, so you're paying for headroom you may not use.
Free tiers exist at some of these vendors, but their limits change, and I haven't confirmed them. Check each page on the day you decide, and record the date next to whatever you copy.
Turbopuffer Cost for a 10-Million-Vector Workload Compared
Price it the same way for every vendor, in three lines.
Storage is 10 million vectors times your dimension count times bytes per value, plus metadata. Writes are the upserts your sync job issues each month, which the previous section showed are billed individually. Queries are your monthly search count.
Run those three numbers against each metering unit in the table. On usage-metered vendors, all three move the bill. On a provisioned vendor, they decide which cluster size you need, and the bill's that size multiplied by hours.
Then add any monthly minimum for your plan, which can exceed the usage total if your workload is small.
Who Should Choose Turbopuffer Over Alternatives
Choose turbopuffer if your data is large, searched occasionally, and updated in batches. Storage dominates your bill, and nothing's reserved while the index sits idle.
If the index is tiny, skip it, because a plan minimum can cost more than the usage it covers.
Skip it also if every query is hot and constant. Query metering then accrues all day, and a provisioned cluster priced for steady load may be the cheaper shape.
Whichever you pick, work out the three lines above before you read the plan table.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
Keeping Turbopuffer Fed with Activepieces Workflows
Skip it entirely if you like; it doesn't lower your turbopuffer bill.
What Activepieces does is keep your turbopuffer namespace current by running a scheduled workflow that pulls changed records, embeds them and upserts them, and flows are unlimited on every plan, the free one included.
Once you have your storage, write and query lines worked out, the question is how data gets into the namespace and stays fresh.
That's plumbing, and Activepieces is one way to build it without writing a service: its MIT-licensed core has 747 integrations counted from the open source monorepo (so you likely have the integrations you need) and MoneyGram, Moneypenny, Alan and FundingSocieties run it in production.
What each tool charges for
Notice which part of the pipeline each tool charges for. Activepieces meters its own work in runs at 1 credit each, so a sync scheduled hourly is about 720 runs a month against the free plan's 1,000 credits.
Turbopuffer meters storage, writes and queries, and the embedding provider meters tokens. Each has its own unit, and the workflow only moves data between them.
What it shows below is the order of those hops, and what to take from it is that the optional step sits in the middle, not at the ends.
Mind the note on the HTTP step, because it matters for your budget.
Sending the upsert through Activepieces instead of a script of your own changes who runs the call, not how many rows are written, and the run stays 1 credit with or without that step in it.
Turbopuffer sees the same writes either way, so the turbopuffer line on your bill is the same.
- A schedule trigger starts the workflow at an interval you choose. That interval sets how stale the namespace can get, so it also sets how often you pay for writes.
- The workflow fetches records from the source, such as a help centre, and keeps only those changed since the last run. Sending everything every time would rewrite unchanged rows and inflate your write volume for no benefit.
- For each changed record, it calls an embedding API to turn the text into a vector. You pay the embedding provider for this, separately from both turbopuffer and Activepieces.
- An HTTP Request step upserts the vectors and any attributes into the turbopuffer namespace. Upserting by a stable record ID means a re-edited article replaces its old version rather than piling up beside it.
When a loop handles one record per iteration, it sends far more upserts than one that sends a batch, and turbopuffer meters every write. Batch where the API allows it.
When a script is the better choice
If the workflow is one fetch, one embedding call and one upsert, a short script on a cron job does the same work with fewer moving parts.
Choose Activepieces when non-developers need to see and edit the flow, or when the same workflow also notifies someone or touches other tools, among its 747 integrations.
Choose the script when the logic is a loop over thousands of records, because there you'd be building a flow for something code does for free. In both cases the turbopuffer bill follows the data you write and query, not the tool that sent it.
Frequently asked questions
Does turbopuffer have a free tier? I can't confirm a permanent free tier, so don't plan around one.
Because the bill is metered on stored data, writes and queries, a small test costs little, but it still lands on a paid plan's minimum. Check the current pricing page for any trial credit before you build a proof of concept.
Can I pay for turbopuffer monthly without a contract?
You pay for what you stored, wrote and queried in the period rather than for a seat count or a prepaid block, because billing is usage-based and monthly.
Whether a given plan ties you to a term is a question for the plan terms and sales, and I won't assume one either way.
In practice, the plan sets your floor, while your volumes set everything above it.
Is turbopuffer cheaper than Pinecone?
It depends on the shape of your data, not on the vendor. Turbopuffer is built to be cheap for large vector sets that sit mostly idle, since you pay for storage and only the queries you run.
If your index is small, or hot around the clock, the minimum and the per-query metering work against you, and the comparison can flip.
Price both with the same three numbers: vectors stored, writes per month, queries per month. Then compare the totals, not the plan names.
What happens if my usage is below the monthly minimum?
You pay the minimum for your plan, not your actual usage. Every month where your metered usage comes in lower, the gap is money spent on nothing. That's why tiny workloads fit poorly: the bill's the floor, and the floor's a fixed cost.
If your usage regularly sits well under it, you're paying for a plan tier you don't need, or for a tool sized for bigger data than yours.
How do I cap or forecast my turbopuffer spend?
Forecast from the three metered units, in this order:
- Estimate stored data: vector count times dimensions times bytes per value, plus attributes.
- Estimate monthly writes, including re-indexing and updates, which are easy to forget.
- Estimate monthly queries from real traffic, including your busiest period.
Multiply each by the current rate on the pricing page, add them, and compare the result with your plan's minimum. The larger of the two is your bill.
For a hard cap, I can't confirm a built-in spending limit, so put the control in your own code: rate-limit queries, batch writes, and alert on usage before the month closes.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales