RunPod Pricing 2026 for Pods, Serverless and Storage
Oct 31, 202617 min read
RunPod bills GPU time by the second, and the rate depends on the GPU model, the cloud tier and whether you rent a pod or call serverless, which matters most if you trigger jobs from a workflow tool like Activepieces and only want to pay while they run.
RunPod pricing is the pay-as-you-go billing model for its GPU cloud, in which you are charged per second for compute while a pod or serverless worker runs, plus separate charges for the storage you keep attached.
Storage and savings plans sit on separate meters, so the hourly GPU price is only one line of the bill.
RunPod pricing today: every plan and GPU rate
What RunPod is and how per-second billing works
RunPod is a GPU cloud where you rent a machine (a pod) or send requests to an endpoint (serverless). Billing is per second, so a ten-minute test costs about a sixth of an hour's rate, not a full hour.
The catch is that the meter runs while the pod is running, whether or not your code is doing anything with the GPU, so a pod left idle bills like a busy one.
The table: H100, A100 and RTX rates by plan
The table below sets each plan against what it charges, what it includes and where it stops you. Read the limits column first, because it shows where a low headline rate stops being the whole story.
The prices come from RunPod's pricing page as of 2026-10-31.
| Plan | Price | Inclusions | Limits |
|---|---|---|---|
| Pods, Community Cloud | Per second, by GPU model | The lower-priced tier for on-demand GPUs | Capacity and availability vary by GPU |
| Pods, Secure Cloud | Per second, by GPU model | The higher-priced tier, with more reliable capacity | Costs more than Community for the same GPU |
| Serverless | Per second of active compute | Endpoints that scale with requests | Cold starts and worker settings change the effective cost |
| Storage | Per GB, billed over time | Volumes that persist after a pod stops | Keeps charging while the pod is off |
| Savings plans | Discounted rate for a commitment | Lower cost on steady usage | You pay for the commitment, used or not |
Prices and plan limits checked against runpod.io on October 31, 2026.
The listed on-demand GPU rates per hour are $0.34 for an RTX 4090, $1.19 for an A100, $2.89 for an H100 PCIe and $3.99 for an H100 SXM.
More than tenfold separates the RTX 4090 from the H100 SXM, so a job that fits on the smaller card never needs the larger one.
Serverless versus pods: which meter applies
A pod meters wall-clock time from start to stop.
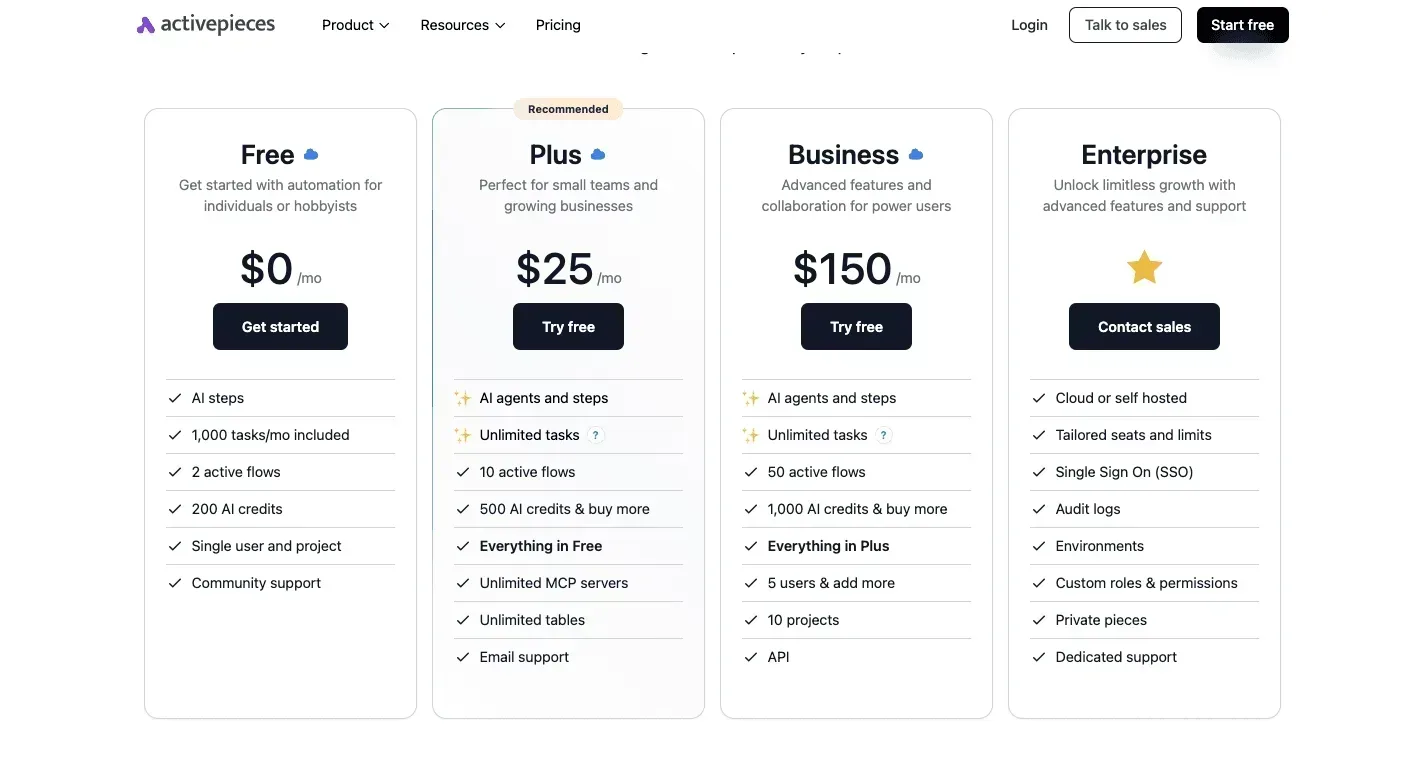
Serverless meters only the seconds a worker is active, which suits bursty traffic such as an Activepieces flow calling an inference endpoint a few times an hour; on Activepieces' Free plan, that flow costs 1 credit per run however many steps it has, against 1,000 credits a month.

If the job runs steadily all day, a pod is usually the simpler meter; for sporadic calls, serverless avoids paying for idle hours.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Example monthly RunPod bill for an inference workload
Add five meters together and you have the month's bill, and only the first two are the GPU work the team thinks it's buying. This is a worked example built from published rate structures, not a measured case.
Week one: the fine-tuning run
The team rents an A100 pod to fine-tune, and the meter is GPU time per second while the pod is running. That suits a steady job, as the choice between pod and serverless suggested.
If nobody stops the pod at the end of the run, the meter keeps counting, and one forgotten pod can cost more than the training did.
Stopping the pod ends the GPU charge but not the disk charge, so the stopped-pod disk becomes a standing line item for as long as the team keeps it.
If nobody stops the pod at the end of the run, the meter keeps counting, and one forgotten pod can cost more than the training did.
Weeks two to four: serving traffic
Serving moves to serverless, billed per second of active worker time on working days. Idle evenings and weekends cost nothing for compute, which is why serverless fits sporadic calls.
Two things still bill around the compute. The model weights sit on a network volume, charged for the storage whether or not a request arrives.
And any worker configured to stay warm is paid for while it waits, so cold-start speed is bought with a meter that never pauses.
RunPod monthly cost total and breakdown by line
Each line in the table below is listed by the unit it meters and the quantity that drives it, so a reader can drop in their own hours and see which line dominates.
| Line | Rate (unit metered) | Quantity (what drives it) | Subtotal |
|---|---|---|---|
| A100 fine-tune hours | Per second of pod GPU time | Hours the run actually takes | Rate × hours |
| Serverless inference | Per second of active worker time | Seconds of requests on working days | Rate × active seconds |
| Network volume | Per GB per month | Size of weights and datasets | Rate × GB |
| Stopped-pod disk | Per GB per month, while stopped | Disk size left behind | Rate × GB |
| One forgotten pod | Per second of pod GPU time | Hours left running unnoticed | Rate × idle hours |
| Total | Sum of the five subtotals |
The last three lines grow without anyone deciding to spend. Storage and the forgotten pod depend on habit, not workload, so the team's first fix is a rule to stop the pod when the run ends and delete the disk it no longer needs.
Costs and limits beyond per-second rates
That rule to stop pods and delete disks fixes only part of the bill. Seven other charges and limits sit outside the per-second rate and decide what a month costs:
- Idle pods that keep billing
- Disk fees on stopped pods
- Network volume charges
- Egress policy
- An $80/hr spend cap
- A maximum of 3 workers per endpoint
- Cold starts
The subsections below take them in the order the bill meets them.
Idle and stopped pods
Every second a pod exists, it bills, whether or not a job is using the GPU. A pod left up over a weekend bills as if it were training the whole time, so the stop rule matters more than the hourly rate.
A stopped pod isn't free either: its disk stays allocated and keeps accruing a storage fee. Stopping ends the GPU charge, and only deleting ends the disk charge.
Storage that outlives the job
A project that finished in March can still show up on the October invoice, if its model weights sit on a network volume. Network volumes are persistent storage billed for as long as they exist, independent of any pod.
Egress policy belongs in the same check: before you move large outputs off the platform, read what RunPod's pricing page says about data transfer so a result download isn't a surprise line. Review volumes monthly and delete what no active job reads.
RunPod spend limits, quotas and GPU availability
An $80/hr spend cap limits how fast an account can burn money. It protects you from a runaway job but also caps how many high-end GPUs you can run at once.
When a burst of requests arrives, it queues behind three workers, because serverless endpoints start with 3 maximum workers according to Docs, and each waiting request adds latency.
Cold starts compound this: a worker that spins up from zero spends billed seconds loading the model before it serves anything.
RunPod Support ties the worker limit to account balance:

- According to RunPod Support, up to 10 workers needs a $100 minimum balance.
- Up to 20 workers needs $200.
- Up to 30 workers needs $300.
That works out to $10 of held balance per worker, so a team that wants 30 parallel workers must keep $300 parked in the account before the first job runs.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
RunPod against Lambda, Modal and Vast.AI on cost
RunPod's H100 rate sits below Lambda's and above Vast.ai's lowest listings, but the hourly figure alone won't decide a month that starts with $300 already parked in the account.
Comparison table
The table below puts each provider's H100 rate next to how it meters time and what it does with idle storage.
Read the rate column last: billing granularity and storage decide how much of the rate you actually pay for. RunPod figures date from October 2026.
| Provider | H100 hourly rate | Billing granularity | Storage | Serverless | When cheaper |
|---|---|---|---|---|---|
| RunPod | $2.89-3.99 | Per second | Volumes keep billing while pods are stopped | Yes | Bursty jobs that stop on their own |
| Lambda | $4.29 | Per minute | Persistent filesystem billed per GB | No | Steady, long-running training |
| Modal | Metered by usage, no fixed hourly rate | Per second | Volumes billed separately | Yes, its core model | Spiky inference with idle gaps |
| Vast.ai | From $1.33 | Per second | Billed while the instance exists | Yes | Fault-tolerant work on marketplace hosts |
Rates move fast. SemiAnalysis tracked the cheapest on-demand H100 at $5.78 per GPU-hour in the first quarter of 2024, then $4.77 in the second, $4.44 in the third and $3.90 in the fourth.
That's a fall of about a third in a year, so any rate you copy into a budget today has a short shelf life.
A quote older than a quarter is a guess.
The comparison therefore turns on what each provider charges for time you aren't computing.
When RunPod is not the cheapest choice
On raw rate, Vast.ai wins. At $1.33 against RunPod's $2.89 floor, a 500-hour month on one H100 costs $665 against $1,445. That's a gap of $780. You pay for it in host variability, so it suits work that can restart from a checkpoint.
Lambda has the highest rate in the table, at $4.29. A team running one job around the clock gains nothing from per-second billing, and a flat, predictable rate is easier to budget.
When traffic is uneven, Modal beats a rented pod. If a GPU would sit idle 70% of the day, Modal charges only for execution seconds, which costs less than any hourly rate, however low.
RunPod is cheapest in the middle: jobs that start, finish and shut the pod down.
Automating RunPod shutdowns and spend alerts with Activepieces
When a pod is forgotten, it keeps billing, and Activepieces can watch for it: a check that runs hourly is 720 runs in a 30-day month at 1 credit each, which fits inside the Free plan's 1,000 credits if you leave out the optional AI steps.
It can run a schedule, ask RunPod which pods are still up, stop the ones past a set time and tell your team, but it doesn't replace the controls RunPod already has.
What RunPod already controls natively
Start with what the platform does itself, because a workflow you build on top should cover only what these leave open. RunPod lets you set an account-level spending limit and gives you balance-based alerts.
You can also set a pod to stop itself by ending the process it runs, so a job that finishes shuts its own pod down. That's the cleanest option, and it belongs inside the job script.
The gap is the pod nobody told to stop. A spend limit caps total damage, so a forgotten pod's cost has a ceiling. But the limit acts only after the money is gone and often blocks the work you wanted to keep running too.
A balance alert says the account is low, not which pod caused it. Neither one looks at a pod and asks whether it has been up longer than any job should take.
A scheduled workflow that stops idle pods
That question is a clock check, and a clock check is what a scheduled flow does well. The flow below runs on a timer, fetches the list of pods from RunPod's API, loops through them, and compares each pod's start time against a cutoff.
It sends the old ones a stop request, then logs the result and emails the team.
The canvas shows the full chain: a schedule trigger feeding Google Sheets, a loop, a date helper, an HTTP request, two AI steps and a Sheets insert.
After that come a router with a Branch 1 path and an Otherwise path, and a Gmail send step.
Read the router as the decision point: pods past the cutoff go down one branch to be stopped and reported, everything else falls through untouched.

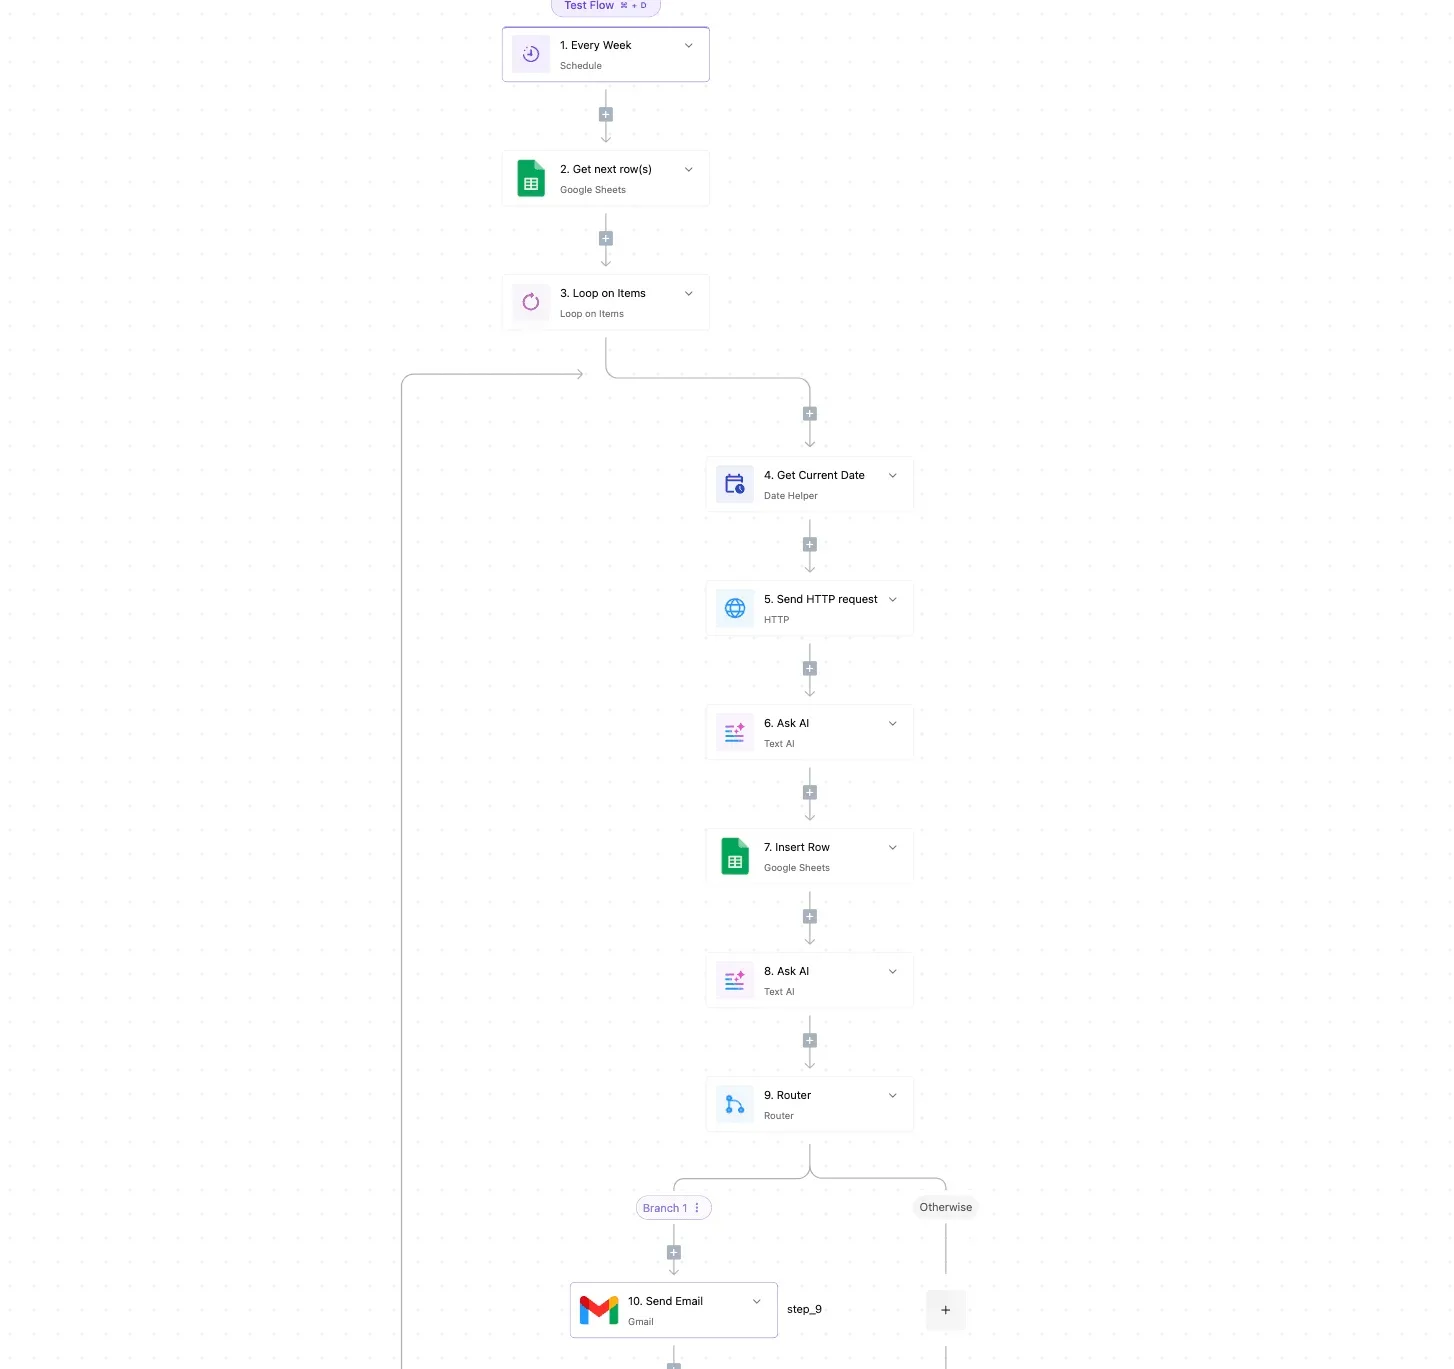
Of all the steps, the HTTP request matters most, since it calls RunPod's API directly, so you need an API key stored as a connection rather than pasted into the flow.
The AI steps are optional. They can write the alert in plain language, but the stop decision should rest on the date comparison, not on a model's judgment.
You don't have to build that chain by hand.
Describe it in Activepieces' built-in chat (list the pods past the cutoff, stop them, email the team) and what comes back is a live flow in your account, the same artifact a builder would have assembled, running under the same RBAC and audit logs as every other flow.
Its run trace shows each step's outcome, from the HTTP call to RunPod through the router to the Gmail send, so you can read exactly what happened on every run. MoneyGram, Moneypenny, Alan and FundingSocieties run Activepieces in production.
Be clear about the limits. The flow only helps if it runs, so a failed schedule leaves you back where you started. It also can't tell a pod that is training from one that is idle, because start time isn't activity.
If the cutoff sits below your longest legitimate job, you'll stop real work, so keep it above. Use it as a backstop to the job's own shutdown, not a substitute.
Five checks before your next RunPod run
Run five checks in that order, because each one catches what the previous one can't. Set a spend limit, label every pod, clear stray volumes, choose pod or serverless per workload, and recheck rates.
The list below runs from the account level down to the single workload.
- Set the account spend limit, so a forgotten pod hits a ceiling instead of your card.
- Label every pod with an owner and a stop time, so anyone reading the console knows who to ask and when it should be gone.
- Delete unused volumes, because storage is metered whether or not a pod is attached.
- Choose pod or serverless per workload, using the worked example's logic: pods for steady, long sessions, serverless for bursty jobs.
- Recheck the pricing page, since the rate you budgeted against may not be today's.
The order matters because the first two steps limit damage, while the last three lower the bill you would otherwise pay on a good day.
Do steps one and two here. The spend limit is the only control that works when everything else fails, including your own labels. A label is a promise from a person; a limit is a rule the account enforces.
Write the owner and stop time into the pod name or tag at creation, not afterwards, because "I'll tag it later" is how an unowned pod runs for a weekend.
During the run
Step four belongs here, since the choice shows itself once the job is running.
If the pod sits idle between bursts of work, you're paying the per-second rate for time that produces nothing, and that points to serverless, where the metered unit is the request's execution time.
If the GPU stays busy for hours, the pod's continuous rate is simpler to predict. Compare the stop time on the label with the real finish; a gap means your estimate was wrong and the next budget should reflect it.
Month-end RunPod storage and pricing review
Steps three and five close the loop. List every volume and match each to a live project; anything without a match is a recurring charge buying nothing, so delete it. Then open the RunPod pricing page and compare it with the rates in your budget.
A GPU that was cheapest last month may not be this month, and the listed rate only matters once you know how long the job really ran.
Frequently asked questions
Does RunPod have a free tier or free credits?
Budget as if every running second is billed, because RunPod's pricing page doesn't describe a permanent free tier for GPU time. Any credits arrive as promotions or referral offers, which can change, so treat them as a bonus and not a line in your plan.
Check the current offer on the pricing page before you rely on one, and before you plan a month around it.
Is RunPod billed per second or per hour?
Compute is billed per second, according to RunPod's pricing documentation, so a short job isn't rounded up to a full hour.
That helps only if the pod stops when the work does. If a pod runs overnight, you're billed for every second of the night, whether or not it did anything.
Storage is metered separately from compute, which is why the next question matters.
Do I pay for a pod that is stopped?
Stopping a pod ends the GPU charge, but the disk is still billed. RunPod's storage documentation says a stopped pod keeps its volume, and a kept volume has a rate.
The stopped pod costs far less than a running one, but it never reaches zero until you terminate it, which deletes the data. Copy out what you need, then terminate.
Is Community Cloud less reliable than Secure Cloud?
By design, Community Cloud carries more availability risk. RunPod describes it as capacity from vetted individual hosts, and Secure Cloud as capacity in its partner data centers with stronger guarantees.
Community Cloud is usually the cheaper listing, so the rate gap is what you get paid for accepting that risk.
For a job that checkpoints often and can restart, the risk costs little. If a job loses hours of work when interrupted, a rerun can cancel the saving.
Can I get a lower rate for committed usage?
Yes, for some GPUs. RunPod's pricing page lists savings plans and reserved capacity as ways to trade a commitment for a lower rate. The discount depends on the GPU and the term, so read the exact terms for the card you use.
If the pod doesn't run, a commitment is still a fixed charge. It pays off only when your real utilization is high and steady, and it repeats the idle-pod problem at a larger scale if your workload is bursty.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales