Azure OpenAI Pricing in 2026: Batch, Standard & PTU

Oct 28, 202614 min read
Azure OpenAI bills per token by default, with provisioned throughput units (PTUs) as a reserved, fixed-fee alternative.
It's Microsoft's hosting of OpenAI models inside Azure, so you buy it through your Azure account, and the usage it generates shows up on the same invoice as everything else, even when the calls come from workflow tools like Activepieces.

Azure OpenAI pricing is the set of charges for using OpenAI models through Microsoft Azure, made up of per-token rates for pay-as-you-go and batch deployments, fixed hourly fees for reserved PTU capacity, and the costs of the Azure services around them.
The deployment type you pick moves the bill more than the model does.
Check your real Azure OpenAI costs
The example workload's monthly bill by deployment type
Take Dana, a freelancer whose document-summary service sends 300 million input tokens and 60 million output tokens a month, 360 million in all.
The deployment type you pick moves the bill more than the model does.
According to Platform, on Global Batch, where requests queue and results come back within a day, her bill is $1,200 a month. That's half of Global Standard.
$2,400 is what Global Standard costs her, and answers return immediately.

Price Azure OpenAI reserved capacity at your volume
$3,900 a month buys the minimum 15-PTU Global reservation, which is the most expensive option at her volume.
At her volume it's 1.6 times Standard and 3.25 times Batch, so reserving capacity only pays off once traffic is steady and heavy enough to fill it.
(chart)
Costs beyond the model line
Storage, search, networking and logging inside Azure each add their own charges.
So does the tool that calls the model.
Activepieces has an Azure OpenAI integration and runs on the key you already hold, so the deployment type and the rate you negotiated with Azure carry straight through and the tokens land on your Azure bill, not ours.
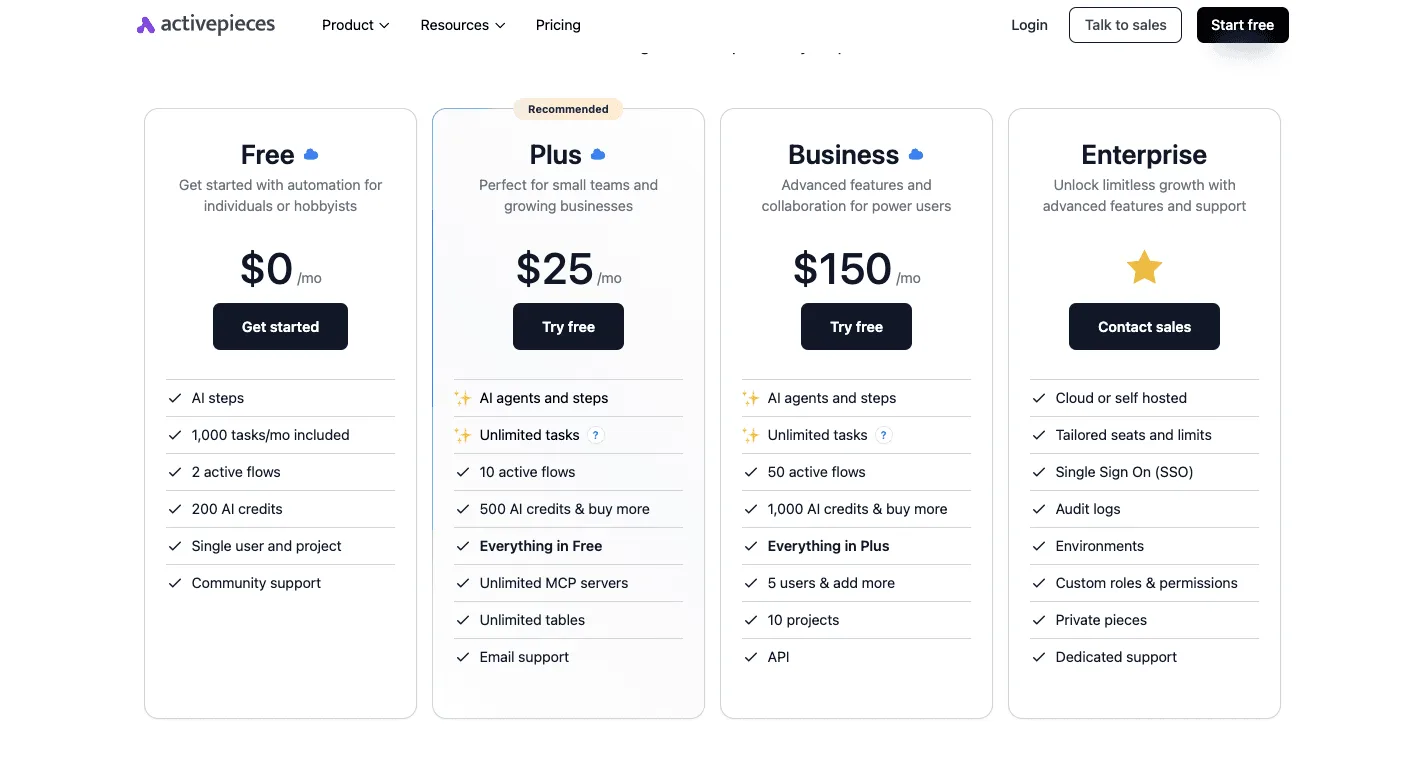
Its Plus plan is $20 a month with bring-your-own-key, and each AI step then costs 1 credit, which keeps the automation's cost on its pricing page and the model's cost on Azure's. Tally both lines before you decide a deployment type is cheap.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Compare Azure OpenAI deployment options
Which deployment type is cheapest depends on how steady your traffic is:
- pay-per-token suits uneven use
- reserved capacity suits constant use
- Batch suits work that can wait
The table below compares the six types on what you are billed for and what you are held to. Cells marked "unverified" are ones I couldn't confirm against Azure's pricing page, so check them before budgeting.
| Type | Price unit | Included | Quota limits | Commitment | SLA |
|---|---|---|---|---|---|
| Global Standard | Per token | Shared capacity, any region | Per-model tokens-per-minute cap | None | Unverified |
| Data-zone Standard | Per token | Processing kept in a US or EU zone | Separate per-zone cap | None | Unverified |
| Batch | Per token, discounted (rate unverified) | Results returned later | Separate queued-token quota | None | None on speed |
| PTU hourly | Per PTU-hour | Reserved capacity | Set by PTUs you hold | None | Latency target (unverified) |
| PTU reservation | Per PTU, term-priced (unverified) | Same capacity, lower rate | Same as hourly | Fixed term | Same as hourly |
| Fine-tune hosting | Per hour deployed (rate unverified) | Your custom model | Unverified | None | Unverified |

Prices and plan limits checked against docs.claude.com and claude.com and openai.com and gemini.google on October 27, 2026.
What the table does show is that Global and Data-zone Standard share a billing unit, so the choice between them is about where your data may be processed, not a different way of paying.
Provisioned throughput units, hourly versus reserved
About 80% more is the price of keeping processing inside one region, which is what Regional costs, so single-region processing is 80% more expensive.
The figures, from Flexprice, are $1.10 per PTU-hour for Data Zone provisioned capacity and $2 for Regional, which means Regional costs nearly double per hour.
Per Learn, left running all month (about 730 hours), one PTU comes to roughly $803 in a Data Zone and $1,460 Regional, whether or not anyone sends a request.
Determine when PTU costs less
The direct answer and check date
Only when your traffic is steady and heavy enough to keep the reserved capacity busy around the clock do provisioned throughput units (PTU), Azure's reserved-capacity option, win on cost. Below that, pay-as-you-go is cheaper.
Microsoft's PTU figures were checked against its pricing page on 28 October 2026. Pull the current numbers from Microsoft's pricing and PTU documentation on the day you decide, since both change.
One number could sink this article's thesis: the break-even. If your monthly token volume, priced at pay-as-you-go rates, exceeds the monthly cost of the PTUs needed to carry your peak load, PTU wins and I'm wrong for your workload.
Price your real monthly tokens at the pay-as-you-go rate. Price the PTUs that cover your busiest hour, for every hour of the month. Then compare.
For a fair comparison, count:
- Token charges on pay-as-you-go or batch.
- Reservation charges for PTUs, billed for every hour whether used or not.
- Overflow traffic that spills to pay-as-you-go when you exceed reserved capacity.
- Engineering time spent sizing and re-sizing the reservation.
Compare Azure OpenAI pay-as-you-go versus PTU
Pay-as-you-go wins unless your traffic keeps a provisioned reservation busy nearly all day, because you pay for the reservation whether or not you send a single request.
Find the PTU utilisation break-even point
Even a reservation used to the hilt saves little. Cld2day puts GPT-4.1 at $1.98 to $2 per 1M tokens, so a fully used reservation saves about a cent or two, which won't cover the effort of managing it.

Cld2day's figures had GPT-4o at $2.37 to $2.5, a saving of roughly five percent at best. Cld2day puts GPT-5 at $1.25 to $1.25, meaning full use saves nothing per token.
It plots the effective cost per 1M tokens of a fixed 15-PTU reservation at 10, 25, 50, 75 and 100 percent utilisation against the flat Standard rate of $5 input and $15 output, so you can see at what point a reservation becomes cheaper than paying standard rates.
Know when Azure OpenAI PTU is right
There are two cases where provisioned throughput earns its place. The first is steady, round-the-clock volume, such as a queue that never empties, where the reservation stays close to full and the small per-token saving at least arrives.
The second is a latency promise: if a customer-facing feature must respond in a consistent time and can't tolerate pay-as-you-go slowing under shared load, you are paying for predictability, not a discount.
If neither describes you, stay on pay-as-you-go and revisit when your measured utilisation holds high for weeks.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
Spot hidden costs and quota limits
Watch Azure OpenAI quota and rate limits
Hit the cap on tokens per minute or requests per minute and requests fail, so a busy launch day can break your product before it raises your bill.
When a compliance requirement applies, every token you buy quietly costs more, because data-zone deployments, which keep processing inside a geographic boundary, carry a price uplift over the global option.
Whether anyone calls it or not, a fine-tuned model is billed for every hour it sits deployed.
Surrounding Azure services on the same invoice
Logging is the usual surprise: storing request and response logs in Azure's monitoring service is billed by the gigabyte, and chatty applications generate a lot of them.
Content safety filtering, private networking and extra regions each add their own lines, so switch on only the logging you'll actually read.
Support plan costs
You get basic support included, but fast response times from a human sit on paid plans that charge monthly, whatever your usage.
If your product earns money while the model is down, buy the plan. If it's an internal tool, skip it and keep the monthly saving.
Check Azure OpenAI versus competitors
The table below compares four routes on the five things that set the bill; the takeaway is that Azure's distinguishing features are its reserved capacity and its regional controls, not a cheaper rate.
| Rate per 1M tokens, comparable model | Reserved capacity | Batch discount | Data residency | Rate-limit model | |
|---|---|---|---|---|---|
| Azure OpenAI | Listed per model, and changes with deployment type | Provisioned throughput, bought ahead | Separate batch deployment type | Choice of Azure region or wider data zone | Quota per subscription, region and model |
| OpenAI API | One list rate per model | Committed capacity arranged with sales | Batch API at a reduced rate | Limited regional choice | Limits per account tier, rising with usage |
| Anthropic API | One list rate per model | Committed capacity arranged with sales | Batch API at a reduced rate | Limited regional choice | Limits per organization tier |
| Google Vertex AI/Gemini | Listed per model | Provisioned throughput | Batch prediction at a reduced rate | Regional endpoints | Quota per project and region |
Azure OpenAI versus the OpenAI API
For the same model, the two vendors are close enough on token rate that the rate shouldn't decide it.
What differs is what surrounds the tokens. Azure makes you ask for quota before you can use a model, and if your traffic outgrows it, requests fail until you get more. The OpenAI API loosens its limits as your account spends more.
In return, Azure lets you pin data to a region and buy reserved capacity, which matters only if your traffic is steady enough to keep it busy.
Compare Azure OpenAI with Anthropic and Google
On Anthropic, a small team gets running with no quota paperwork, because it sells its models, such as Claude Sonnet 5.5, directly with tiered limits.
Google's Vertex AI, its cloud route to Gemini, works much like Azure: quota per project, regional endpoints, reserved throughput.
Assess token usage first
Log a week of real token use, price it on pay-as-you-go, cap the spend, and only then ask whether reserved capacity is worth it.
Measure, then price
- Log token use per call for one week, recording the date, which workflow made the call, and tokens in and out.
- Price the totals on Standard, which is Azure's pay-as-you-go deployment, where you pay only for tokens used. Multiply your logged totals by the posted rate and scale to a month. That's your baseline, and anything else has to beat it.
- Set a budget alert and a TPM quota. An alert in Azure cost management emails you when spending crosses a line you choose. TPM, tokens per minute, is the quota that caps how fast a deployment can consume. Together they mean a runaway loop stops at a ceiling you picked, not at the end of the month.
- Defer PTU until utilisation is proven. PTU, provisioned throughput units, is reserved capacity you pay for whether you use it or not. If your logs show steady, heavy traffic, reserving can make sense. If they show gaps, you're paying for idle capacity.
- Cost the automation around the model, because the model call is rarely the whole job. Add it to the baseline, or your estimate will come in low.
What Activepieces does about this
The part of the bill Activepieces touches is the automation around the model, and we leave the deployment-type decision with you.
Our Azure OpenAI integration runs on the key you already hold, so whichever deployment you chose (Global Standard, Batch or a PTU reservation) and whatever rate you negotiated with Azure carry straight through. The tokens land on your Azure invoice, not ours.
We don't resell the model, so we never pick one for you or mark it up.
That gives you two lines to price instead of one blurred together. On the Plus plan, at $20 a month with bring-your-own-key, each AI step costs 1 credit, and that is the whole of what Activepieces charges for the call.
The model's cost stays on Azure's pricing page and the automation's cost stays on ours, so the baseline in the measuring steps above can be built from two figures that don't overlap.
The code is open as well. Activepieces is MIT-licensed at its core, so you can self-host the flows that trigger your model calls and keep the orchestration out of the surrounding Azure services (storage, networking, logging) that add lines to the invoice.
If a flow can wait overnight, you can point its Azure OpenAI step at a Batch deployment and let it run at the half-price rate from Dana's example, while a customer-facing flow stays on Standard.
We don't set your quota, lower your token rate or tell you whether a PTU reservation will fill. Those stay with Azure and your logs.
What we can do is make the flow that spends the tokens easy to see, change and switch off, and you can reach it from Claude, ChatGPT, Cursor or any MCP client.
Frequently asked questions
Free tiers and pricing against the OpenAI API
Is there a free tier for Azure OpenAI?
No standing free tier exists for the service itself. New Azure accounts have sometimes come with starter credit you can spend on it, so a first experiment may cost you nothing, but once that credit is gone, every token is billed.
Check what your account actually includes before assuming anything is free.
Does Azure OpenAI cost the same as the OpenAI API?
Per-token list prices for the same model are often close, but your bill isn't. On Azure you also pay for the deployment type you choose and for the services around it, such as storage, networking and monitoring.
Compare total monthly cost on your own usage, not the price per token.
Billing for testing and switching deployment types
How is Azure OpenAI billed if I only test occasionally?
Pay-as-you-go deployments bill only for tokens you send and receive, so a quiet week costs close to nothing. The exceptions are anything billed by the hour, such as provisioned capacity and hosted fine-tuned models, which charge whether or not anyone is using them.
Can I switch between pay-as-you-go and PTU later?
Yes, but it's a new deployment, not a setting you flip. You create the provisioned deployment, point your application at it, then retire the old one.
Any reservation discount is a separate commitment, so make it only after real usage tells you the volume is steady.
A few smaller questions come up often enough to answer in one line each:
- A free trial of the service itself isn't guaranteed; only promotional account credit might apply.
- Batch doesn't require provisioned capacity. It's its own deployment type.
- You can run provisioned and pay-as-you-go deployments side by side, for example steady traffic on one and overflow on the other.
- A fine-tuned model that sits deployed but idle still accrues an hourly hosting charge.
- Token prices can differ by region and by whether the deployment is regional or global, so check the one you'll use.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales