Best AI for Coding 2026 Ranked by Real Performance
The best AI for coding tools are ranked by their reasoning capabilities and IDE integration. Developers can choose the platform that matches their stack.
Covers credential sprawl from unsanctioned tools: access risk, exposure tradeoffs, and controls that hold up under audit.
ContributorSeptember 26, 202613 min read
This article was researched and fact-checked by an advanced research system.
As software development evolves, the integration of artificial intelligence has shifted from a luxury to a fundamental necessity for maintaining competitive velocity.
The best AI for coding in 2026 leverages deep contextual awareness to automate boilerplate, refactor legacy systems, and even orchestrate complex workflows, much like how developers use Activepieces to automate their internal business logic, ensuring that engineers spend less time on repetitive syntax and more on high-level architecture.
This year’s top-ranked tools distinguish themselves through superior reasoning capabilities and seamless IDE integration, providing a significant edge in both individual productivity and team-wide scalability. Selecting the right platform requires balancing raw performance with the specific nuances of your tech stack and security requirements.
AI for coding refers to a category of software development tools, ranging from autocomplete plugins to agentic IDEs, that utilize large language models to automate code generation, debugging, and architectural reasoning.
Top AI coding tools for 2026
A shift from predictive text to agentic reasoning defines the 2026 coding landscape. Cursor, Claude 3.7, and GitHub Copilot address distinct operational needs ranging from deep architectural logic to enterprise compliance.
While simple autocomplete remains a commodity, these three tools represent the current standard for integrating large language models directly into your software development lifecycle.
The top three tools at a glance
The current market hierarchy reflects a trade-off between autonomous capability and organizational control, as shown by the following primary use cases:
- Cursor: Best for Agentic IDE workflows.
- Claude 3.7: Best for complex logic and reasoning.
- GitHub Copilot: Best for Enterprise security and integration.
No single model provides both the highest reasoning capability and the lowest administrative risk simultaneously. Selecting a tool now requires you to weigh the cost of compute against the precision of the output.
No single model provides both the highest reasoning capability and the lowest administrative risk simultaneously.
This is particularly true as you move toward complex automation via platforms like Activepieces, which uses an MIT-licensed core to bridge the gap between code generation and system deployment.
How to choose based on your stack
Directly impacting the feasibility of high-frequency agentic loops, operating costs for these models vary significantly. According to ModelPricing, Claude 3.7 Sonnet is priced at $3.00 per 1M tokens. This represents a 20% premium over GPT-4o at $2.50 per 1M tokens.
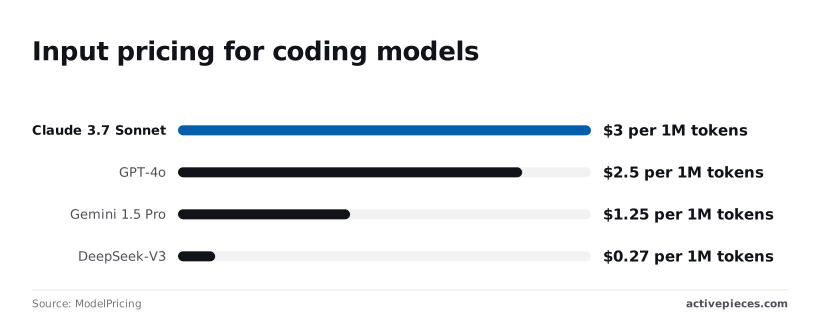
Tokonomics reports that if you're optimizing for high-volume, lower-complexity tasks, you may find Gemini 1.5 Pro more sustainable at $1.25 per 1M tokens, effectively halving the expenditure compared to the premium alternatives.
For projects where cost is the primary constraint, DeepSeek-V3 has the lowest entry point at $0.27 per 1M tokens, allowing for massive scaling without reaching the budget limits of more expensive providers.
Everything below works on Activepieces' free plan. Start without code or a credit card.
Compare Claude 3.7 and GPT-4o logic
Claude 3.7 Sonnet currently holds the highest performance marks for agentic coding tasks. Its reasoning capabilities allow it to resolve GitHub issues without human intervention more reliably than its predecessors. While low-cost models handle syntax, these reasoning models manage the logical flow of entire features.
Claude 3.7 Sonnet: The current gold standard for coding logic
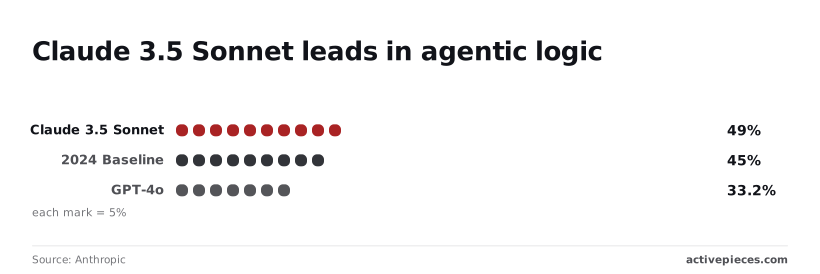
On SWE-bench Verified, Claude 3.5 Sonnet achieves a 49% success rate. This means it can independently solve nearly half of the real-world software engineering problems presented to it.
This result exceeds the 2024 state-of-the-art baseline of 45%, indicating that the model has set a new standard for performance in the industry.
Claude handles complex logic more effectively than GPT-4o, which trails at a 33.2% success rate on the same benchmark. Consequently, if you're using GPT-4o for deep architectural debugging, you may spend more time correcting logical hallucinations than you would with the Sonnet series.
GPT-4o: Speed and multi-modal documentation parsing
For workflows requiring high-speed iterations and the processing of visual assets like UI mockups, GPT-4o is the primary alternative.
While it lags in pure logic, its low latency reduces the "wait state" during your inner loop. Its multi-modal vision capabilities allow it to ingest a screenshot of a CSS layout error and suggest a fix, a task that text-only models cannot perform.
Token costs and API limits for developers
Integrating these models into an IDE like Cursor introduces specific operational costs and rate limits that dictate how often you can utilize high-reasoning modes.
| Model | Input Cost (per 1M tokens) | Output Cost (per 1M tokens) | Context Window |
|---|---|---|---|
| Claude 3.7 Sonnet | $3.00 | $15.00 | 200,000 tokens |
| GPT-4o | $2.50 | $10.00 | 128,000 tokens |
| DeepSeek-V3 | $0.27 | $1.10 | 128,000 tokens |
Claude 3.7 Sonnet’s higher price point reflects its heavier compute requirements for reasoning. The 200,000-token context window in Claude allows for the ingestion of larger documentation sets in a single prompt.
Integrated Development Environments: Why Cursor leads the pack
When an IDE uses native integration, it bypasses the latency and context-loss inherent in traditional plugin APIs. The IDE can then treat your entire repository as a single, queryable data structure.
Cursor: The power of native codebase indexing
By maintaining a local index of your entire codebase, Cursor achieves superior refactoring accuracy. This ensures that every code generation step accounts for cross-file dependencies and internal library calls.
By embedding the AI directly into the forks of the VS Code source, the system can monitor file tree changes in real-time. You no longer need to manually copy-paste context into a chat window.
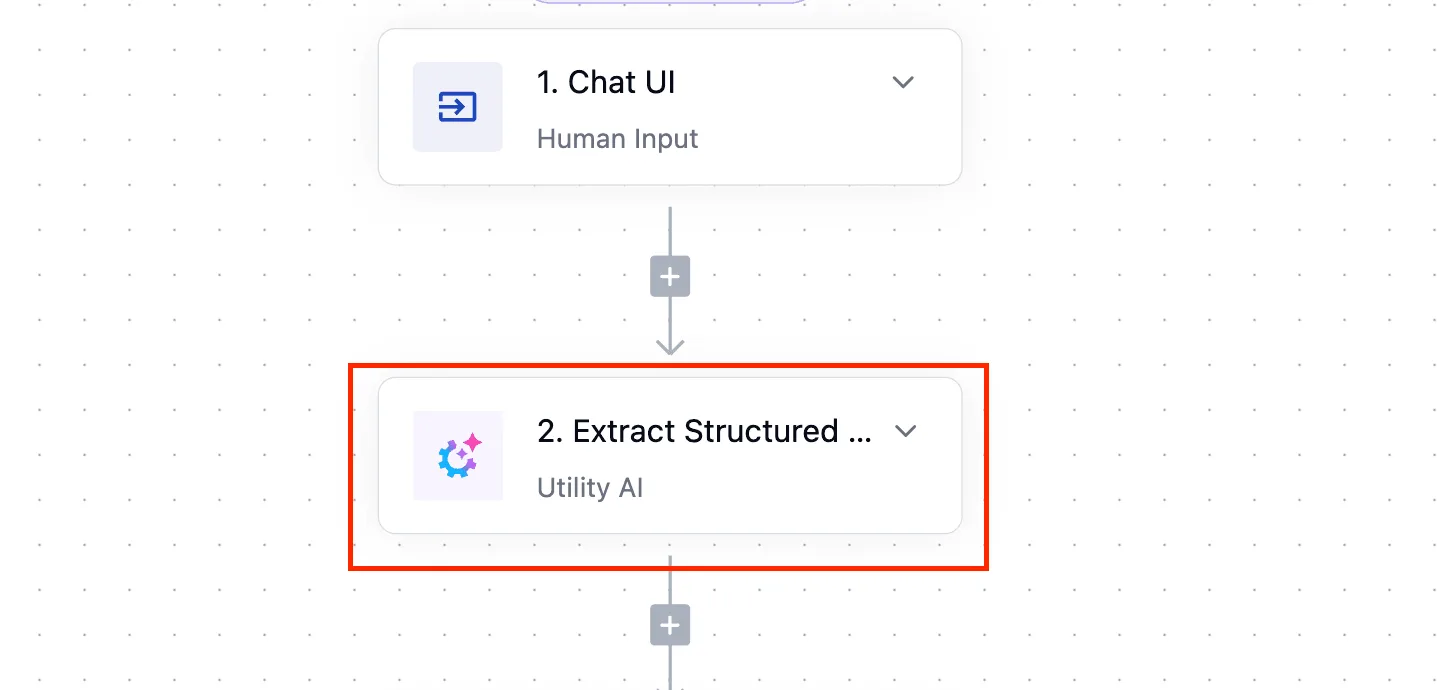
Because the IDE-native model can see the pending state of the whole project, it eliminates the "contextual drift" that occurs when a plugin loses track of unsaved changes.
Windsurf: a new contender for agentic workflow
Windsurf has emerged as a significant alternative to Cursor by focusing on a concept called Flow. This agentic IDE treats the developer and the AI as a single unit, allowing for a more fluid transition between manual coding and autonomous agent actions.
The tool uses a deep understanding of the development context to act as an independent agent that can execute complex multi-step tasks.
Replit Agent: rapid prototyping for full-stack builds
Replit Agent represents the fifth pillar of the 2026 stack, focusing on zero-to-one deployment. While Cursor excels at modifying existing enterprise codebases, Replit Agent is designed to build and host entire applications from a single natural language prompt.
GitHub Copilot: The reliable enterprise standard
GitHub Copilot operates as an extension within existing environments like IntelliJ or VS Code. If you prioritize centralized policy management over deep agentic autonomy, this serves as a standardized security layer.
This plugin-based approach allows your IT department to deploy AI assistance across a variety of pre-approved development environments. While it lacks the deep file-system control of a native IDE, it integrates directly with GitHub’s broader ecosystem to mitigate intellectual property risks.
Pricing and usage limits as of May 2025
The cost of agentic development is structured around the trade-off between unlimited low-latency completions and restricted access to high-reasoning models.
Cursor has a free tier for individual exploration. It also has a Pro tier for individual professional use with a monthly quota of high-reasoning model requests, and a Business tier that adds centralized billing and administrative controls.
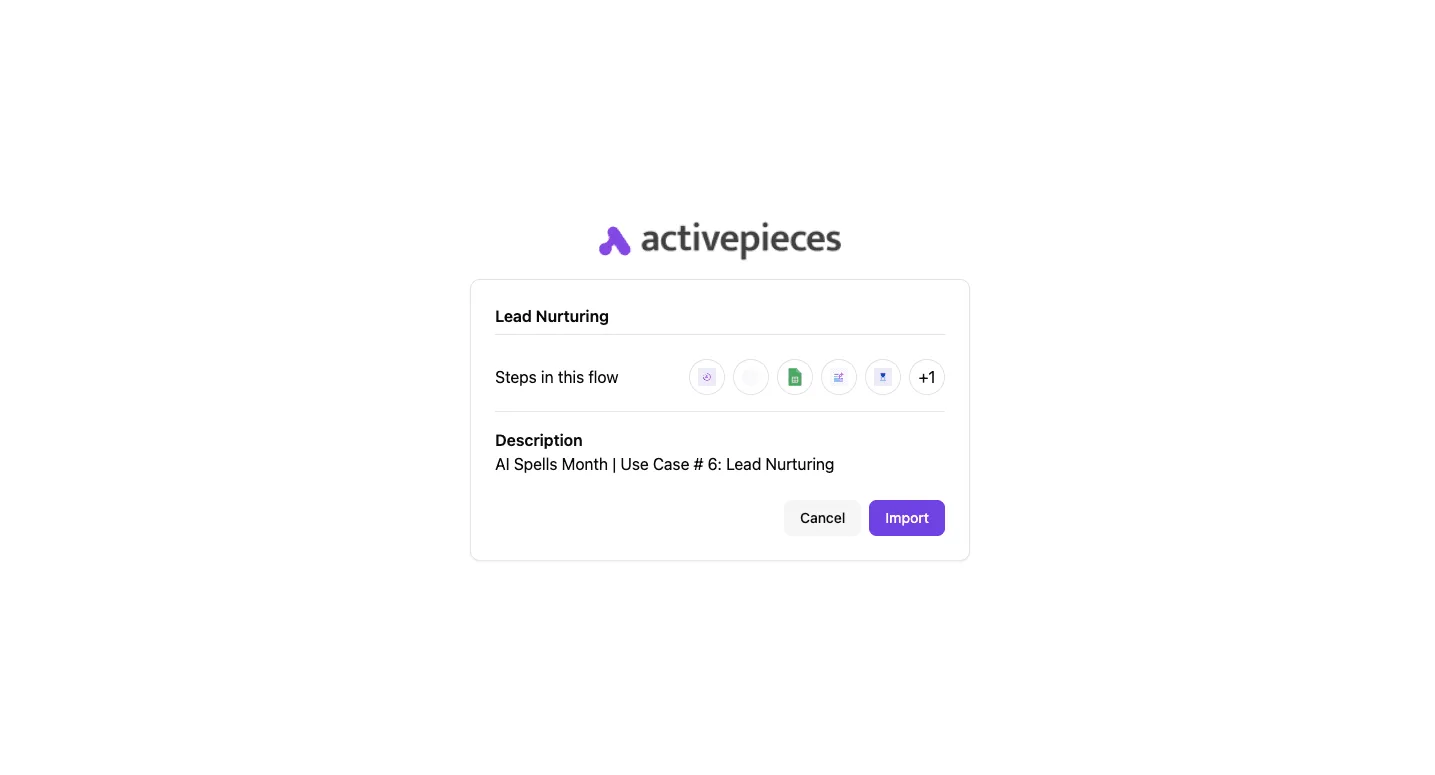
GitHub Copilot has a two-tier structure consisting of an Individual plan for single users and a Business/Enterprise plan. This plan includes seat management, audit logs, and the ability to exclude specific repositories from being used for model training.
Easier to see it running than to read about it: set it up free, no card.
The economics of AI: comparing API input costs
Why DeepSeek-V3 is disrupting the market
By offering a high-reasoning model at a price point significantly lower than the established industry benchmarks set by OpenAI and Anthropic, DeepSeek-V3 alters your procurement strategy.
This reduction in overhead means you can increase the frequency of your automated unit testing. If you're using a "Bring Your Own Key" configuration in an IDE, you can effectively double your daily prompt volume for the same capital outlay.
Balancing model intelligence with token budgets
Selecting a model for agentic workflows requires a deliberate trade-off between the sophisticated logic of Claude 3.7 and the operational speed of lighter models like GPT-4o mini.
To mitigate financial risk, you should implement a tiered routing strategy where a high-cost model handles architectural decisions while a cheaper model manages repetitive boilerplate.
The hidden cost of long-context windows
Large context windows allow an agent to ingest an entire codebase, but this increased data volume exponentially raises the cost of every subsequent prompt within that session. Every file included in the context is re-billed as input for every new turn.
By maintaining a lean context, you avoid the "context tax" where you pay to send the same static documentation to the provider repeatedly.
Activepieces: Automating the deployment of AI-generated logic
Connecting LLM outputs to 100+ business apps
Activepieces exposes every connected integration as a tool schema on a per-project MCP server, allowing Claude 3.7 or Cursor to execute logic across 735+ apps without a separate builder UI.
By maintaining a lean context, you avoid the "context tax" where you pay to send the same static documentation to the provider repeatedly.
By using pre-built connectors for platforms like Slack, Jira, and Salesforce, you bypass the need to write custom authentication and error-handling boilerplate.
Consequently, you can move from an AI-suggested bug fix to a deployed notification across your engineering stack without manually configuring a single webhook listener.
Building event-driven AI agents without infrastructure overhead
Without the operational burden of managing server clusters or lambda functions, the platform allows for the execution of AI-driven logic in response to system events.
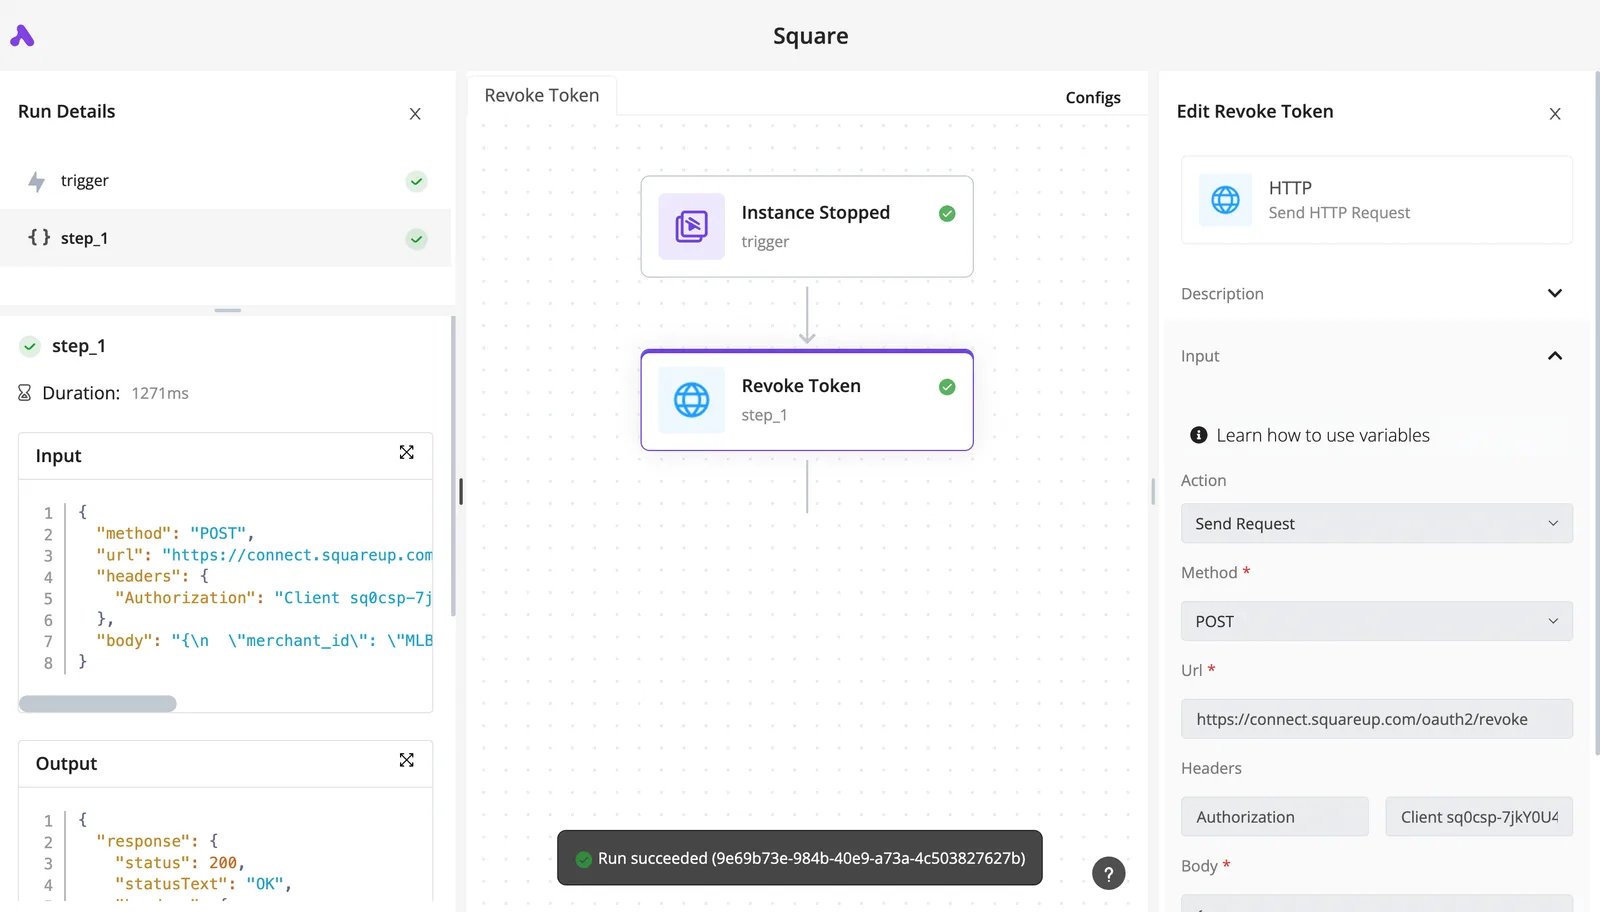
Because Activepieces exposes its 735+ integrations through a per-project MCP server, your coding assistant becomes your automation builder. You can direct Cursor or Windsurf to modify a live workflow via this open protocol, inspecting the resulting tool calls in the run trace.
Self-hosted vs. Cloud options for secure coding workflows
You must choose between the convenience of the Activepieces Cloud managed service and the data sovereignty of a self-hosted Docker installation. Activepieces offers unlimited flows on every plan, including free, while the cloud version handles all scaling and updates automatically.
Self-hosted installations keep all API keys and code execution within your corporate firewall. This setup ensures that sensitive internal logic never leaves your private network, a setup currently used by companies like MoneyGram and FundingSocieties.
By bridging the gap between local coding assistants and a vast ecosystem of business integrations, Activepieces is the better choice for developers who want to deploy AI-generated logic directly into production workflows.
It eliminates the friction of manual configuration by exposing hundreds of pre-built connectors as accessible tools for MCP-enabled agents. This architecture allows you to transform raw LLM outputs into functional, event-driven automations without managing the underlying infrastructure.
Monday morning audit: Optimizing your AI coding stack
An audit ensures that agentic IDEs don't become an unmanaged expense or security liability. Without a weekly review, you risk paying for idle compute while accumulating technical debt through unreviewed automated commits.
Step 1: Measure your 'Acceptance Rate' vs. 'Edit Rate'
A high acceptance rate in Cursor or GitHub Copilot suggests the model is predicting syntax correctly. It only becomes valuable if the edit rate remains low.
The Monday Morning AI Audit is a checklist to stabilize these costs and maintain code quality. Export usage logs from Cursor or Copilot dashboards to identify which teams are generating the most volume.
Identify 'High Inference' users whose compute consumption exceeds the standard seat cost. Prune CLAUDE.md or .cursorrules files that exceed a few hundred lines to prevent the IDE from wasting tokens on outdated instructions.
Rotate API keys and session tokens to ensure that departed contractors no longer have access to the model's reflection of your codebase.
Step 2: Consolidate redundant LLM subscriptions
Managing multiple individual seats for Claude Pro, ChatGPT Plus, and IDE-specific credits creates fragmented billing.
Consolidating these into a team-wide plan under a single provider like Anthropic or OpenAI allows for administrative control over where your training data ends up.
Step 3: Establish data privacy guardrails for AI prompts
Data privacy guardrails prevent sensitive environmental variables or customer PII from being sent to an external inference engine. By configuring the 'Privacy Mode' in Cursor or the 'Data Exclusion' settings in GitHub Copilot, you ensure that local code snippets are processed in-memory and discarded.
Frequently asked questions
Can I use these AI coding tools offline?
Most modern agentic IDEs require a persistent internet connection to transmit codebase embeddings to high-compute models like Claude 3.7.
If you're on a secure, air-gapped network, you can't access the reasoning capabilities that define these tools.
While local-first models like Ollama allow for basic autocomplete without a signal, the lack of cloud-based cross-file analysis prevents the tool from suggesting architectural changes across your entire project.
Does GitHub Copilot own the code I generate?
GitHub’s terms of service for the Copilot for Business tier state that the customer retains ownership of the generated code. This ensures that the intellectual property remains a corporate asset rather than a shared training resource.
This distinction is critical. It prevents your proprietary logic from appearing in the suggestions provided to other companies, mitigating the risk of inadvertent trade secret leakage.
What is the difference between an AI IDE and an AI plugin?
An AI IDE like Cursor is a standalone fork of VS Code that controls the entire file system and terminal. A plugin like the original GitHub Copilot extension operates as a guest within a host editor.
This architectural difference allows the IDE to index your entire repository locally to provide context for every prompt. It can execute terminal commands to debug errors it finds in its own generated code.
It also manages complex multi-file refactors that a standard plugin lacks the permissions to initiate.
Which AI is best for legacy code migration?
Due to its high context window, Claude 3.7 has become the standard for legacy migrations. This allows it to ingest thousands of lines of outdated documentation and code simultaneously.
This capacity reduces the hallucination rate during the translation of COBOL or older Java versions to modern frameworks. The model can see the entire dependency tree instead of guessing at missing functions.