Modal Labs Pricing 2026: GPU Rates, Plans and Credits

Oct 29, 202616 min read
Modal charges for what you use, by the second, with no flat fee for the basic plan, which makes it an easy fit for bursty jobs triggered from workflow tools like Activepieces.
Starter comes with a monthly free credit, and the paid tiers add a plan fee on top of usage.
Modal pricing is the usage-based billing model for Modal's serverless cloud platform, in which you pay per second for the CPU, GPU and memory your code uses, plus any plan fee for the Starter, Team or Enterprise tier you choose.
The sticker's low, but the bill depends on how long your code runs and how long machines sit waiting.
Modal Labs pricing in plain terms
What Modal is, in one paragraph
Modal is a serverless platform: you hand it code, and it runs that code on machines it manages, including GPUs for AI work, without you renting or maintaining a server. You pay while your code's running rather than for a machine that sits there.
Modal suits people who have their own code to run.
How Modal bills: per second, not per month
Four things move the total, and a monthly plan name tells you about only two of them:
- Per-second compute: processor time, memory and any GPU, billed for as long as your code's running.
- The monthly free credit on Starter, which absorbs small workloads and ends where the credit does.
- The plan fee on Team and Enterprise, which is the one predictable line on the bill.
- Idle or warm containers, meaning machines kept switched on so they respond quickly, which bill whether or not anyone's using them.
The list above is why two customers on the same plan can pay very different amounts.
The first three are easy to read off a pricing page.
The fourth is the one people overlook, and a warm GPU left running overnight costs real money while doing nothing. Estimate by what your job's running, how long, and how often it has to be ready.
Everything here was checked against Modal's pricing page, documentation and changelog on 2026-10-29. Pricing pages change, so confirm current rates before you commit to a budget.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Every Modal plan with price, inclusions and limits
As of 29 October 2026 I could confirm only some of the terms of Modal's three plans, Starter, Team and Enterprise, plus credit programs, so the pricing details you'll read are necessarily incomplete. Anywhere I couldn't, the table says "contact Modal" rather than guess.
Ask Modal about every "contact Modal" cell before you budget around it. The table sets the plans side by side on the limits that cause surprise bills.
| Plan | Monthly fee | Free credit | Seats | Concurrency and GPU limits | Log retention | Support | Security |
|---|---|---|---|---|---|---|---|
| Starter | $0 + compute / month | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal |
| Team | $250+ compute / month | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal |
| Enterprise | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal |
| Credit programs | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal | Contact Modal |
Since you pay for compute whichever tier you sit on, the plan matters less than the rates.
Compute rates: GPU, CPU and memory per second
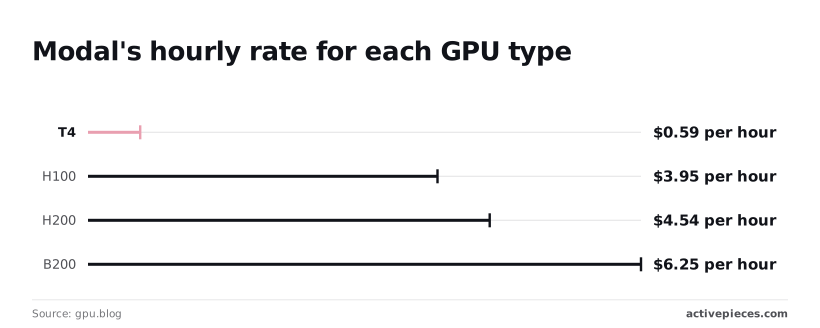
At $0.59 an hour, a T4 suits light jobs, according to gpu.blog, and Modal's GPU rates climb steeply with chip size from there, which means your GPU selection becomes a cost decision as much as a performance one.
An L4's $0.80, an A100 40GB's $2.10 and an A100 80GB's $2.50, leaving your hourly cost entirely dependent on your GPU choice, which means picking the wrong GPU triples your hourly bill.
If you want the newer GPU, you'll pay more per hour: the H100's $3.95 and the H200's $4.54. An H100's nearly seven times a T4, and one left idle for a day costs $94.80, making GPU waste genuinely expensive.
Between February and August 2024 the H100 went from $7.65 an hour to $4.56, according to Modal's own pricing article, so list prices fall substantially.
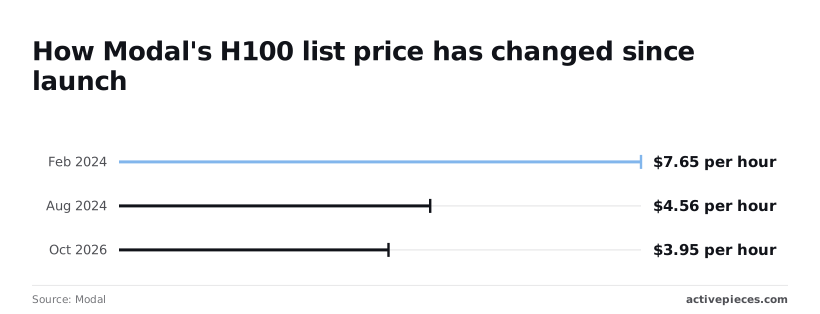
It's $3.95 as of October 2026, about half the early price. A budget built on an old quote overstates your cost, so date every figure you use.
I couldn't verify the amounts or eligibility of the credit programs Modal runs for startups and researchers, so contact Modal. Credits offset the bill without changing the rates, and an idle container still burns them.
What Modal costs at three realistic usage levels
Three bills, one sum: seconds of compute multiplied by the per-second rate, minus credits, plus the plan fee. What changes between them is how many seconds you pay for, which is why the plan tier tells you so little.
The table sets the three workloads side by side so you can see which column does the damage.
| Workload | GPU type | Hours used | Per-second rate arithmetic | Credit offset | Plan fee | Monthly bill |
|---|---|---|---|---|---|---|
| Hobby inference endpoint | Entry-level | Short bursts, plus idle time | Hours × 3,600 × rate | Credits may absorb most of it | Starter | Usage minus credits |
| Team scheduled batch jobs | Mid-range | Fixed windows, run on a schedule | Hours × 3,600 × rate | Credits cover part of it | Team | Usage minus credits, plus fee |
| Production API | High-end | Close to every hour of the month | Hours × 3,600 × rate | Credits barely register | Team | Mostly usage |
Read down the hours column first. The plan fee barely moves from row to row, while hours used and GPU class decide almost everything else. Price your own workload by filling in that row, then check the plan limits.
You pay for a hobby endpoint on Starter for the seconds it runs, and also for the seconds it sits warm waiting for a request.
Credits can hide that for a while. Once they run out, a container you forgot to shut down is the line item that surprises you.
If a small team schedules batch jobs, the estimate is the easiest of the three, because you choose when each job starts and stops. Multiply the length of each run by how many runs you schedule.
The risk is a job that hangs and keeps billing until something stops it, so set a time limit on every job.
Activepieces can start those scheduled Modal runs from a timer or a CRM event, and if the app that should trigger them has no connector, you aren't left waiting on a vendor's roadmap: you can have AI write the missing connector and keep it in your own instance, visible to no one else.
Roughly 60% of its 746 integrations were contributed by the community, and you can count them yourself in the MIT-licensed open-source monorepo on GitHub.
When traffic is steady, production inference keeps the GPU busy or warm nearly all month, so credits become a rounding error and the per-second rate's the bill. Here, picking the cheapest GPU that meets your speed needs saves more than any plan choice.
Hidden costs and limits that surprise Modal users
Past the GPU rate, four things move the bill or stop you cold. They're containers that sit idle while still billed, multipliers for region and preemption choices, plan caps on concurrency and GPUs, and storage and data-transfer charges.
Modal idle time and warm container charges
When your function finishes, the container doesn't vanish. It waits out a scaledown window in case another request arrives, and you pay for that wait as if it were work.
Read the timeline below as a trade: the shaded idle stretch of one container's life is the price of fast responses, and the second lane, a minimum-warm container billed from start to finish, is that price paid in full, around the clock.

Skip the tuning and a bursty workload pays for a lot of waiting. Keep a warm minimum on a GPU function nobody calls at night and you rent that GPU all night.
Modal region and non-preemptible pricing premiums
If you pin a function to a specific region, or require that it never be interrupted, the per-second rate can rise above the listed price.
Treat the headline rate as the floor. If your job can tolerate a restart, leaving it flexible's usually the cheaper setup. If it can't, price in the premium before you commit.
Plan limits on concurrency and seats
Fan a workload out across many inputs and it can hit the ceiling long before it hits a budget. Each plan limits how many containers and GPUs you can run at once, and how many seats you can add.
The cost is time: jobs queue, or you move up a tier just to get room.
Modal storage, data transfer and log costs
Quietly, files you keep in volumes and images accumulate, and data leaving the platform may be charged. Log retention can also be limited by plan.
None of this is large on day one, but nobody watches it, which is how it grows. Check each against your actual data volumes.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
How to keep a Modal bill down
Measure what your jobs actually use, then trim the GPU size, the idle time and the one-at-a-time requests you're paying for. Doing nothing means paying for capacity you never touch, so work through these in order:
- Measure current GPU use on a typical day.
- Right-size the GPU.
- Shorten the scaledown window and tune concurrency.
- Batch requests.
- Set a workspace spending limit and billing alerts.
Put batching on an oversized GPU, for instance, and it just hides the waste, which is why the order matters: each step changes what the next one should be.
Right-size Modal GPU and memory choices
Start with what the dashboard says your functions use, not what you guessed when you wrote them.
Many teams pick a large GPU on day one "to be safe" and never revisit it, so every second runs at the top-tier rate for work a smaller card handles fine.
Change the gpu setting on the function, rerun a representative job, and compare cost per finished job rather than cost per second. Do the same for CPU and memory, which are billed separately.
Tune Modal scaledown window and batching
When a container has finished its work, it stays alive until the scaledown window runs out, and you pay for that waiting. Shorten scaledown_window for spiky traffic, and keep it longer only where a slow cold start would hurt users.

Then let one container serve several requests at once with @modal.concurrent, so you aren't starting a second paid container for work the first could absorb.
Where your model can process many inputs in one pass, @modal.batched groups requests together, which typically costs less than running them one by one.
The day someone ships a loop that never exits, tuning stops being tuning. Set a spending limit on the workspace and add billing alerts below it, so you hear about a runaway job while it's still a small line item.
Modal compared with Replicate, RunPod and Baseten
Because all four bill for GPU time, the real differences are how finely they meter it and what you pay while a container sits waiting.
The table sets the four side by side; read the billing and cold-start columns first, because they decide how much idle time lands on your invoice.
| Pricing model | Billing granularity | Cold-start approach | Best suited to | |
|---|---|---|---|---|
| Modal | Usage-based compute | Per second | Fast container start; optional warm containers | Code-first teams with bursty jobs |
| Replicate | Per second of hardware, or per output on some public models | Per second | Rarely used models start cold | Calling hosted public models |
| RunPod serverless | Usage-based workers | Per second | Scale-to-zero workers or always-on active workers | Cost-driven teams who tune settings |
| Baseten | Dedicated deployments | Per minute | Scale-to-zero configurable | Steady production inference |
Check each vendor's own pricing page for current rates and free credits before you commit. They change often.
Where Modal costs more
Whether or not anyone's calling it, a warm container's billed. Keeping one alive to dodge cold starts turns a pay-per-use bill into a rental. That makes a constant, around-the-clock workload cheaper on a dedicated deployment.
Whether or not anyone's calling it, a warm container's billed. Keeping one alive to dodge cold starts turns a pay-per-use bill into a rental.
Look at the market baseline: H100 rental averaged $8.00 an hour in April 2023, then $5.90 in October 2023, $4.20 in April 2024 and $3.20 in October 2024, showing GPU rental collapsing toward commodity pricing, meaning anyone holding inventory priced at $8.00 is now 60% underwater.

So any quote older than a year probably overstates your cost.
Where Modal costs less
By April 2025 rental prices had reached $2.85, and $2.75 in October 2025. The drop's flattening, so don't wait for prices to fall further. Plan around roughly $2.75 an hour as the going rate, which means you can forecast GPU costs reliably across different workloads.
Per-second billing pays off when jobs are short and uneven. A 40-second task costs 40 seconds, where per-minute billing charges for 60, a 50% premium on that job, so every small iteration carries hidden overhead.
Across thousands of small runs, that gap's the saving, which means billing granularity becomes as critical as GPU choice for batch workloads.
Connect Modal endpoints to business workflows with Activepieces
Activepieces, an MIT-licensed core with 746 integrations, lets people who don't write code start a Modal job from a form, a CRM event or a timer, so you're likely to find your existing tools already supported. It does nothing to Modal's compute or pricing.
Those small runs still bill the way the last section described. What changes is who can start them, and how often.
When a workflow tool fits
Leaving a job in a developer's hands has a cost. Every run waits for someone to type a command, or a script sits on a laptop that has to stay on.
If your job should fire when a customer record changes, or at the top of every hour, a workflow tool does that start for you.
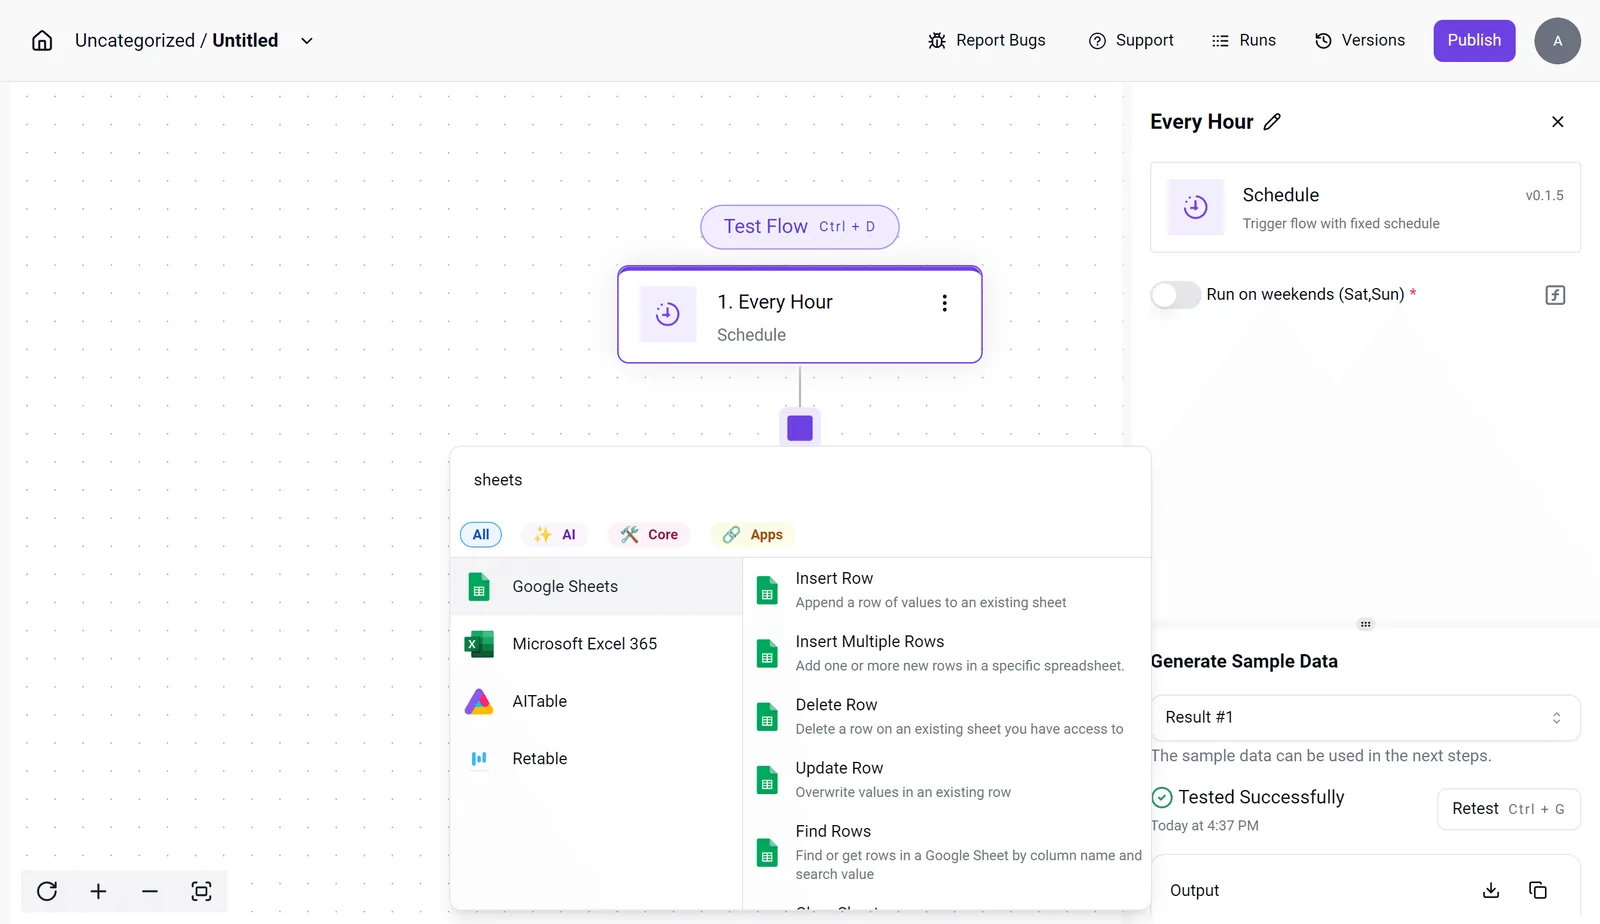
In the screenshot, the builder has a test flow open. A Schedule trigger labeled "Every Hour" is selected, and the settings panel beside it has a "Run on weekends" toggle.
Below the trigger, a step picker lists spreadsheet apps and their actions, such as Insert Row and Find Rows. The "Generate Sample Data" panel shows a successful test.
Take from this that the trigger, the schedule and the test all sit on one screen, so someone in operations can set the timing without opening code.
Every run's compute you pay for, so a job that doesn't need to run on Saturday shouldn't. That is why the weekend toggle matters for your bill. Activepieces has its own plan and charges, separate from Modal's, so count both when you estimate.
What the Modal call looks like
On the Modal side, a developer exposes a function as a web endpoint, which gives it an ordinary web address.
In Activepieces, you add an HTTP step that sends a request to that address, passing along fields from the form, spreadsheet row or CRM record. Modal starts the function, runs it, and returns the result to the next step in the flow.
Two checks keep the estimate honest. Confirm with your developer how long one call runs, since Modal bills by the second. And confirm how often the trigger fires, since an hourly schedule means a call every hour whether or not there's work to do.
Frequently asked questions
A schedule that fires with nothing to do raises a handful of questions, and the short answers are below.
Free use and idle charges
Is Modal Labs free to use? Yes, up to a point. Modal has a free starter plan that includes a monthly allowance of credit, so small experiments can cost nothing.
Once your usage passes that allowance, you pay for what you run, so a workload that looked free in testing can start billing when it moves to a real schedule.
Does Modal charge when my function is idle? Not when nothing's running. Modal bills for compute while a container's alive, so the charge's for containers you have kept warm or that haven't shut down after finishing work.
If you keep containers waiting so requests start fast, you're paying for that waiting, much like leaving a truck idling outside a job site. Check your shutdown and warm-container settings before you leave anything running.
Spending controls
Can I set a hard spending cap on Modal? Look in your workspace billing settings for spending or budget controls before you rely on any.
I wouldn't assume a cap will stop every job at an exact dollar amount. Until you've confirmed how the limit behaves, treat it as a warning and keep an eye on usage during the first weeks of a new workload.
Credits and checking prices
Does Modal offer credits for startups? Modal has offered credits to startups and researchers through application programs. Eligibility and amounts change, so the program's own page is the only reliable source.
Applying costs you a form, while skipping it could mean paying for compute you didn't need to pay for.
How do I check Modal's current prices myself? Open Modal's public pricing page and read the per-second rates for the processors and memory your workload needs.
Then multiply by how long your jobs run and how often they fire. That workload-based estimate will tell you more than any plan name.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales