The Hidden Cost of Historical Data Sync for Automations

Oct 1, 202615 min read
When you first activate a workflow, the system must decide how to treat existing records that already meet your criteria.
Most platforms, including Activepieces which follows standard industry protocols, default to a "forward-looking" approach where the trigger only fires on events occurring after the moment of activation. This prevents a sudden flood of historical data from overwhelming your connected apps or exhausting your task quota.
However, some advanced configurations allow for a "backfill" process, enabling the engine to scan past entries and process them as if they were new.
Understanding this initial behavior is crucial for ensuring data integrity and preventing duplicate entries during the transition from manual to automated processes.
Historical data handling refers to the specific logic or configuration that determines whether an automation trigger processes existing records upon activation or only responds to events occurring after the workflow is live.
Define workflow start points by history
A workflow trigger establishes a temporal boundary that determines which data points qualify for processing and which the system ignores as legacy state.
When a developer activates a logic flow, the runner must resolve the status of every existing record in the source system to prevent a race condition between old state and new updates.
Why webhook triggers skip historical events
When using webhook-based triggers, the system operates on a push-model where the source platform, such as GitHub, sends a payload only when a specific event occurs.
Because the listener does not exist until the deployment point, the workflow effectively treats the entire history of the repository as non-existent. While the listener is real-time, historical data can be forced through it via manual 'replay' features in the source platform.
Services like Shopify or Stripe allow users to backfill events by re-sending old payloads to the active endpoint.
Thousands of alerts for every contribution made since a project started would flood a communication channel if this logic were not in place. The strategy ensures that a new automation designed to notify a team about pull requests remains silent about the past.
The 'index and wait' approach for polling triggers
Polling triggers function by regularly querying an API, like the Salesforce customer relationship management suite, to identify records created after a specific timestamp.
Upon the first execution, the system performs a high-water mark check to establish a baseline. It records the ID of the most recent entry and pauses.
Budget exhaustion occurs when a new flow attempts to treat a five-year-old lead database as a set of new, actionable events.
The run is the meter, not the steps inside it, which is why Activepieces charges 1 credit per flow run regardless of how many steps are executed.
Budget exhaustion occurs when a new flow attempts to treat a five-year-old lead database as a set of new, actionable events.
This published pricing model ensures that a ten-step process costs the same as a two-step workaround, allowing builders to maintain granular logic without being taxed for architectural discipline.
The following timeline illustrates the Backfill Problem. The deployment point acts as a gatekeeper between the dense cluster of historical events on the left and the sparse stream of new events on the right.
If the gatekeeper fails, the system attempts to process the entire left side of the timeline in a single burst.
The 'full backfill' risk for database listeners
Every existing row is often treated as an "Insert" event by default when database triggers monitor Change Data Capture logs or entire tables.
This behavior forces the runner to execute the entire logic branch for every record in the table, which consumes the entire execution quota before the first legitimate new change arrives.
To mitigate this, developers must apply specific filter logic:
- Define a "Start Date" variable within the trigger configuration.
- Compare the record's creation timestamp against the deployment timestamp.
- Drop the execution if the record age exceeds the deployment age.
Without these constraints, the automation engine treats the past as a continuous present, leading to cascading failures in downstream services.
If you are running this arithmetic for your own team, see what the same workload costs on Activepieces.
Standard lookback windows vary by platform
Platform-specific defaults determine the volume of the initial data payload, meaning a single "on new record" trigger can ingest thousands of legacy entries before the first live event occurs.
These defaults rarely align across a tech stack. This lack of coordination creates unpredictable spikes in resource consumption during the initial handshake between services.
Why shopify and HubSpot defaults differ
Shopify, a commerce platform, prioritizes order integrity by fetching recent transactions to ensure the system misses no sales during a connection gap.
To maintain database consistency, HubSpot often defaults to a broader synchronization of contact properties. This causes the automation engine to treat every historical lead as an active trigger.
Because these services serve different operational roles, their native APIs present "new" data through different lenses of recency and state.
The risk of 'hidden' historical records
Hidden records exist in the delta between the record creation time and the moment the user toggles the automation to an active state. The system perceives the entire backlog as a simultaneous burst of activity.
If a user connects a project management tool to a communication app, the system may attempt to send a notification for every ticket ever closed, triggering rate limits on the receiving end.
The automation treats the entire history of the account as a valid queue unless a manual filter is applied to ignore records created before the current timestamp.
How lookback windows impact initial task consumption
Every historical record pulled by the trigger counts as a successful execution, so the size of the lookback window directly dictates the immediate depletion of the monthly task quota.
Initial syncs exhaust the budget before the workflow reaches its first genuine real-time event.
Downstream services may block the automation's IP address due to the sudden high-frequency request volume. Error logs become saturated with legacy data failures, obscuring the performance of new, critical transactions.
Three architectural patterns for managing historical records
Architectural patterns for data synchronization determine whether a workflow processes every legacy record or only those created after the logic is deployed. Choosing a pattern requires balancing the risk of duplicate processing against the computational overhead of maintaining state across execution cycles.
Watermarking triggers using ID or timestamp fields
Watermarking functions as a persistent state marker. The system records the highest value of a specific field, such as an updated_at timestamp or an auto-incrementing integer ID, to serve as the starting point for the next poll.
In a workflow using a customer relationship management platform like Salesforce, the engine queries for records where the timestamp is greater than the stored watermark.
Only new or modified entries trigger the logic because of this limit. This prevents the redundant consumption of task quotas on data that has already been synchronized.
If the sync fails, the watermark remains at the last successful record's value, allowing the system to resume from the exact point of interruption without manual intervention.
Checkpointing stream state for high-volume data
Checkpointing involves the periodic persistence of the entire stream state to a durable storage layer. This allows the system to recover from a specific offset in the event of a cluster failure.
This pattern is necessary for high-throughput environments where losing the current position in the data stream would result in missing thousands of events.
Unlike simple watermarking, checkpointing often tracks multiple partitions of data simultaneously, requiring more complex logic to manage the commit of these offsets.
| Pattern | Data Integrity | Setup Complexity | Infrastructure Cost |
|---|---|---|---|
| Watermarking | High | Medium | Low |
| Checkpointing | High | High | Medium |
| Time-shifting | Low | Low | Low |
The choice of pattern dictates the long-term stability of the integration, as a mismatch between data volume and tracking logic leads to either silent data loss or runaway execution costs.
Time-shifting to ignore records older than the deployment date
By explicitly instructing the automation engine to ignore any record created before the workflow's activation timestamp, time-shifting applies a hard filter to the initial query.
This approach effectively zeroes out the historical debt of the source system. Consequently, the very first run only processes "day zero" events rather than attempting to ingest years of legacy logs.
While this is the most cost-effective method for preserving a monthly task budget, it creates a permanent data gap between the source and destination.
If a record is updated but its creation date remains outside the shift window, the workflow will never observe the change, leading to a state of permanent inconsistency between the two systems.
Worth checking against a plan that does not meter every step: one credit covers a whole run on Activepieces.
Establish a reliable state with Activepieces
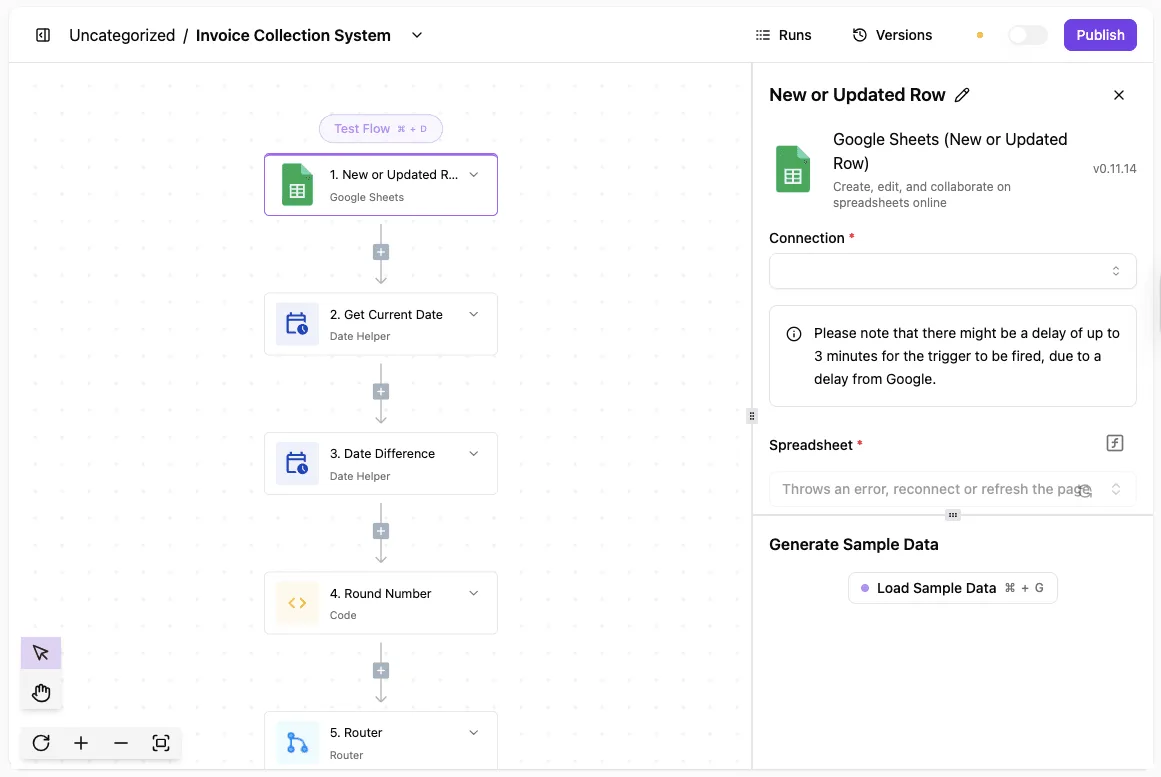
Activepieces manages state by indexing the current dataset as a baseline before the first polling cycle initiates, a capability built into an MIT-licensed core that ensures the underlying logic remains transparent and auditable.
This mechanism ensures that the automation engine treats existing records as a known state rather than a queue of new events, preventing the budget exhaustion that occurs when a system attempts to synchronize years of legacy data upon activation.

Preventing floods of historical data
Activepieces prevents historical data floods by executing a dry-run fetch that populates the internal cursor without triggering downstream actions, drawing from a library of 738 integrations where roughly 60% are community-contributed to ensure broad coverage of source behaviors, which means users benefit from a vast ecosystem of connectors maintained by a diverse group of developers.
When a user connects a source like GitHub, a web-based platform for version control, the trigger component queries the API for the most recent ID or timestamp.
This value is written to the workflow’s persistent storage, creating a boundary that effectively ignores all preceding entries.
Activepieces uses Git Sync and Release Management to promote these versioned flows from test to production, ensuring that the logic governing historical data boundaries is reviewed as code rather than being an accident of clicking "publish." Organizations like MoneyGram and FundingSocieties run these environments to maintain strict control over how state-handling logic is audited and deployed across their infrastructure.
Because the flow logic only evaluates records with a higher sequence number than the stored cursor, the initial activation consumes zero task runs regardless of the source's total record count.
The following data illustrates the primary friction points encountered during the deployment phase of new automations.
Most failures originate from state mismanagement during the first connection: initial sync misconfiguration accounts for 85% of issues, while all other runtime errors make up 15%, meaning developers should prioritize debugging the handshake process over investigating later execution steps.
By isolating the initial sync from the execution engine, the system remains stable even when connecting to high-volume databases.
Choosing read from now vs read from start
The 'Read from Now' toggle allows the user to explicitly define whether the state machine begins at the current time or at the beginning of the available data stream.
Selecting 'Read from Now' instructs the trigger to perform a metadata check to set the cursor at the latest entry.
Selecting 'Read from Start' bypasses the initial state-setting and forces the engine to iterate through every historical record available via the API. Confirming the selection locks the behavior into the workflow metadata. This prevents subsequent restarts from re-triggering the historical sync.
Managing state persistence across workflow iterations
State persistence is handled through a dedicated key-store that survives both manual restarts and platform updates.
When a workflow completes a successful run, the trigger updates the stored cursor only after the final step has executed without error. If a failure occurs mid-stream, the state remains at the previous successful checkpoint.
The next polling cycle then re-fetches the interrupted record for a retry. This transactional approach to state means that data is never skipped due to transient network errors and never duplicated due to a lack of memory between runs.
Monday morning checklist for new trigger deployments
A successful deployment requires explicit constraints on the initial data fetch to prevent a legacy migration from consuming the entire monthly execution budget.
Without these guardrails, the system treats every historical record as a new event, triggering downstream actions for data that is no longer relevant to current operations.
Audit the source system for record volume
Predicting the initial load requires calculating the specific lookback window of the source API to determine how many records will enter the pipeline upon activation.
If you connect Shopify, the platform enforces a 30-day maximum window, meaning any order updated within the last month will trigger a run regardless of its original creation date.

Similarly, Breeze Prospecting utilizes a 30-day window, so a new deployment will immediately process leads that may have been qualified weeks ago.
For high-volume marketing data, HubSpot attribution allows for a 90-day lookback, which can result in three months of click data hitting your budget in a single burst.
To mitigate this, many teams implement a Retargeting Guardrail of 7 days, so the automation only engages with users who have shown recent intent.
Testing automation triggers with a single record
Testing the integration logic with a single record ensures that the transformation and destination schemas are compatible without risking a mass failure event.
This step validates the state machine's ability to transition from "Idle" to "Processing" and finally to "Success" for one unit of work. Use this checklist to verify the scale of the deployment:
- Airbyte recommends verifying the 'Lookback Window' (e.g., Shopify 30-day max), as this defines the chronological boundary of the first fetch.
- Check the API Page Size (e.g., 50 records per call); this determines how many records are bundled into a single network request, so adjusting this value directly impacts your application's latency and throughput.
- Estimate total API calls (e.g., 52,000); this allows you to predict if you will hit rate limits before the sync completes.
This validation confirms that the webhook or polling listener is correctly mapped to the expected data fields.
Checking the watermark timestamp before going live
The watermark acts as the cursor for the next execution. It restricts the system to records modified after the last successful run.
If this timestamp is null or set to a historical default like January 1, 1970, the system will attempt to sync the entire history of the source.
Manually setting the watermark to the current UTC time ensures the automation ignores the past and only acts on future events. Once this state is persisted, the trigger can be moved to a production status with zero risk of a budget-exhausting backfill.
Frequently asked questions about trigger data handling
How do triggers handle records updated after the first run?
Triggers monitor specific state changes in a source system. A record updated after the initial sync will only re-fire if the update modifies the specific field the trigger watches.
In a system like Salesforce, a customer relationship management platform, a trigger set to watch "New Leads" will ignore changes to existing leads, whereas a "Modified Record" trigger will capture every subsequent edit.

If the automation logic requires processing both new entries and later changes, the workflow must be configured as a multi-state machine that checks the record ID against a persistent database.
Can i manually reset a trigger to re-process old data?
Manually resetting a trigger requires clearing the stored cursor or "high-water mark" in the automation platform's state memory.
Once this value is deleted, the next execution cycles back to the earliest available record allowed by the API's retention policy.
This action forces the system to treat every historical entry as a new event, which can lead to duplicate entries in the destination unless the downstream logic includes an upsert step.
What happens if the first run fails halfway through?
If the first run fails due to a timeout or rate limit, the trigger state typically defaults to the last successfully processed record ID.
This ensures that the next execution attempt resumes from the point of failure rather than restarting the entire backfill from the beginning.
Without this checkpointing behavior, a large data sync would enter an infinite loop of partial processing and failure, eventually exhausting the entire task budget.
Do webhooks ever have access to historical data?
Webhooks are push-based notifications and do not have inherent access to historical data. They only transmit information about events occurring in real-time.
Unlike polling triggers that query a database for past entries, a webhook listener only sees what the source system sends at the moment of the trigger.
To include historical context, the workflow must take the ID provided by the webhook and use it to perform a "Get Record" lookup in the source API.
Related reading
References
Running the numbers
See what the same workload costs here.
Free forever plan, and every paid plan self-hosts at no extra cost.
See pricing Talk to sales