Vast AI Workflow: How to Rent a GPU (2026 Guide)
Nov 15, 202614 min read
If you want the fastest path on Vast.ai, it is six steps: search offers, rent an instance, connect, run the job, copy output out (or hand the results to a workflow tool such as Activepieces if something downstream needs them), destroy the instance.
The Vast AI Workflow and the Fastest Path
The six-step loop in one paragraph
You rent GPUs by the hour on Vast.ai, a marketplace where hosts list them. The sequence below is the whole workflow, and the steps must happen in this order:
- Search offers.
- Rent an instance.
- Connect.
- Run the job.
- Copy output out.
- Destroy the instance.
Skip step 6 and you pay for an idle GPU, because billing continues until it. Step 5 must come before step 6 because destroying the instance deletes its disk.
On-demand, interruptible and reserved instances compared
| Billing | Interruption risk | Best use | |
|---|---|---|---|
| On-demand | Fixed hourly rate while running | None from other renters | Test runs, anything you cannot restart |
| Interruptible | Bid-based rate, usually lower | Stopped when a higher bid arrives | Checkpointed training, batch jobs |
| Reserved | Prepaid commitment at a reduced rate | None from other renters | Steady, long-running workloads |
Because H100 prices have fallen at every step, short test rentals are cheap.
Virtualized records $8 per GPU-hour in April 2023, $5.90 in October 2023, $4.20 in April 2024 and $3.20 in October 2024, which means GPU compute had transitioned from a premium service to a commodity market within thirty months.
It then records $2.85 in April 2025 and $2.75 in October 2025, indicating that GPU-hour pricing fell for more than two years before beginning to flatten, making long-term cost projections uncertain. That's a drop of about two-thirds in thirty months.
The last step was only ten cents, so the fall is flattening and you shouldn't wait for it to continue.
Set the on-demand rates side by side and the marketplace discount is visible too. aicalculators.org lists on-demand H100s at $2.20 per hour on Vast.ai, against $3.67 on Azure, $3.76 on Google Cloud and $4.14 on AWS.


That puts Vast.ai about 47% below AWS, so a one-hour trial costs roughly $2.20 and a bad configuration is a cheap lesson.
What you need before you start
You need an account with credit loaded, an SSH key registered, and a container image that runs your job. You also need to know how much disk the job needs, because the rental fixes disk size and a wrong guess means starting over.
Know which output files you'll copy out in step 5.
Interactive work involves many manual decisions that need an operator's care. The next section takes the steps one at a time.
This takes minutes, not a project: automate it in Activepieces free.
Account, Credit and Your First Rented Instance
Before you click rent, you need credit on the Billing page and an SSH key on your account.
You also need a template, a launch mode, an offer that passes your filters, and a disk size set on the rental form.
Adding Vast AI credit and an SSH key
Fund the account first, because an offer won't launch against an empty balance. Then paste the public half of your SSH key into the account settings.
If the key is missing when the instance starts, the machine boots and bills you while you have no way to log in.
Choosing a Vast AI template and launch mode
Some images won't run on older drivers, so the template comes before the hardware. It decides the software image: which framework, which CUDA version, which tools come preinstalled.
If you plan to script anything, choose SSH, since you can still run a notebook from inside it. The launch mode decides how you reach the machine: SSH gives you a plain terminal, while a Jupyter-style mode gives you a browser notebook.
Filter offers and set disk size before renting
Narrow the offer list on five fields:
- GPU model
- VRAM
- Reliability score
- Price
- Location
A model that doesn't fit in memory won't run at any price, which is why VRAM is the filter that rules machines out.
Location affects the latency of your SSH session and how long your uploads take.
Then set the disk size on the rental form itself. On most marketplaces the disk size is set when you create the instance, so a wrong guess means destroying the instance and renting again, and anything you downloaded is gone.
Size it for the model weights plus your datasets plus working space, and round up.
Look at the agents list below, with its "Blog Author Enricher" and "SEO blog writer" cards, and you see the opposite kind of setup.
Once the instance is running, the next job is connecting to it and confirming the GPU is visible.
Connecting, Running a Job and Saving Output
Press the instance's Open button for a Jupyter session in the browser, or copy its SSH command for a terminal, and run nvidia-smi before anything else. If the GPU isn't listed, stop and fix that first.
Connect with Jupyter or SSH
When you only need a notebook or a quick check, Jupyter does it: the button opens a session with a file browser and a terminal tab. SSH suits anything long-running.
Copy the ready-made ssh command from the instance card, with the host and port assigned to that rental. Paste it as given, because the port differs per instance and a copied command from an earlier rental will fail or reach the wrong machine.
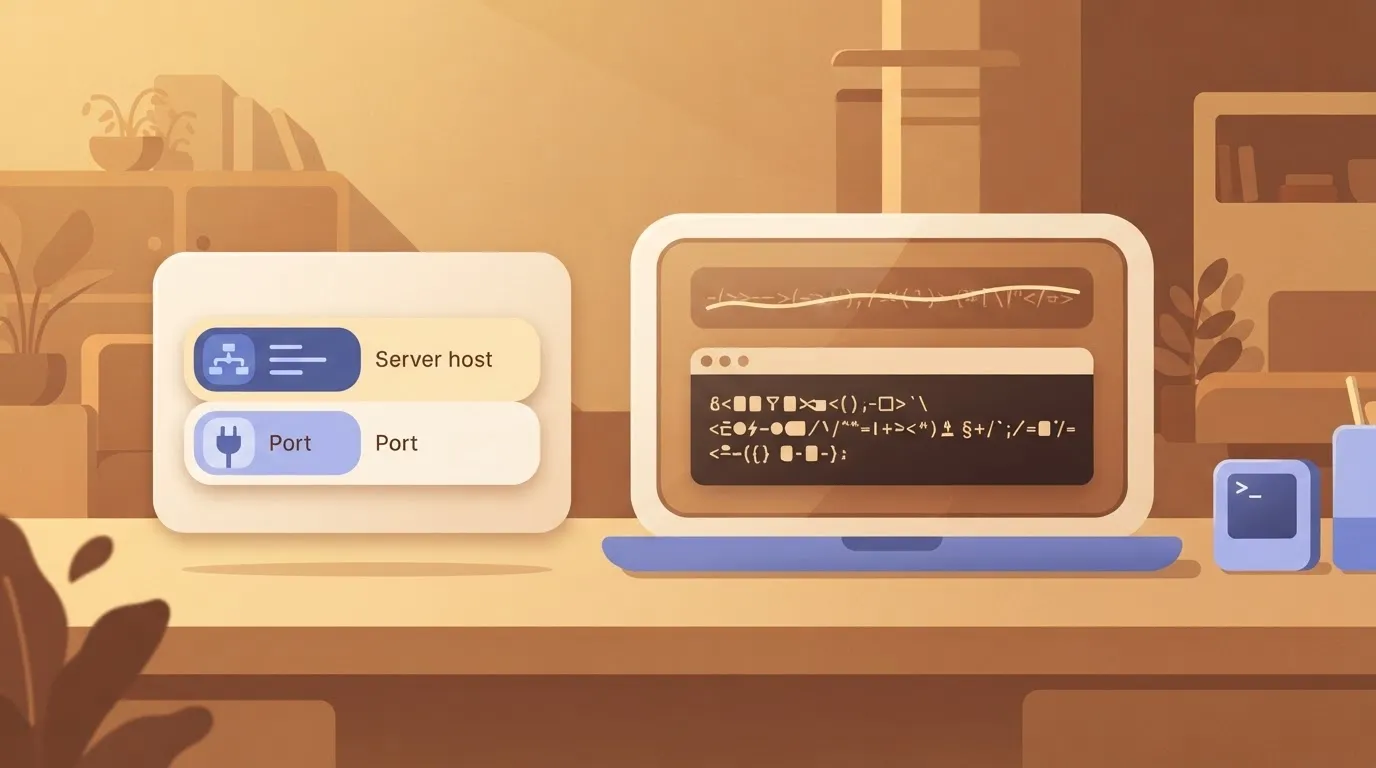
Start long jobs inside tmux or screen, so a dropped connection doesn't kill training.
Copy results off before you destroy
Destroying an instance deletes its disk. Whatever sits only on that disk is gone once you confirm, and there's no recovery step. Pull results first, using one of three routes:
scp -P <port> -r root@<host>:/workspace/output ./outputfor a single directory you'll fetch once.rsync -avz -e "ssh -p <port>" root@<host>:/workspace/output/ ./output/for repeated pulls, since a rerun after an interruption transfers only what is missing.- Cloud sync from the instance to a storage bucket you control, which suits large outputs you'd rather not route through your own connection.
Files are not the only thing that outlives a rental. Credentials are the second.
To close that gap automatically, use a flow that fires on an instance-stopped event and calls a token-revocation endpoint.
The run trace below shows one doing so: the stop trigger, then a POST to Square's OAuth revoke URL (Square's the payments provider whose token the job had been using), with both steps passing and the output JSON recorded.
To make the loop repeatable, use the commands; every console action above has one.
- Find a machine with
vastai search offers, filtered on the GPU and price you want. - Rent it with
vastai create instance <offer_id> --image <image>. - Read the connection details with
vastai show instances, orvastai ssh-url <instance_id>for the SSH address. - Pull results with
vastai copy, or thescpandrsynccommands above. - Remove the rental with
vastai destroy instance <instance_id>.
Never run step 5 before step 4 has been verified by listing the files locally, or you'll be testing step 5 against an unknown input state.
You can follow the rest of this with the builder open. Start free, no card.
Vast AI Limits and Errors
When a Vast AI job fails, the cause is usually one of a few choices made at rental time: the image, the disk size, the instance type and the SSH key.
The table below lays out each symptom with its likely cause and fix, and marks whether Vast's documentation states the behavior or you infer it from experience.
Treat the "Partly" and "Not directly" rows as working conclusions to verify against your own instance logs.
| Symptom | Cause | Fix | Docs state it? |
|---|---|---|---|
| Stuck loading or image pull failure | Host has a slow or failing pull, or the image name or tag is wrong | Check the instance log, then destroy and rent a different host | Partly |
| Out of disk | Disk was sized at rental and can't be grown in place | Recreate with more disk and copy data out first | Yes |
| Interrupted instance | Interruptible rental outbid, or the host took the machine back | Checkpoint to external storage; use on-demand for long runs | Yes |
| SSH refused | Key was not attached before launch, or the instance is still loading | Add the key to your account, then recreate if needed | Partly |
| CUDA/driver mismatch | Image's CUDA version is newer than the host driver supports | Filter hosts by CUDA version or pick an older image tag | Partly |
| Charges while stopped | Storage stays reserved for a stopped instance | Destroy it once data is copied off | Yes |
How to fix common Vast AI errors
Stalled Vast AI image loads and bad tags
Read the instance log before doing anything else. A stalled image pull and a bad image tag look identical on the dashboard, which shows only a status label, and only the log tells you which one it's.
If the pull is the problem, waiting rarely helps, so destroy the instance and rent from another host.
Outbid rentals and full disks
When another bid outranks yours, an interruptible rental can be taken from you. Anything not written to storage outside the instance is at risk, so write checkpoints somewhere else on a schedule.
Disk is also fixed when you rent, so a full disk means recreating the instance, not resizing it.
Vast AI SSH connection refused errors
When SSH refuses you, one of two causes is usually behind it: the instance hasn't finished loading, or your public key was not on the account when it launched.
Rule out the first by checking the log. If the key was missing, add it and recreate the instance, because a key added later may not reach one that already started.
Vast AI charges for stopped instances
Stop an instance and compute pauses, but its disk isn't released. Storage keeps billing until you destroy the instance, so a forgotten stopped instance still costs money. Copy your files off, confirm them locally, then destroy it.
Automating Vast AI Jobs with Activepieces
Destroying the instance is the step people forget on the tenth run, not the first.
Describe that cleanup in the built-in chat of Activepieces, whose core is MIT-licensed, and it publishes a live flow in your account, the same flow a builder would have assembled by hand.
It's governed like any flow someone built manually, with RBAC, audit logs and run traces, so nobody needs hiring to write it.
Nothing here is a one-click integration: none of the 750 integrations counted in the open source monorepo is a dedicated Vast.ai connector.
What Activepieces does have is a generic HTTP step, and Vast.ai exposes a REST API, so the same calls you made by hand in the console can run as a flow.
If you rent a GPU once a quarter, skip it. If you launch the same job every week, the flow replaces the part of the checklist that depends on your memory.
It always runs in one shape: a trigger starts it, an HTTP step calls the Vast.ai API, and the result branches.
It traces that path from the trigger on the left to the two outcomes on the right, an alert message and the destruction of an idle instance.
Destroy idle instances on a schedule
Use a schedule trigger, such as every evening, and add an HTTP step that asks the Vast.ai API for your current instances. Authenticate it with your API key stored as a connection rather than pasted into the step.
A branch step then checks each instance against the rule you chose, for example that it has no job attached, and a second HTTP step sends the destroy request for those that match.
When an instance is destroyed that shouldn't have been, you open the run, read the exact response the list call returned, and see which condition matched.
Every run leaves a trace of each step's input and output. That's a record you can debug, which the console's billing page is not.
Flows are unlimited on every plan, including free, so this destroy flow and the alert flow below can sit side by side without costing you a plan upgrade.
Alert when an instance runs too long
Nothing is destroyed in this one. It uses the same list call, compares how long each instance has been running with a limit you set, and sends a message to email or a chat channel when one exceeds it.
Use this where a long run may be legitimate, such as training that's meant to take days, and deletion would throw away work.
The alert tells a person to decide, and the run trace shows what the API reported when the message fired.
Rent one cheap on-demand instance, run the flow's destroy step against it, and open the run trace to confirm the instance is gone from your account. Do this before you trust the flow with anything expensive.
Frequently asked questions
Is Vast.AI cheaper than AWS for GPU work?
Usually yes on the hourly rate, though not always once you count what you rebuild when a host drops.
Read the marketplace side as a spread, not a quote, because every host sets its own price and the listing you see today may be gone tomorrow.
Interrupted or short jobs that checkpoint often come out well ahead on the marketplace. A long job with no checkpoints can erase the saving with one lost host.
Can I stop an instance and resume without losing data?
Your disk survives a stop, but your place on the GPU doesn't. A stopped instance keeps its storage on the host, and that storage keeps billing, because the host is holding the space for you.
The GPU is released, so when you try to resume, someone else may have rented it and you wait or start over elsewhere. Copy anything you can't afford to lose to storage you control before you stop.
Does Vast.AI bill by the second?
Yes, compute is metered continuously, so a short test costs a short amount. The charges that surprise people are the ones outside the compute meter: storage while stopped, and bandwidth, which hosts price individually.
Read the bandwidth rates on the listing before you pull a large dataset or push large checkpoints.
Is it safe to run private data on a Vast.AI host?
Not by default. The host operator controls the machine your container runs on, and hosts differ in how vetted they are. Treat an ordinary host as untrusted: use public or synthetic data, keep credentials out of the image, and rotate any key you did load.
For regulated or confidential data, restrict your search to the verified datacenter tier and read what isolation that tier states. If its terms don't cover your data, the marketplace is the wrong place for that job.
Related reading
References
Build it
Set this up in minutes.
No code required. Connect your accounts, and Activepieces runs it from there.
Start free Talk to sales