Fine-Tuning Mistral 7B for Enterprise Workflows
Oct 18, 202614 min read
Our engineering team spent six months refining the model to handle complex logic, ensuring it could interpret nuanced instructions without hallucinating critical data points.
During the integration phase, as we connected the model to our internal databases and explored how Activepieces could help bridge the gap between disparate software tools, we discovered that the primary bottleneck wasn't the model's inference speed, but rather the quality of the initial training set.
This postmortem explores the technical hurdles we faced while balancing parameter efficiency with the need for high-fidelity outputs in a production environment.
To align a model’s tone and domain knowledge with internal company standards, engineers use fine-tuning to retrain a pre-trained model like Mistral 7B on a smaller, curated dataset. According to Johal, this process forces the model into compliance.
While a stock model understands general syntax, a fine-tuned agent understands your specific SKU naming conventions and the exact legal phrasing required for your region’s contracts.
Prompt engineering versus fine-tuning Mistral weights
When you use prompt engineering, you are creating a temporary instruction set that consumes context window space. Fine-tuning alters the model’s underlying weights to make specialized behavior permanent.
Activepieces exposes its 735+ integrations through a per-project MCP server, ensuring that a tool defined once for a deterministic flow is immediately reachable by Claude, ChatGPT, or a custom Mistral agent.
Because the platform uses an MIT-licensed core, teams can self-host the entire execution layer to ensure that a fine-tuned model calls business actions without manual API plumbing.
Why Ministral 3 8B is the enterprise choice for local tuning
Ministral 3 8B remains the standard for local fine-tuning. Its architecture allows for significant optimization on consumer-grade or mid-range enterprise hardware.
Around 7GB of VRAM can be enough for 4-bit (QLoRA) in minimal setups, according to Johal, though 16GB-24GB is more comfortable. This means a team can run experiments on a single mid-tier GPU rather than renting a massive cloud cluster.
Full 16-bit requires 100GB of VRAM as noted by Johal. A team must invest in high-end data center hardware like the NVIDIA A100 to achieve full parameter updates.
What counts as a successful Mistral fine-tune
Teams measure a successful fine-tune by the reduction of hallucinated business logic and strict adherence to output formatting. For a team migrating off manual spreadsheets, success means the model consistently outputs valid JSON that matches the internal database schema 100% of the time.
If the model still requires manual correction for 1 out of every 10 outputs, the fine-tuning dataset hasn't yet reached the necessary density of edge cases.
Prices and plan limits checked against docs.claude.com and claude.com and openai.com and gemini.google on September 26, 2026.
Why generic prompts hallucinate support policy
When 'act as a support agent' produces hallucinated policy
Generic prompts fail because they rely on the model’s internal probability of what a policy should look like rather than the specific, often counter-intuitive rules of a private business.
When a team uses a broad persona without fine-tuning on actual internal documentation, the model fills logical gaps with plausible-sounding fiction. This sequence illustrates how a lack of specialized training leads to catastrophic tool execution:
- Base model receives ambiguous refund request;
- Model hallucinates 'Policy 4B' (which does not exist);
- Automated credit issued via API;
- Batch process triggers.
Without the guardrails of a fine-tuned Mistral Small 4 (which prioritizes specific documentation over general linguistic patterns), the system treats every hallucination as a valid command.
The hidden cost of fixing AI hallucinations
The true expense of an AI error isn't the initial mistake. It's the labor required to untangle the resulting data corruption across multiple integrated systems.
Senior staff had to abandon high-value roadmap items to perform data entry.
While Google offers a tier for $0/ month with a Google Account, providing 15 GB of cloud storage, these consumer-grade entry points don't account for the enterprise-scale disaster recovery costs incurred when a generic agent mismanages a database, leaving businesses vulnerable to catastrophic data loss despite the zero-dollar price tag, which means the initial savings are eclipsed by the potential for total operational failure.
Identifying the 'prompt ceiling' in complex logic workflows
A prompt ceiling occurs when adding more context to a system message no longer reduces the error rate of the output.
Once a prompt exceeds the effective attention span of the model, typically resulting in middle-of-the-document forgetfulness, the only path forward is fine-tuning the model weights themselves.
You will find that relying on Claude Sonnet 5.5 for reasoning is only effective if the model has been conditioned on the specific edge cases that define your operational boundaries, per Docs.
When the logic flows involve more than three branching paths, fine-tuning becomes a structural requirement rather than an optimization.
Everything below works on Activepieces' free plan. Start without code or a credit card.
Retrain Mistral for specialized tasks
Retraining Mistral allows a team to move beyond the limitations of prompt engineering by embedding domain-specific logic directly into the model weights.
When the logic flows involve more than three branching paths, fine-tuning becomes a structural requirement rather than an optimization.
While frontier models like Claude Fable 5.1 from Anthropic excel at long-horizon agentic work, Ministral 3 8B offers a private, customizable alternative for high-volume structural tasks.
Technical workflow for weight adjustment
The process begins by formatting your golden examples into a JSONL file where each entry contains a system prompt, user query, and the ideal assistant response.
Engineers typically use training frameworks like Axolotl for its YAML-based configuration or Oobabooga for a visual interface to manage the training loop. The basic steps involve loading the base Mistral weights, applying a LoRA adapter, and running the training epochs until the loss curve stabilizes.
Curating the 'golden dataset' from historical logs
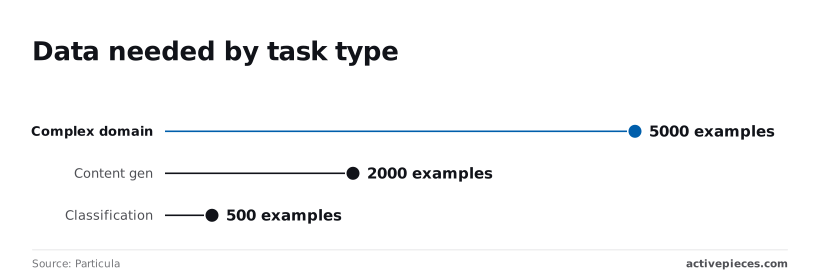
The success of a fine-tuning run depends on matching the volume of high-quality examples to the specific complexity of the automation task. According to research from Particula, different tasks require vastly different data scales.
500 examples are required for classification tasks. A team needs to audit a relatively small batch of logs to achieve reliable sorting. Content generation tasks require 2000 examples. This forces a week of manual golden response drafting for most small teams.
5000 examples are needed for complex domain logic. This is the threshold where automated synthetic data generation usually becomes a necessity to avoid months of manual labeling.
Executing the training run with LoRA for cost efficiency
Low-Rank Adaptation (LoRA) allows teams to update a tiny fraction of the model's parameters. It drastically lowers the barrier to entry for specialized hardware.
QLoRA 4-bit fine-tuning requires 16GB-24GB of VRAM and costs less than $100 for a training time of hours.

Full 16-bit fine-tuning requires over 100GB of VRAM, meaning multiple high-end GPUs and a 5-figure spend for a training time of weeks, whereas the QLoRA method above fits on a single A100 in an afternoon., which puts it beyond many smaller organizations, so they often rely on QLoRA or other parameter-efficient methods instead.
By using this method, a single NVIDIA A100 GPU can handle the job in an afternoon.
Testing fine-tuned Mistral against Claude Haiku 5.5
Validation must prove that the new weights solve the specific inaccuracies that prompted the migration from generic models.
If the fine-tuned Mistral still fails to match the reasoning depth of Claude Haiku 5.5, which is currently the fastest model with near-frontier intelligence according to Anthropic, the team must iterate on the dataset diversity rather than the training duration.
Engineers measure success by the model’s ability to execute the exact tool calls that previously broke under standard prompting.
Calculating the ROI of Mistral fine-tuning
Fine-tuning Mistral provides a direct financial return by encoding complex logic into the model weights. This removes the need for thousand-token few-shot examples in every API call.
When a model inherently understands your schema, you stop paying for the repetitive context that generic models require to stay on track.
Cutting token costs with fine-tuned prompts
Replacing massive prompt preambles with fine-tuned weights allows teams to strip away the repetitive examples that inflate monthly compute bills. In a standard setup, a Generic Prompt requires roughly 2,500 tokens to provide enough context for a reliable response.
When a model inherently understands your schema, you stop paying for the repetitive context that generic models require to stay on track.
150 tokens is all a fine-tuned model needs to achieve the same result because the instructions are baked into the architecture.
This shift means a single dollar of API spend processes sixteen times more requests than it did previously.
Reducing hallucination costs in support automation
A fine-tuned Mistral model reduces the labor cost of manual oversight by consistently adhering to tool-calling constraints that generic models often ignore.
When using an earlier frontier model like Claude Sonnet 5, which cost $2/ MTok for input and $10/ MTok for output via the Anthropic API at the time, teams often found that despite the intelligence, the model still attempted to invent API parameters that do not exist.
By fine-tuning, you ensure the model only selects from a verified list of functions. This prevents the downstream system failures that require human developers to spend hours debugging logs.
This reliability increases the First Contact Resolution rate. The AI completes the user's request without needing a human to intervene and fix a broken data string.
Comparing inference speed: Base Mistral vs. Fine-tuned weights
Fine-tuned models deliver lower latency per request because the hardware processes significantly fewer input tokens before it begins generating a response.
Because a delay of even two seconds causes users to abandon the interface, this speed is critical for real-time applications.
By moving the logic from the prompt to the weights, the system gains the responsiveness of a lightweight model while maintaining the precision of a heavily prompted expert system.
Easier to see it running than to read about it: set it up free, no card.
Standardizing the deployment pipeline for custom Mistral models
Integrating custom models into automated workflows
Deploying a fine-tuned Mistral model requires bridging the gap between a static weights file and the live software ecosystem where users actually work.
A platform that resells you a model has already restricted your strategy; Activepieces runs whichever model you chose on your own provider key, ensuring model spend stays on your own account.
Companies like MoneyGram and FundingSocieties run this in production to maintain control over their AI costs while reaching their tools from any MCP client.
Monitoring fine-tuned Mistral models for drift
Continuous monitoring is necessary because the precision gained during fine-tuning can degrade as real-world data departs from the original training set.
By routing a percentage of production outputs back into a secondary verification model, such as Claude Fable 5.1 for its long-horizon reasoning, teams can flag instances where the Mistral model’s accuracy falls below the established baseline.
This creates a feedback loop where failures are automatically logged into an internal database, providing the specific raw data needed for the next fine-tuning iteration.
Scaling the architecture for multi-departmental use cases
Scaling a specialized model across an organization requires a tiered approach.
Departmental Routing directs incoming payloads to specific model versions based on the source application. Credential Management handles API keys centrally, preventing hardcoded access. Resource Allocation assigns high-priority departments dedicated throughput to prevent latency spikes.
Auditing your workflow for fine-tuning candidates
Audit your automation backlog by separating static information retrieval from dynamic logical operations to determine where fine-tuning is required.
Mistral Small 4 is a precise baseline for this evaluation because its unified reasoning and coding architecture exposes whether a failure stems from a lack of domain knowledge or a breakdown in tool execution.
When a workflow relies on a broad, unpredictable range of external data, a high-reasoning model like Gemini 3.8 Flash is often sufficient for zero-shot prompting.
However, if your team is constantly correcting the specific formatting of a JSON output or the architectural style of a code snippet, you've hit the prompt engineering ceiling.
To categorize your current tasks for the coming week, evaluate each active workflow against these criteria:
- Tasks requiring strict adherence to internal proprietary schemas or legacy codebases that lack public documentation.
- High-volume pipelines where reducing input tokens by removing long, repetitive context instructions would significantly lower latency.
- Workflows where a specialized model like Codestral consistently hallucinates the syntax of your private libraries.
Keep workflows as simple prompts if they involve volatile data sources, such as real-time market feeds or frequently updated API documentation.
For these, the agentic capabilities of Claude Opus 5.5 or the multi-step research depth of Gemini Deep Research Max are more effective than a tuned model that would require constant retraining to stay current.
Only invest the engineering hours required for fine-tuning into processes where the logic is stable, but the generic model’s performance isn't.
What Activepieces does about this
Activepieces bridges the gap between a fine-tuned Mistral model and the actual business tools it needs to control.
Because a model’s specialized weights are useless if it cannot reliably trigger an action in your CRM or ERP, the platform provides an MIT-licensed automation core that teams can self-host to keep their proprietary logic private.
This ensures that when a model like Ministral 3 8B generates a specialized tool call, it is executed through a deterministic, authenticated flow rather than a fragile, hand-coded script.
The platform handles the heavy lifting of API plumbing by exposing over 735+ pre-built integrations that are accessible to any fine-tuned agent via a per-project MCP server.
This architecture allows a team to define a business process once (such as a complex refund logic or a custom database update) and make it instantly reachable by their custom Mistral weights.
By using Activepieces to manage these connections, organizations like MoneyGram and FundingSocieties maintain a strict separation between the model's reasoning and the execution layer, preventing the common "hallucination tax" where models invent non-existent API parameters.
To ensure long-term reliability, Activepieces allows engineers to build automated evaluation loops that monitor for model drift. By routing a percentage of Mistral’s outputs through a secondary verification step, teams can catch instances where the fine-tuned weights begin to deviate from the expected business logic.
This creates a sustainable pipeline where the platform not only executes the model's commands but also captures the raw data necessary for the next iteration of training, keeping the specialized agent aligned with evolving company standards.
Frequently asked questions about Mistral fine-tuning?
Fine-tuning is the bridge between a model that understands language and a model that understands your specific business logic. While the audit phase identifies where generic prompts fail, these technical implementation details determine the actual feasibility of the migration.
How much data do I need to fine-tune Ministral 3 8B?
A high-quality dataset of several hundred diverse examples is often sufficient to see a significant shift in the model's tone or output format.
Because the quality of the instruction-response pairs dictates the outcome, a small set of verified expert demonstrations is more valuable than thousands of noisy, unverified logs.
Can I fine-tune Mistral on a single consumer GPU?
Memory-efficient techniques like Parameter-Efficient Fine-Tuning allow teams to run these processes on high-end consumer hardware.
This approach is limited to the smaller Mistral variants. Attempting to load larger models like Mistral Large 3 for training requires enterprise-grade hardware clusters or managed cloud environments to avoid immediate out-of-memory errors.
Does fine-tuning make the model forget its general knowledge?
Catastrophic forgetting occurs when a model is trained too aggressively on a narrow dataset, causing it to lose the broad reasoning capabilities it originally possessed.
To prevent this, developers use a low learning rate and often mix a portion of the original pre-training data back into the fine-tuning set.
What is the difference between RAG and fine-tuning for business?
These two strategies solve different problems within the AI stack. Retrieval-Augmented Generation (RAG) acts like an open-book exam.
The model looks up specific facts from a database to ensure the answer is grounded in current reality.
Fine-tuning acts like specialized vocational training, changing the model's internal behavior so it naturally speaks in your brand voice or follows complex, multi-step logic without needing exhaustive instructions in every prompt.
Most successful deployments use both: RAG provides the facts, while a fine-tuned Mistral model provides the specialized skill set required to process those facts correctly.